Can AI be creative?
What happens in a brain that has a new idea, where recombination stops, and what the measurements of machine creativity show, from AlphaGo's move 37 to GPT-4 on the Alternate Uses Task
What happens in a brain that has a new idea, where recombination stops, and what the measurements of machine creativity show, from AlphaGo's move 37 to GPT-4 on the Alternate Uses Task
AI trading bots and LLM agents tested on six years of Binance data: what machine learning predicts, what trading fees eat, and why LLM backtests lie
A mixture-of-experts layer in PyTorch trained next to dense models: the router, load balancing, dropped tokens, what experts learn, and serving
Linear attention, the delta rule and Gated DeltaNet in PyTorch, a recall test, GPU timings, and why Qwen3-Next and Kimi Linear keep few attention layers
Ship a model so that it runs the same next year: a lock file with hashes, an image pinned by digest, builds that give the same bytes twice, GitHub Actions publishing to GHCR, the image pulled and run without Docker, and the model exported to ONNX for a free in-browser demo.
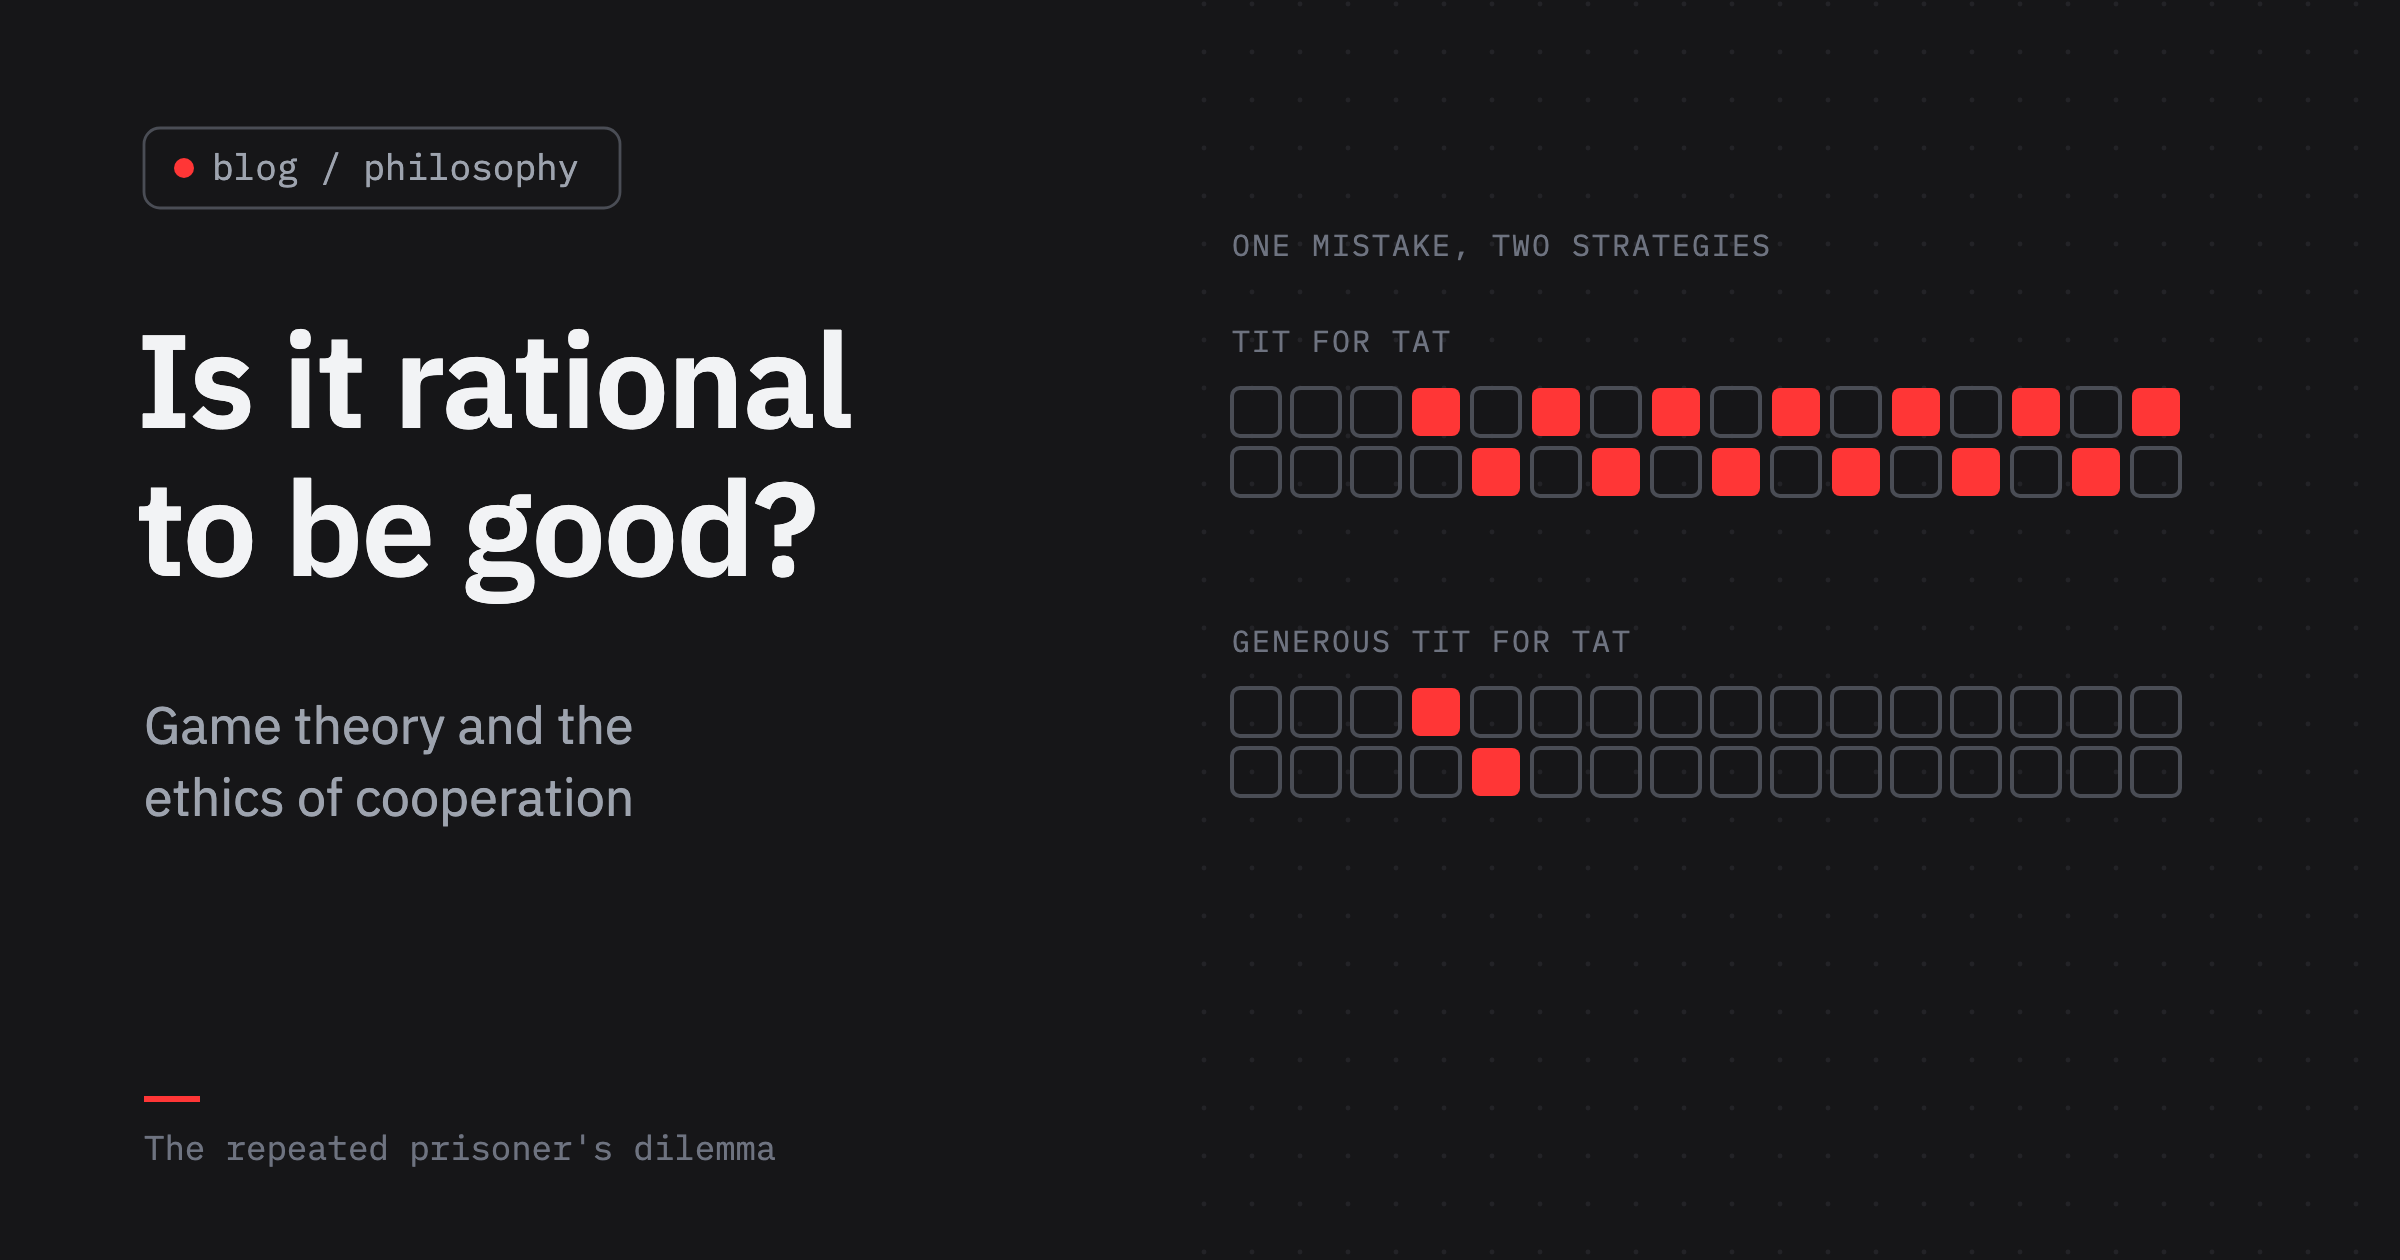
Glaucon's challenge, Hobbes's Foole and Hume's farmers read through the prisoner's dilemma: when cooperation is rational, which virtues the models select, how much forgiveness reason allows, and what game theory cannot settle
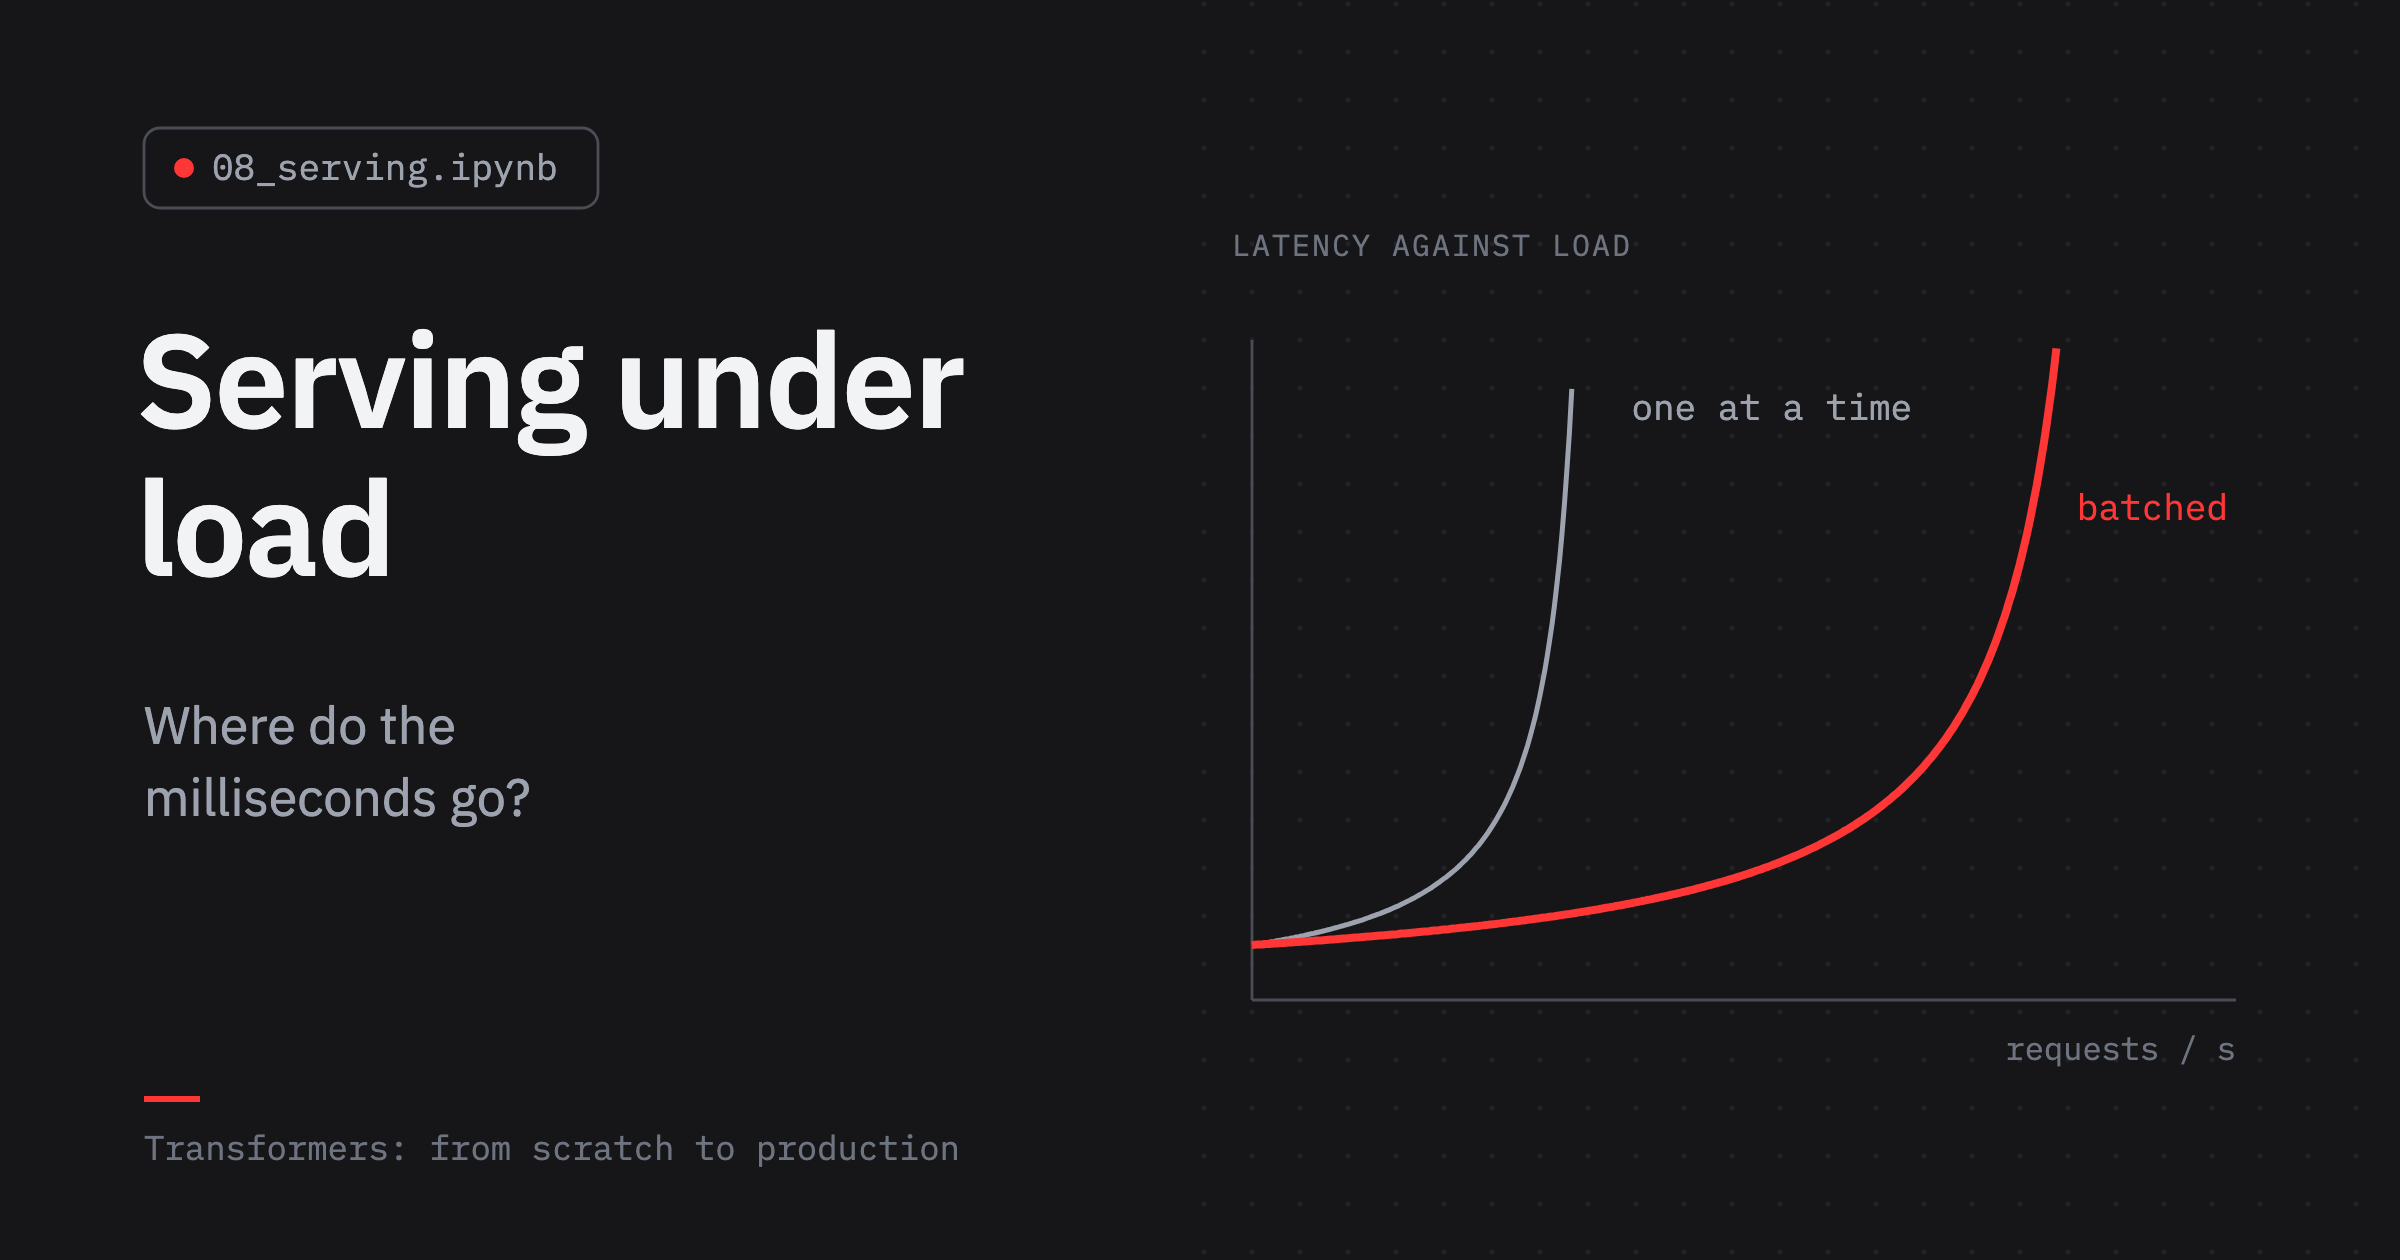
Put a Transformer behind an HTTP API and measure it the way users meet it: a KV cache in beam search, int8 quantization that doesn't pay off, FastAPI and asyncio, open-loop load tests, queueing theory checked against the measurements, dynamic batching, and a Gradio page.
Turn a model from a notebook into a Python package anyone can install: the src layout, pyproject.toml, a command line, four kinds of tests checked by mutation testing, GitHub Actions, and a model card that measures what the model can't do.
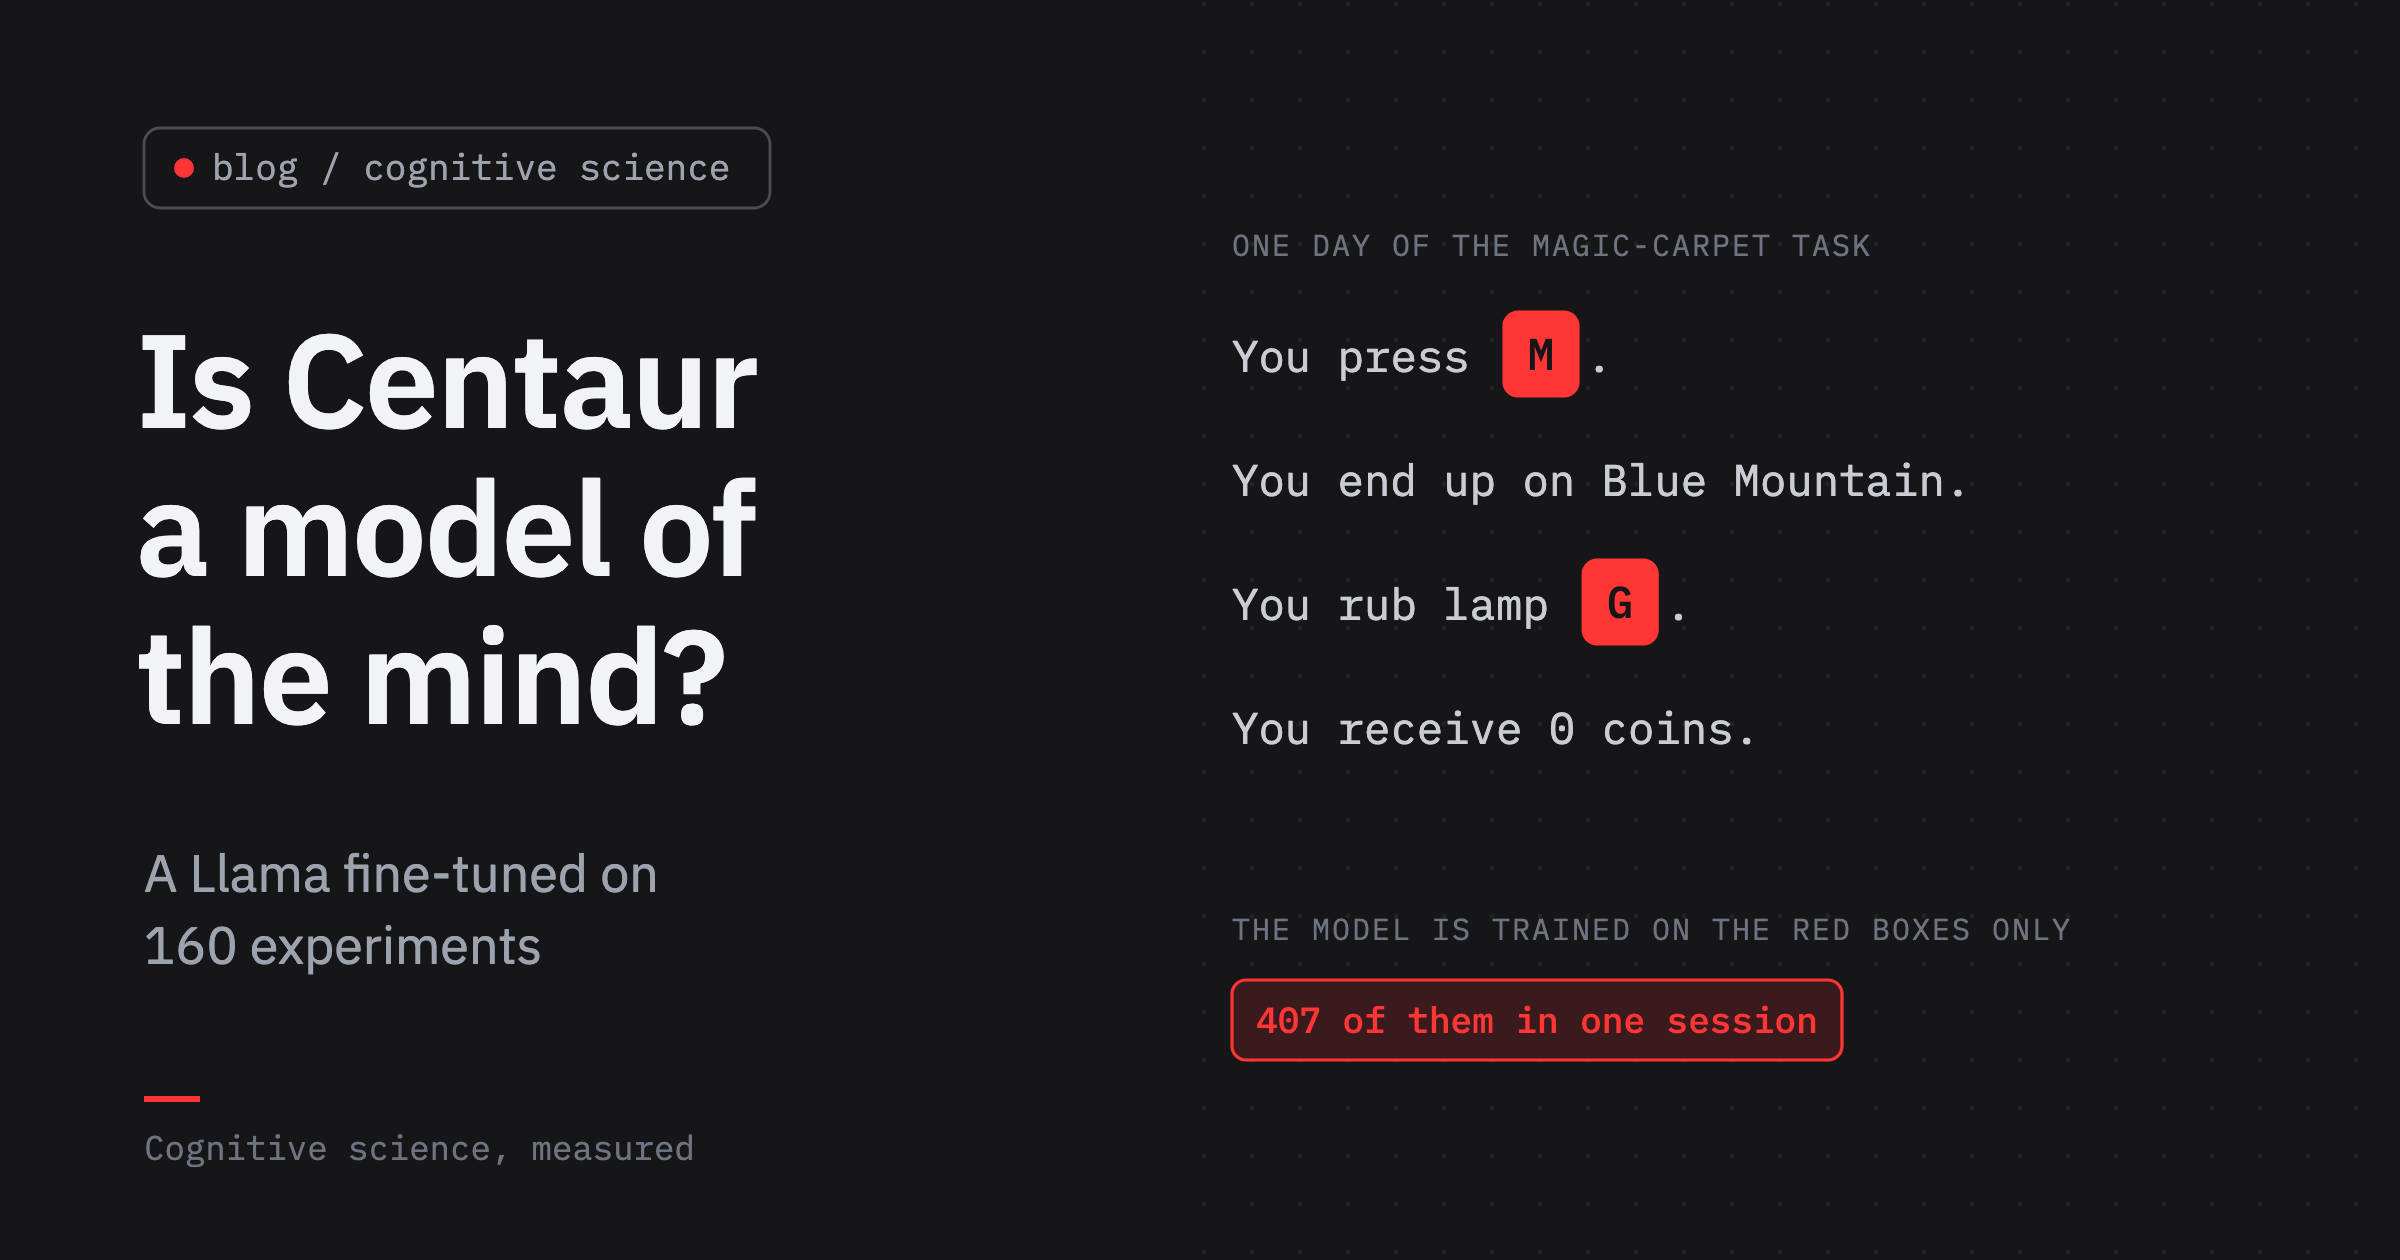
In 1973 Allen Newell asked psychology for one system that performs all its tasks. In 2025 a Llama fine-tuned on 160 experiments was presented as that system. What Centaur predicts, what happens when you take away its instructions, and why its own authors went on to beat it with half a million parameters
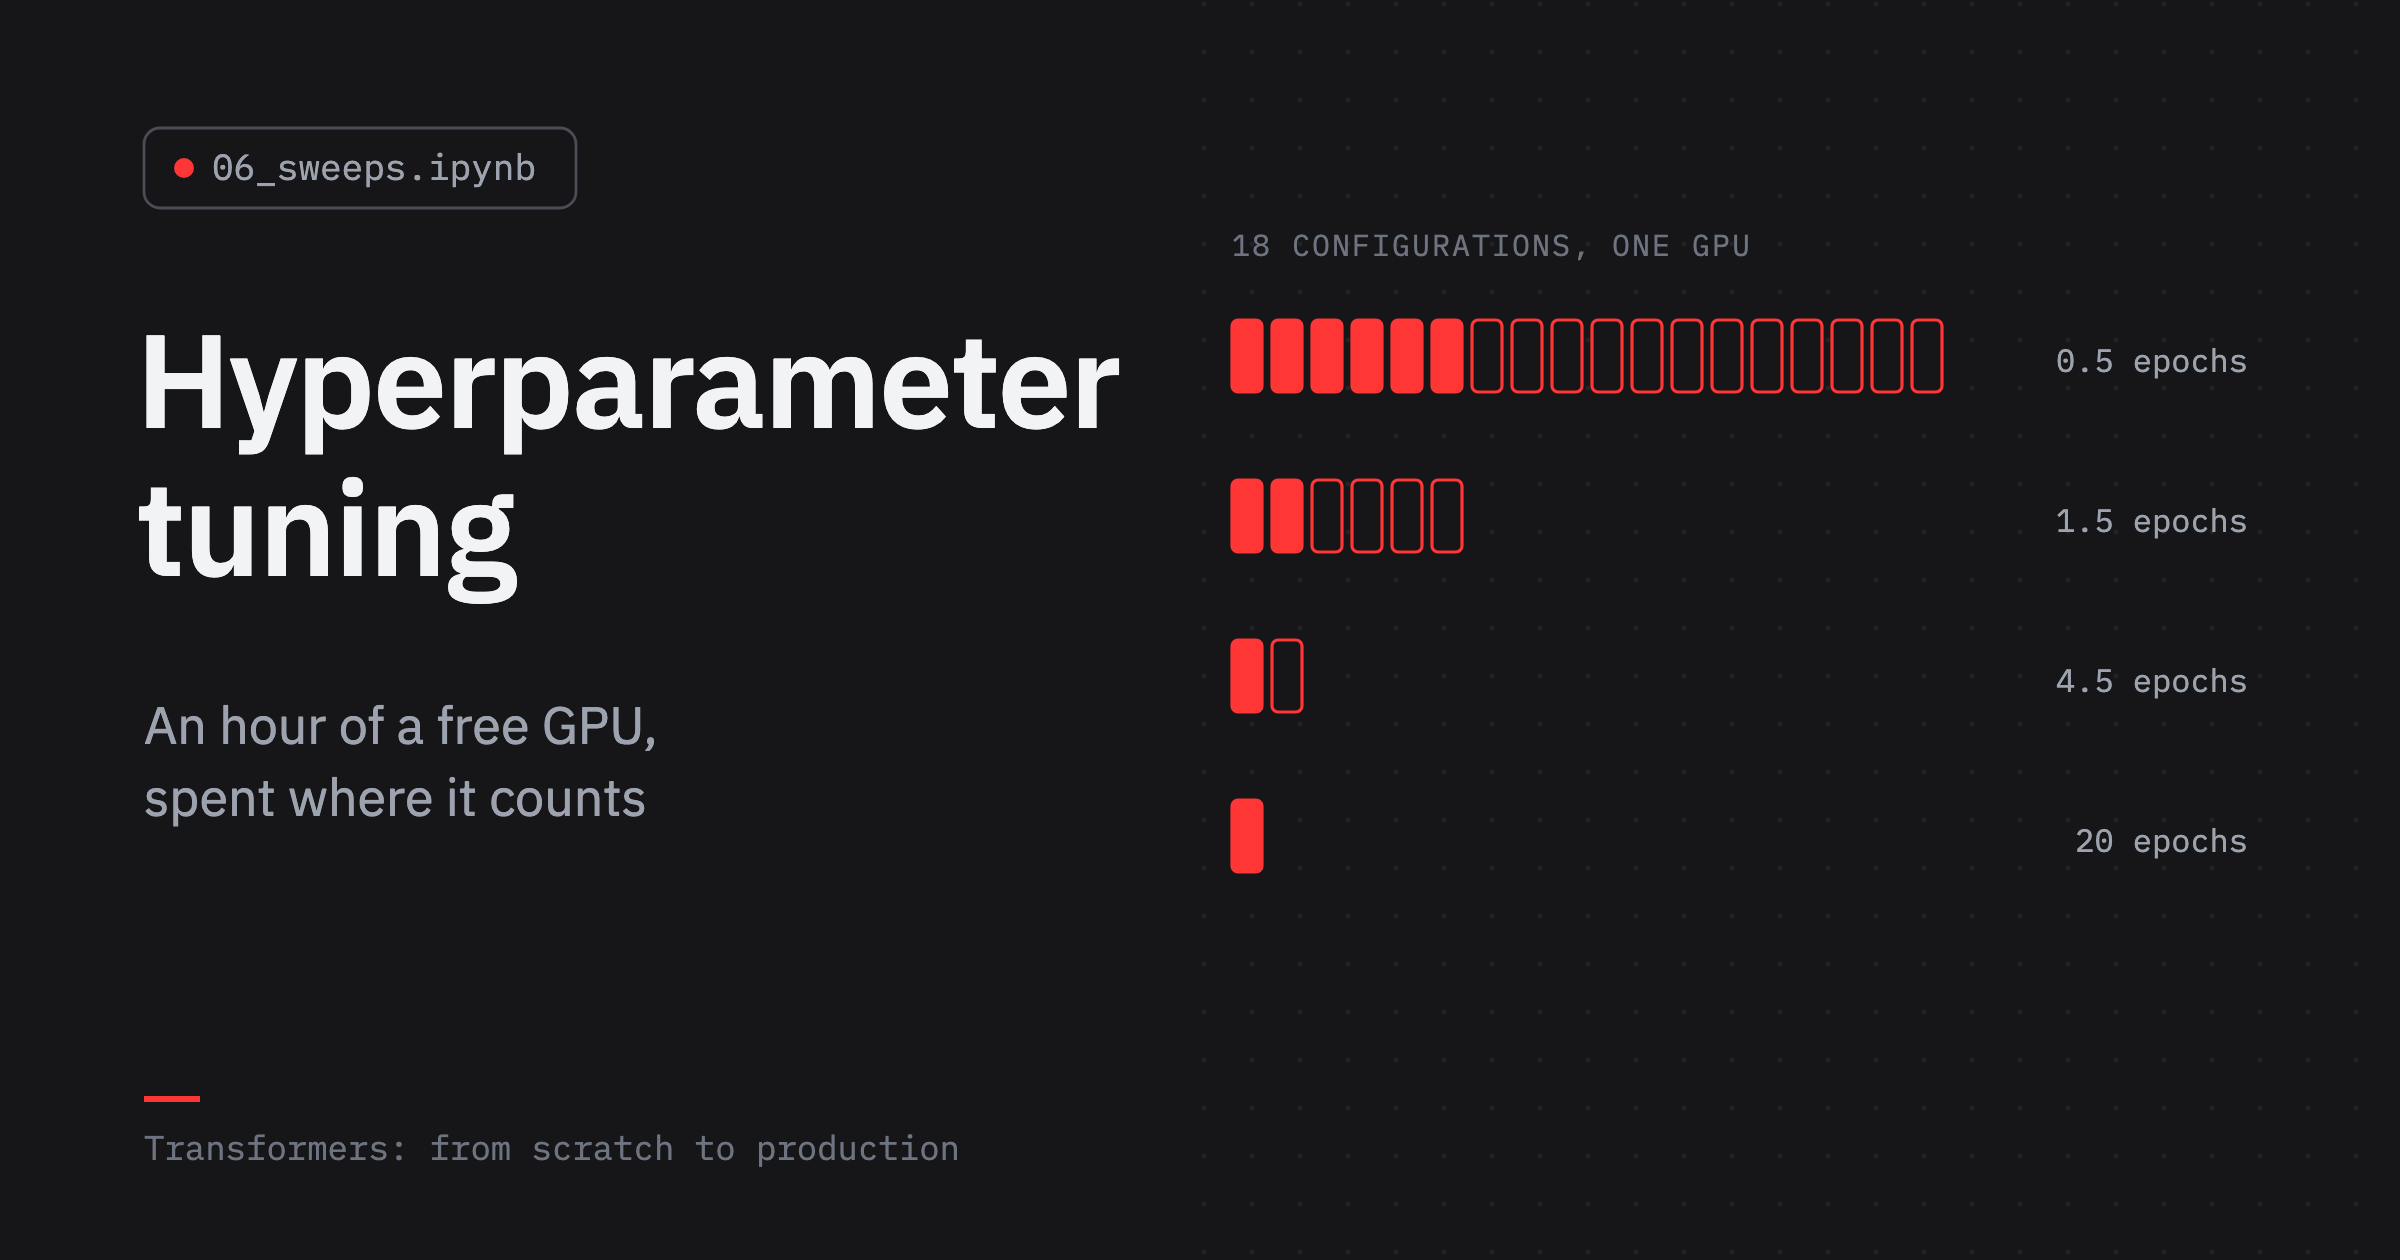
Spend an hour of a free GPU on hyperparameters: experiment tracking with Weights & Biases, a learning-rate range test, random search and successive halving from scratch, and W&B Sweeps with Bayesian optimization.
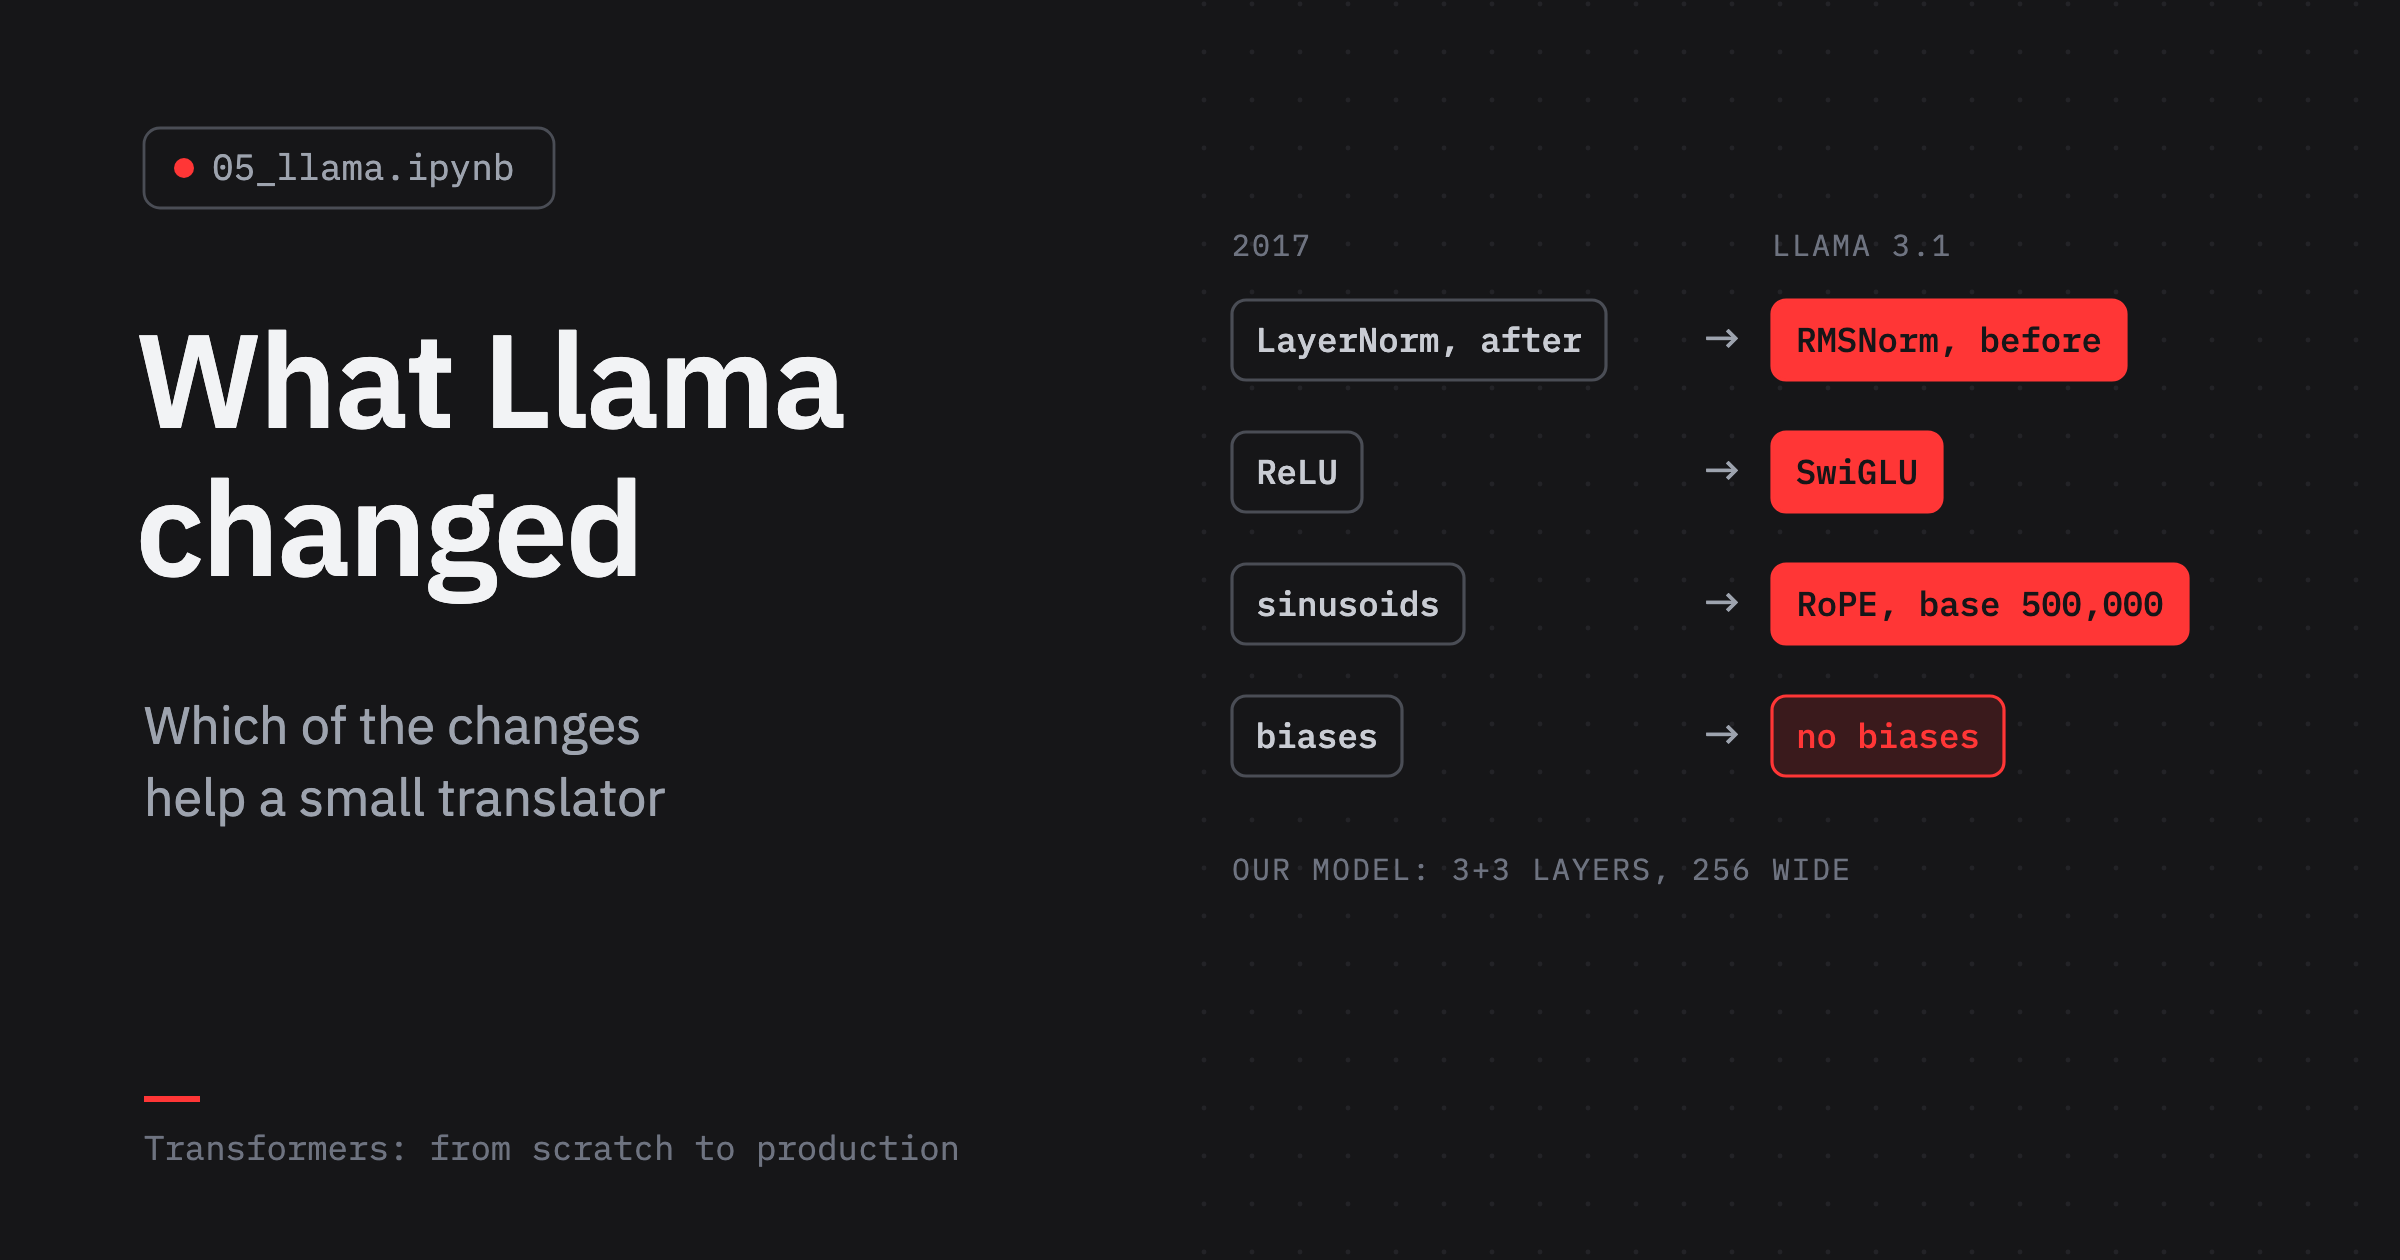
Pre-norm, RMSNorm, SwiGLU and RoPE: the changes Llama made to the 2017 Transformer, written in PyTorch, added to our translator one at a time and measured against what a new random seed does alone, with fused attention and a KV cache.
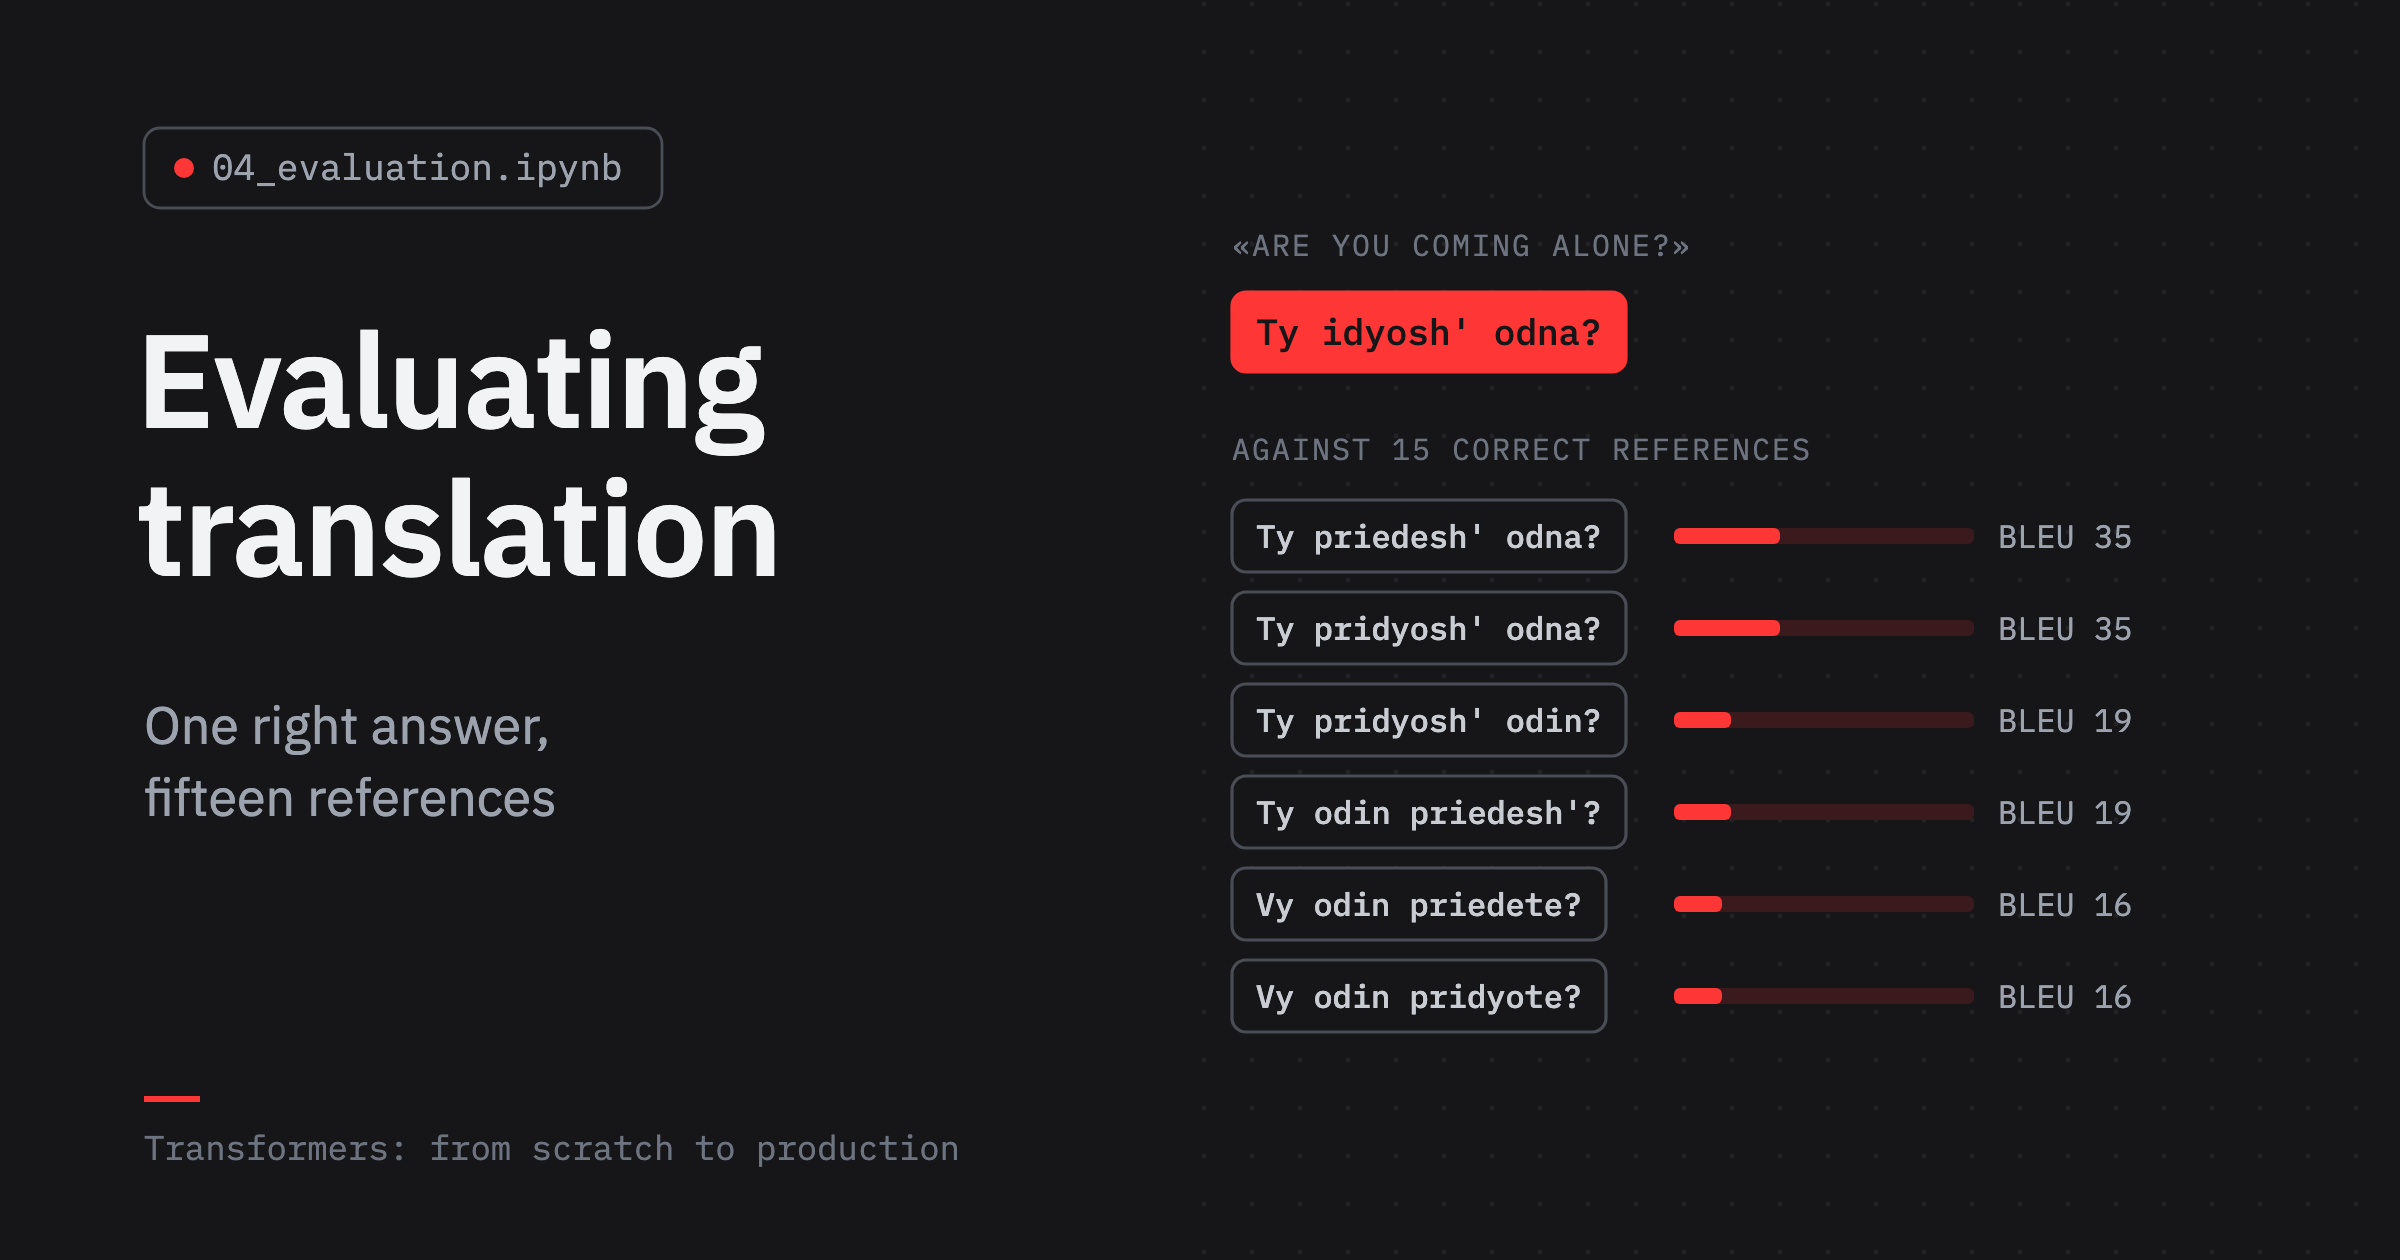
Evaluate English–Russian translation with BLEU, chrF and COMET written from scratch: multiple references, agreement with professional translators, significance tests and a contaminated test set.
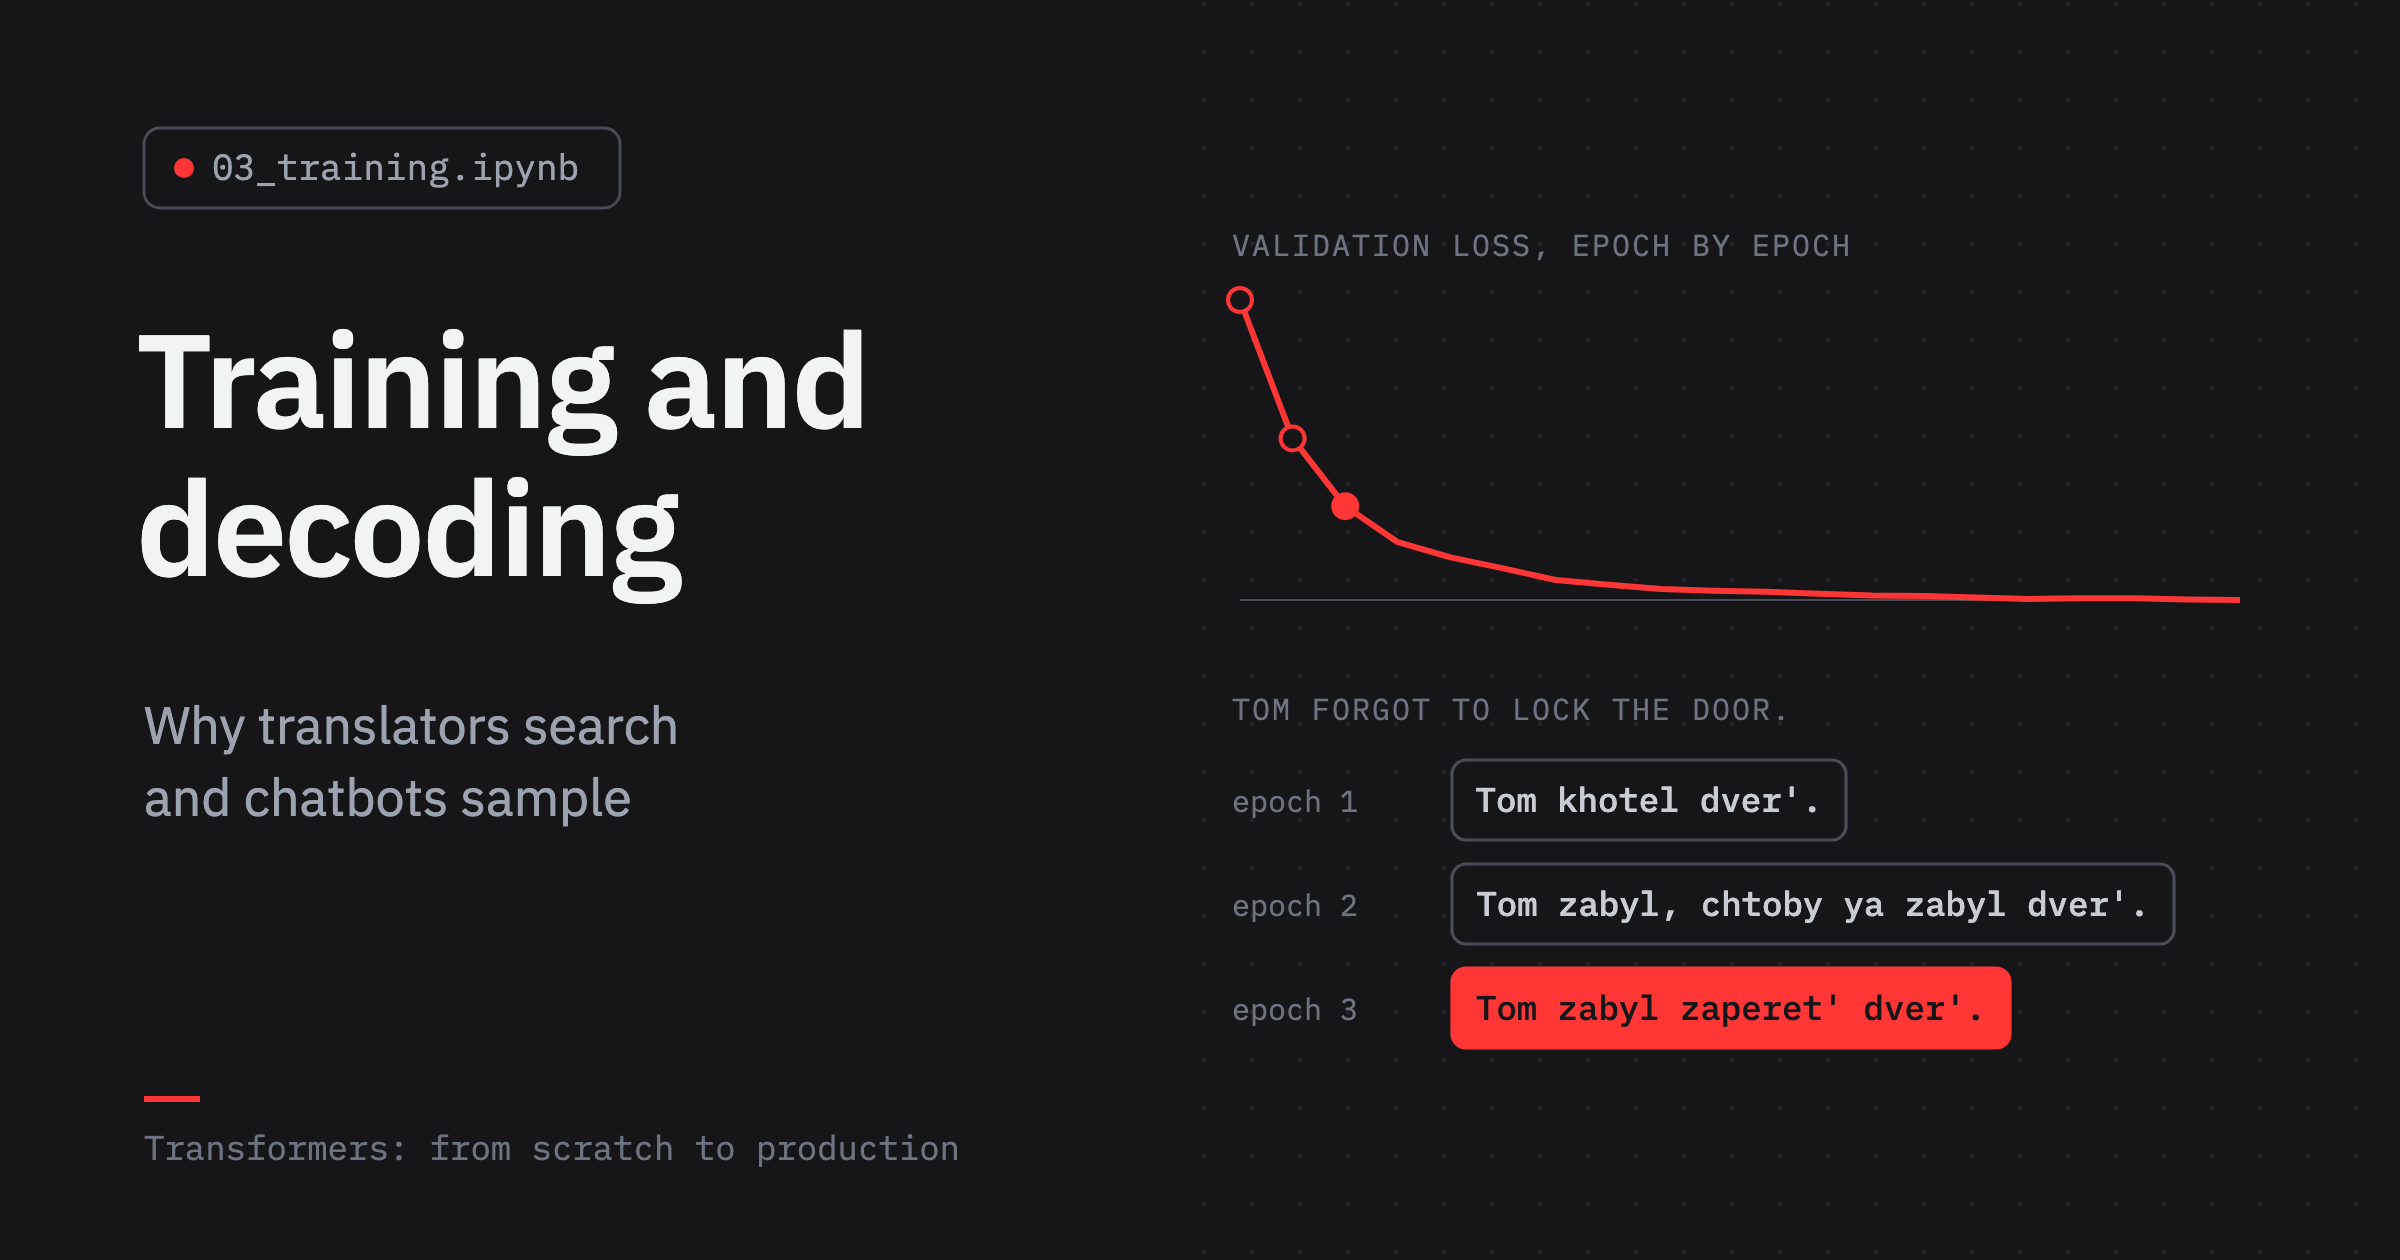
Train a Transformer on half a million sentence pairs on a free GPU, then decode it with greedy search, beam search and sampling.
Attention, masks, heads, positions and the full encoder-decoder of the 2017 paper, written line by line in PyTorch and checked against real models.
What GPT-4o actually receives when you type, why Russian costs more tokens than English, and byte-pair encoding written from scratch.
A patient who could reason about everything and decide nothing, a card game whose decks are rigged, and a theory that puts the body inside decisions: Damasio's somatic markers, the evidence for them and the evidence against
Why generating text is limited by memory rather than arithmetic, measured on a free GPU, and what serving engines like vLLM do about it: the KV cache, continuous batching, quantization and speculative decoding
How to adapt a pretrained transformer by training a fraction of a percent of it: what adapters, LoRA, prefix and prompt tuning, BitFit, (IA)³ and Compacter add to the model, written out in PyTorch and measured on one task
Symbols, rules and meaning: the computational theory of mind from McCulloch and Pitts to the Chinese Room, and what language models add to an old argument
Positional encoding, self-attention, multi-head attention and cross-attention, then the encoder and decoder layers, written in PyTorch one module at a time.
Byte-pair encoding written in Python step by step, trained on English–Russian sentences from Tatoeba and compared with the tokenizers of Hugging Face.
Why a fine-tuning update can be the product of two thin matrices: rank, the singular value decomposition and the Eckart–Young theorem, then LoRA's initialization, gradients and scale, derived by hand and checked on BERT
What a large language model is, how it is trained in three stages, and what it could and could not do in spring 2024: a tour after Andrej Karpathy's talk, with the claims checked against their sources and measured on small open models
Naming, comments, modules, tests, docstrings, exceptions and keyword arguments: the basic habits that keep Python code readable and easy to change