Contents
In 1950 Alan Turing made a prediction with numbers in it. In about fifty years, he wrote, computers would “play the imitation game so well that an average interrogator will not have more than 70 per cent chance of making the right identification after five minutes of questioning”[1].
He was a quarter of a century late, and then the machines overshot. In 2025 Cameron Jones and Benjamin Bergen ran Turing’s game as he described it: an interrogator chats for five minutes with two witnesses at once, one human and one machine, and has to say which is which.
Prompted to play “a young person who is introverted, knowledgeable about internet culture, and uses slang”, GPT-4.5 was picked as the human 73% of the time; the interrogators found the real human in only 27% of games against it[2].
The study also included, as a control, ELIZA, Joseph Weizenbaum’s program from 1966 that turns your sentences into questions. It was picked 23% of the time. In 1966 Weizenbaum had already noticed that “some subjects have been very hard to convince that ELIZA (with its present script) is not human”[3].
So a machine passes the test. Does it think? The answer depends on what you take thinking to be, and the most influential answer of the last eighty years is that thinking is computation: the mind is to the brain what a program is to the machine that runs it.
This is the computational theory of mind. It gave cognitive science its first research program and artificial intelligence its first name, and it has been attacked from the start on one question that language models have now made practical: can a system that manipulates symbols by their shapes ever mean anything by them?
Logic in the nervous system
The idea is older than computers. In 1943 the neurophysiologist Warren McCulloch and the logician Walter Pitts published “A logical calculus of the ideas immanent in nervous activity”[4].
They simplified the neuron to a unit that adds its weighted inputs and fires if the sum reaches a threshold, and showed that networks of such units can compute any proposition of logic.
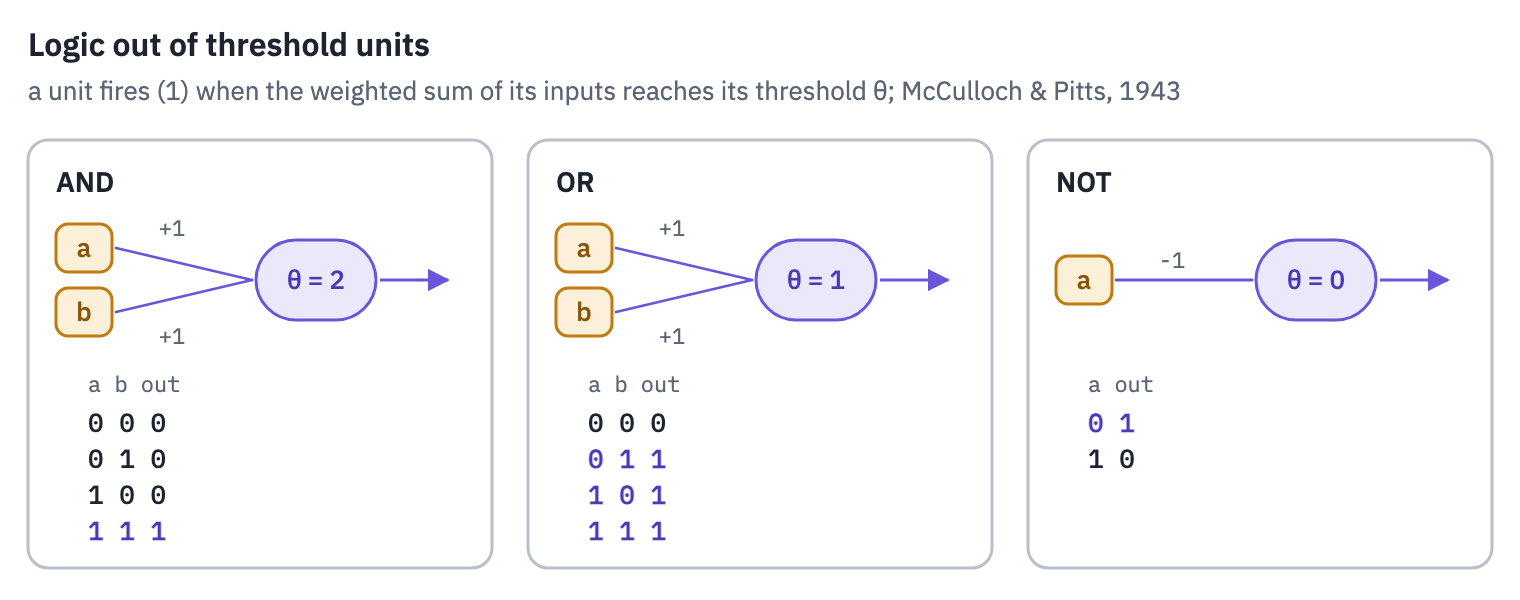
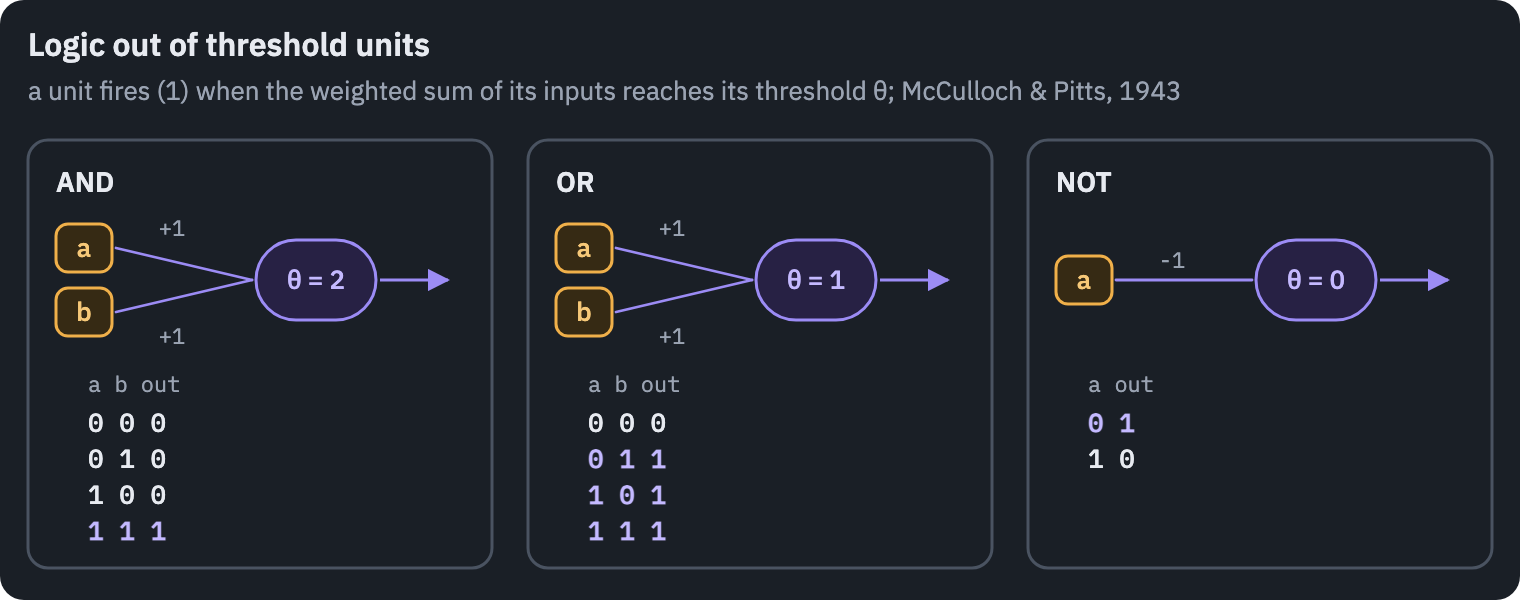
Three units suffice for AND, OR and NOT, and from those any Boolean function can be built. The neuron in this model is wrong in almost every biological detail, and the authors knew it.
The point was elsewhere: if neurons compute logical functions, then a brain is a kind of logic machine, and a thought might be a computation running on it.
Seven years earlier Turing had described a universal machine that can carry out any computation that can be written down as rules[5]. Put the two papers together and you get the founding bet of cognitive science: the brain implements a computer, and the mind is what it computes.
Symbols and search
The bet was stated most sharply by Allen Newell and Herbert Simon, whose Logic Theorist proved theorems from Principia Mathematica in 1956. Twenty years later, in their Turing Award lecture, they gave it the form of an empirical hypothesis[6]:
A physical symbol system has the necessary and sufficient means for general intelligent action.
A physical symbol system is a machine that holds physical patterns, symbols, combines them into expressions, and runs processes that create, copy, modify and destroy those expressions. “Necessary” means that anything intelligent is such a system, people included.
“Sufficient” means that a large enough system of this kind, suitably organized, would be intelligent. Both halves are strong claims, and Newell and Simon offered them the way a physicist offers a law: to be tested against what intelligent systems actually do.
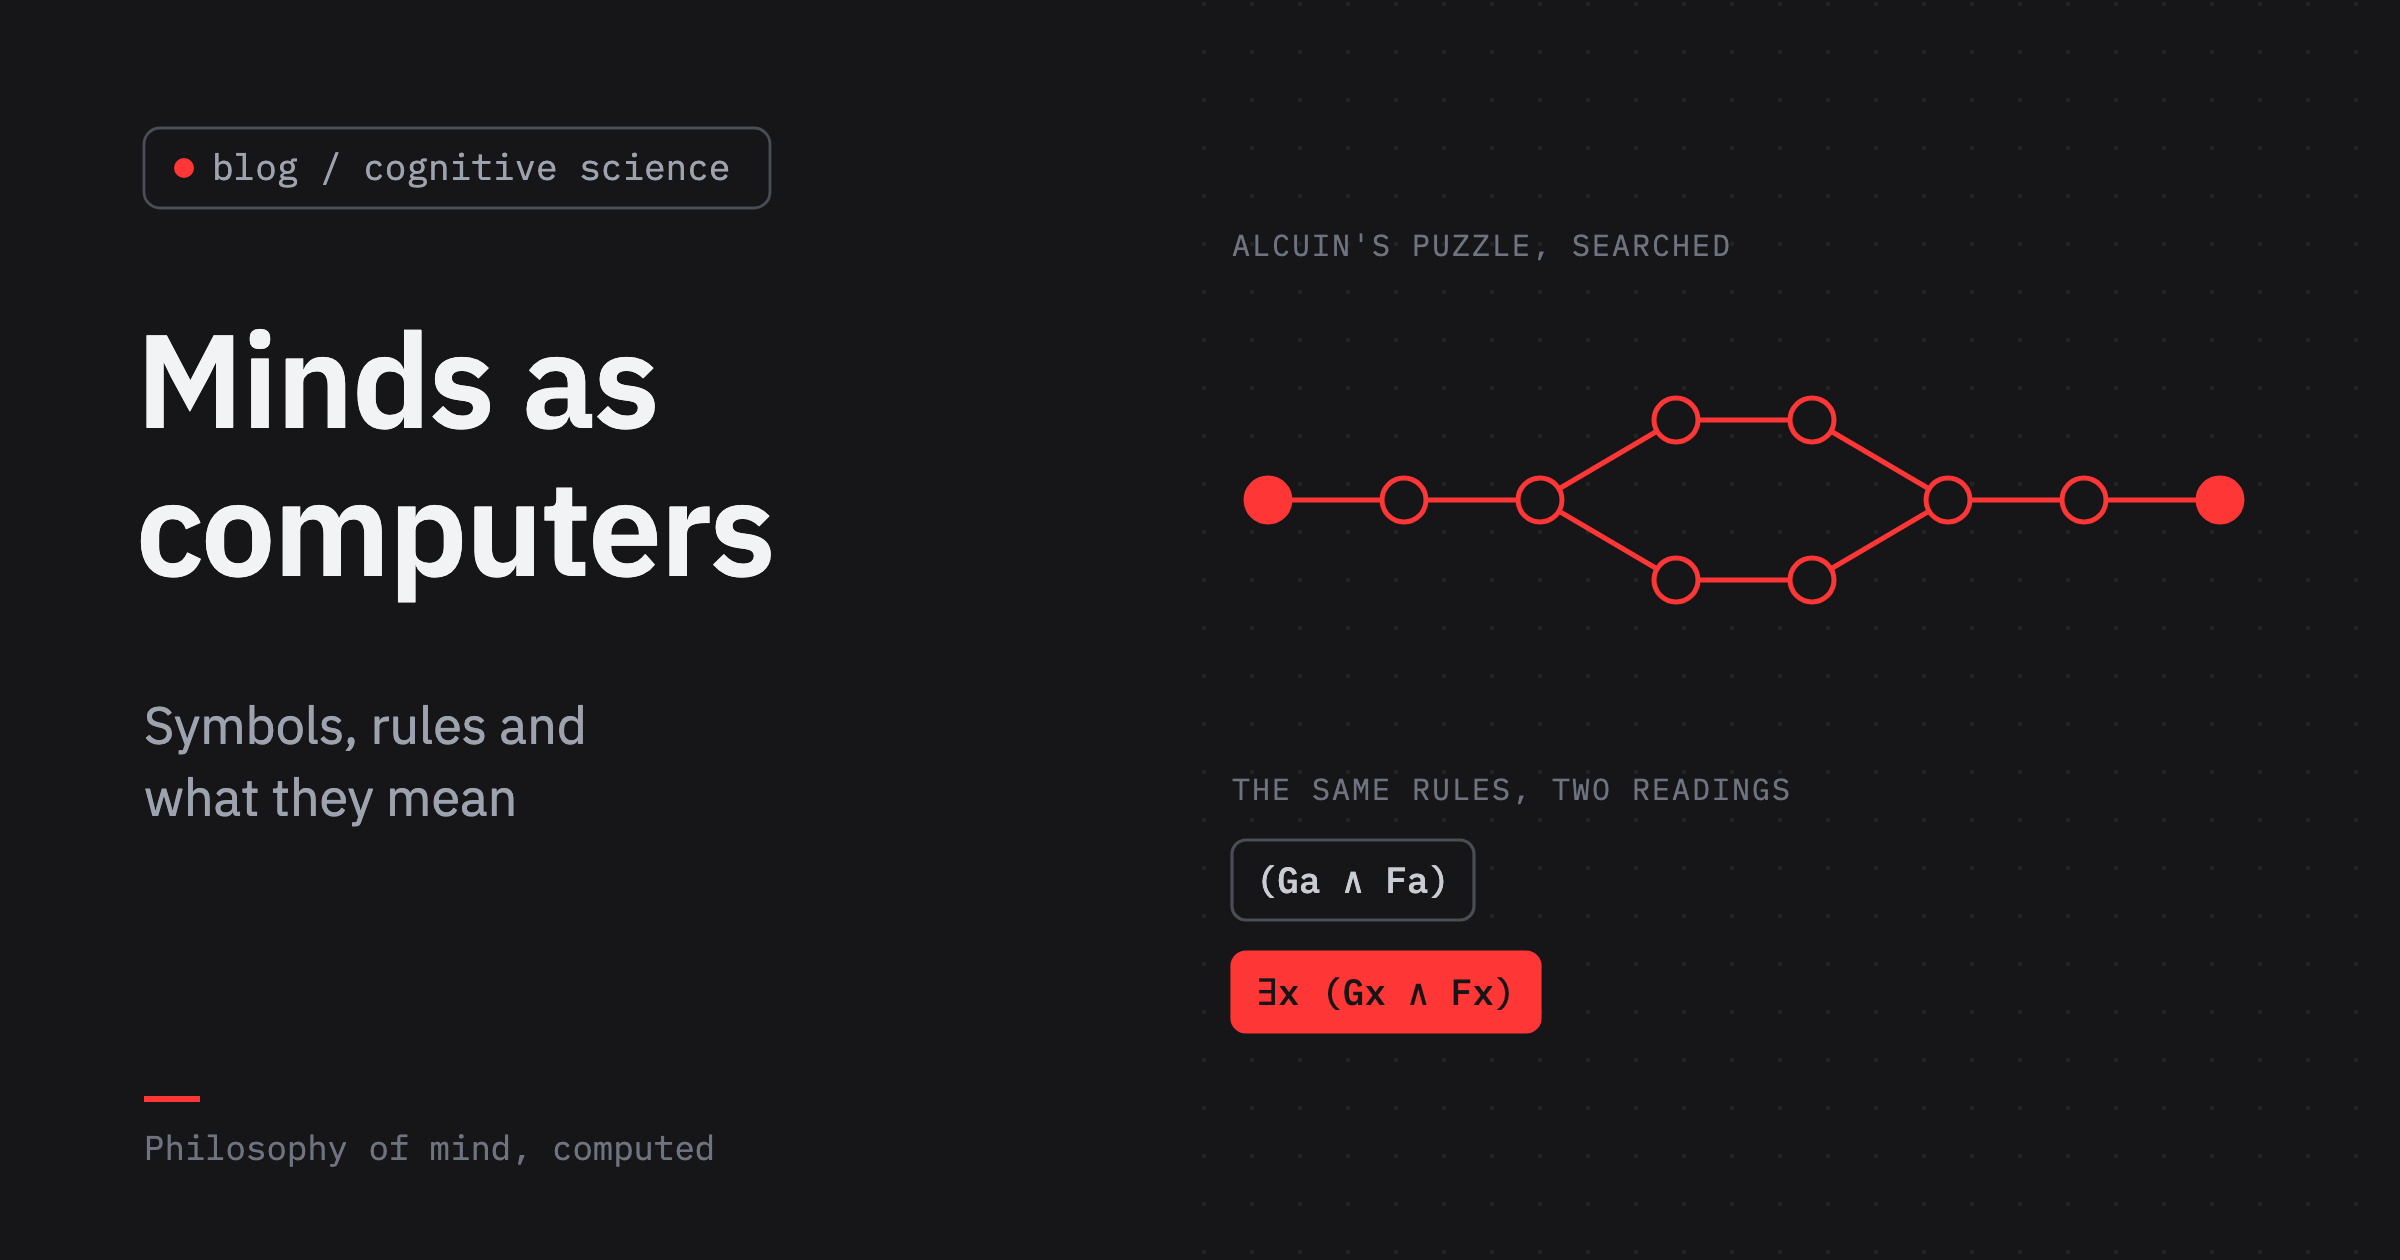
What does symbol processing look like in practice? Take a puzzle from Propositiones ad acuendos juvenes, “problems to sharpen the young”, a collection almost certainly by Alcuin of York from around 800 (MacTutor).
A man must take a wolf, a goat and a bundle of cabbages across a river in a boat that carries only two: him and one passenger. Left alone, the wolf eats the goat and the goat eats the cabbage.
For a symbol system the puzzle is a set of expressions, one per arrangement on the banks, and a rule that turns one arrangement into another. Solving it is searching:
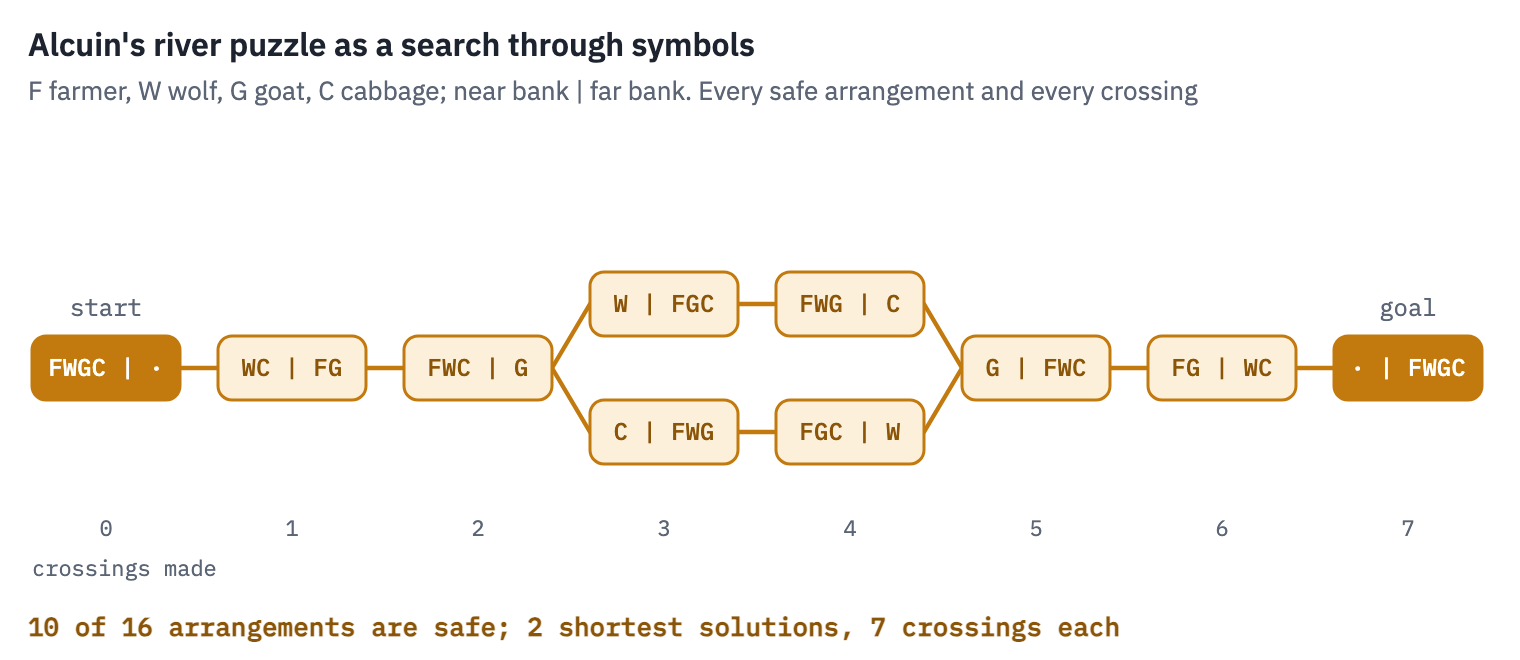
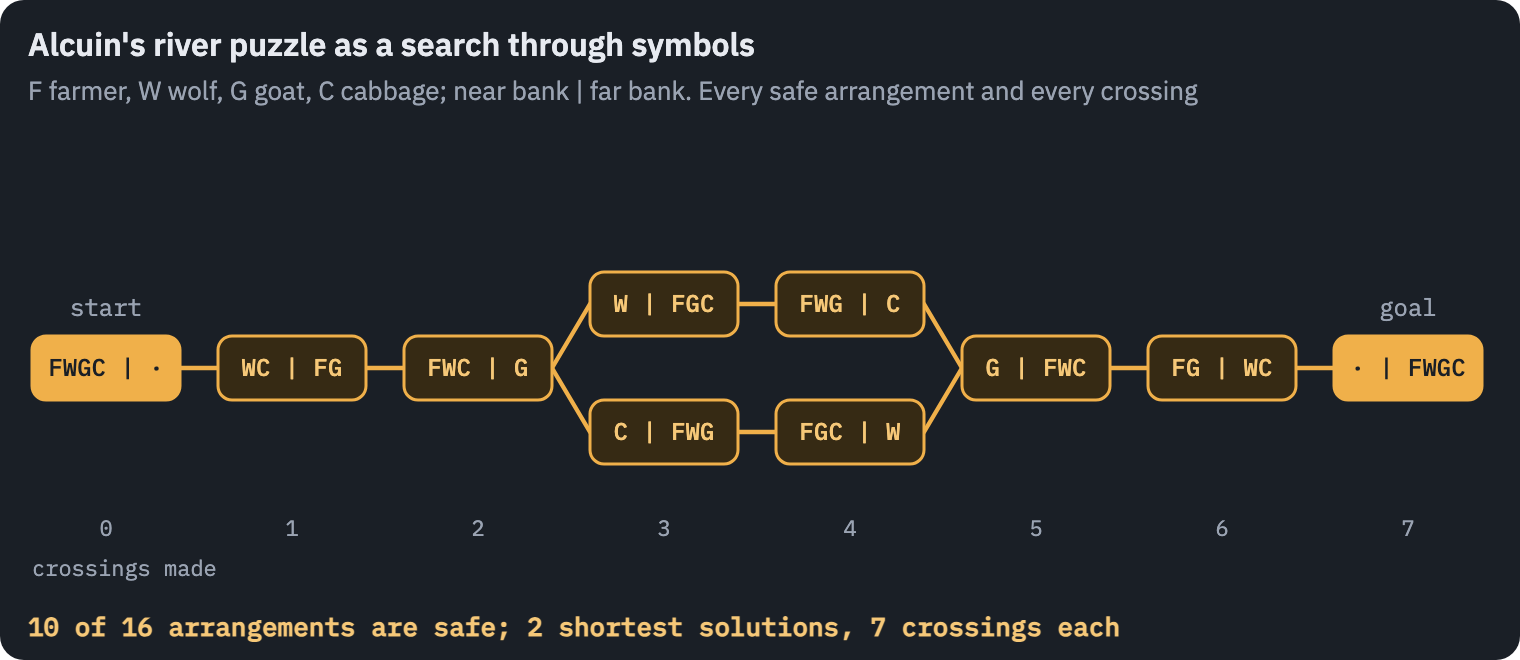
The search finds what people find by trial and error: there are only ten safe arrangements, and two shortest solutions that differ in whether the wolf or the cabbage goes over first.
Newell and Simon’s claim is that this is not an analogy for what you did when you solved the puzzle as a child. It is a description of it, written at a different level of detail.
A language of thought
The philosopher Jerry Fodor turned the hypothesis into a theory of the mind as psychology knows it[7]. We explain behaviour by beliefs and desires: she took the umbrella because she believed it would rain and wanted to stay dry.
Fodor argued that this kind of explanation works because it is literally true. Beliefs and desires are real states of the brain, and they have the structure of sentences in an inner language, a language of thought, sometimes called Mentalese.
The hard part is how the content of a belief, what it is about, can cause anything. Fodor’s answer came from logic and computers.
A proof checker does not understand the formulas it checks; it looks at their shapes. Yet logicians have designed the rules so that whenever the premises are true, the conclusion the rules produce is true too.
Syntax, done right, keeps track of semantics. If the mind is such a system, then thoughts cause other thoughts by their shapes, and the causation respects what they mean.
Here is the idea in the smallest form, in an example from José Luis Bermúdez’s textbook Cognitive Science[8]. Let \(Ga\) say that Georgina is tall and \(Fa\) that she has red hair.
One rule joins two sentences with \(\wedge\); another replaces a name by a variable bound by “there exists”. Neither rule looks at what \(G\), \(F\) or \(a\) mean:
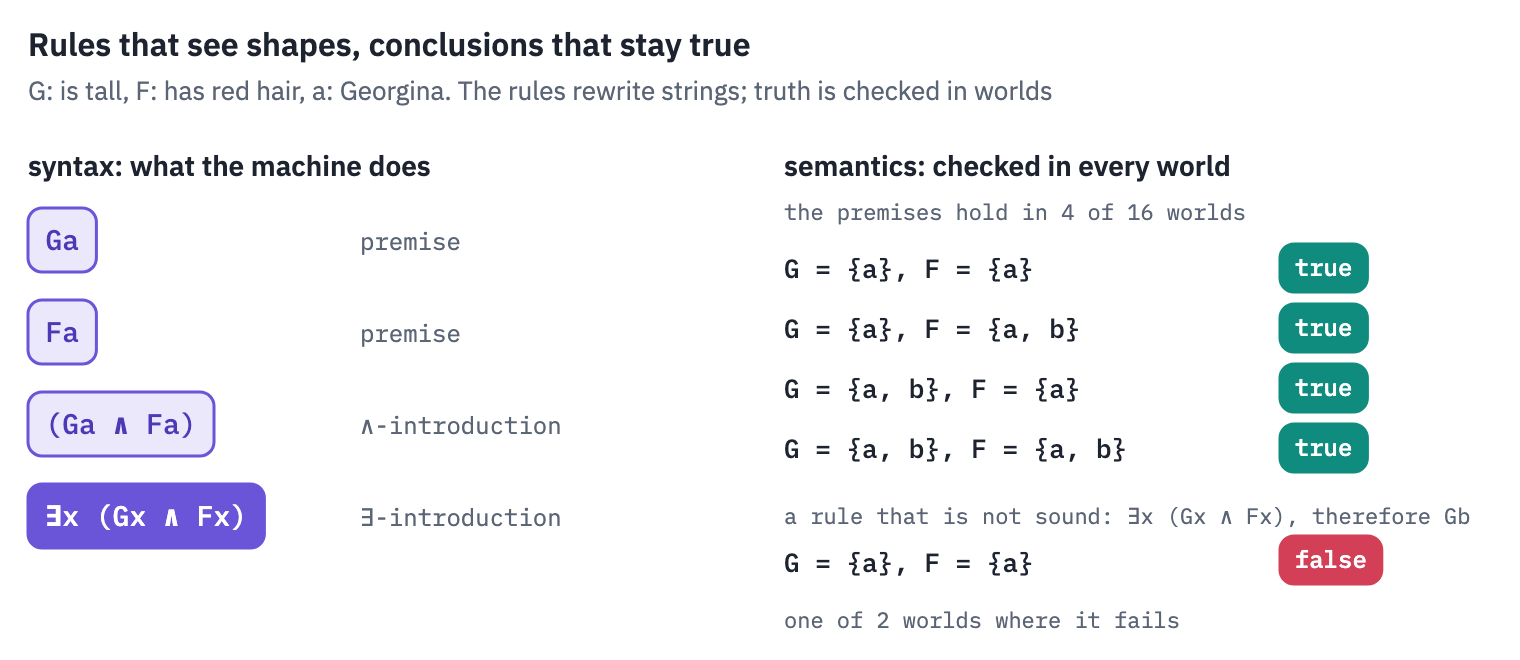
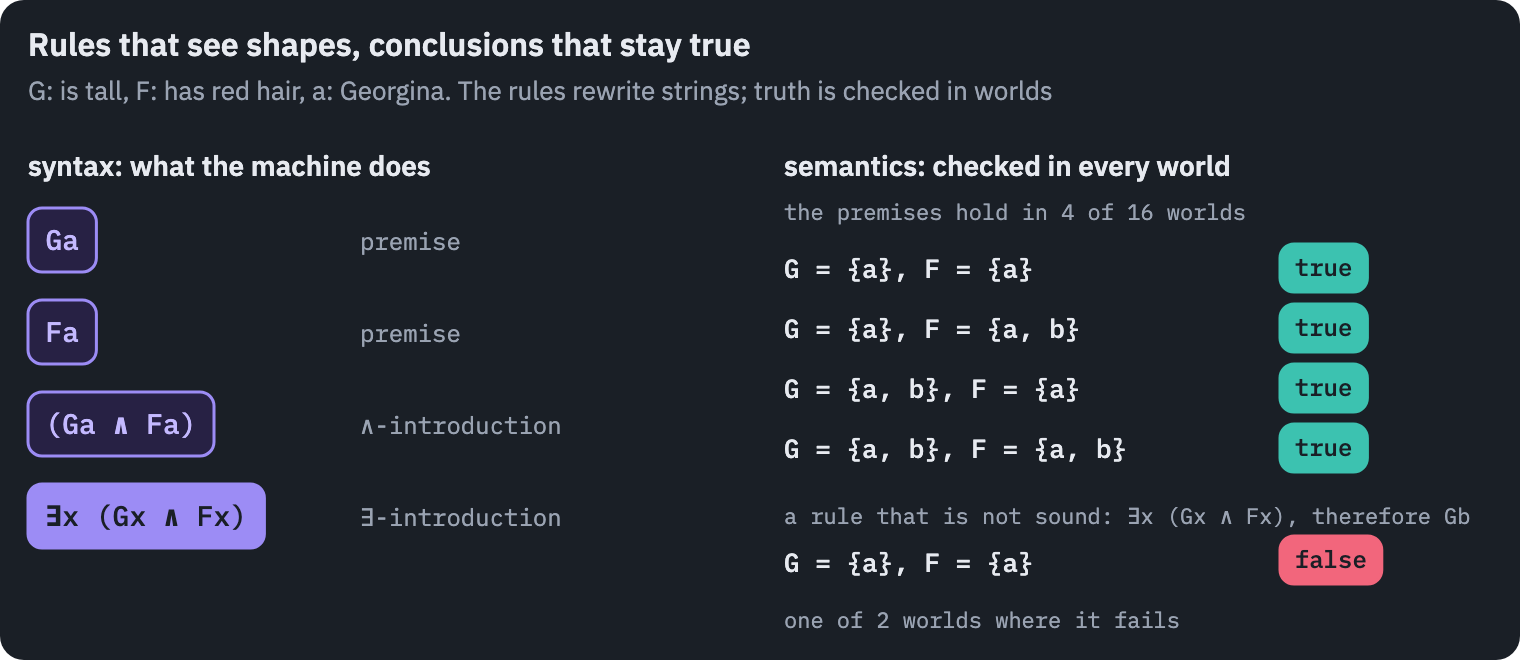
The check on the right is the whole point. Over every way the world could be, as far as these sentences can tell, the rules never lead from truths to a falsehood.
A rule that is not sound, such as concluding \(Gb\) from “someone is tall and red-haired”, fails in some world, and a well-built system simply does not have it.
Fodor and Zenon Pylyshyn later turned this into an argument against the alternative that was then on the rise, neural networks[9].
Thought is systematic: “you don’t find people who can understand the sentence ‘John loves the girl’ but not the sentence ‘the girl loves John’”, and the same holds for thinking those thoughts. It is productive: from finite means we can think indefinitely many new thoughts. A language with combinatorial syntax explains both for free.
A network that learns associations, they argued, either implements such a language, and is then just its hardware (“models of the implementation of a Classical architecture”), or fails to be systematic. Their verdict was blunt: “the mind cannot be, in its general structure, a Connectionist network.”
The same question at three levels
Part of the confusion in this debate is that “the mind is a computer” can mean three different things. The vision scientist David Marr separated them[10].
At the level of computational theory you say what is computed and why: a cash register computes addition, because combining prices must not depend on their order or grouping.
At the level of representation and algorithm you say how: decimal digits and carrying, or binary and shifts. At the level of implementation you say what physically does it: gears, transistors, neurons.
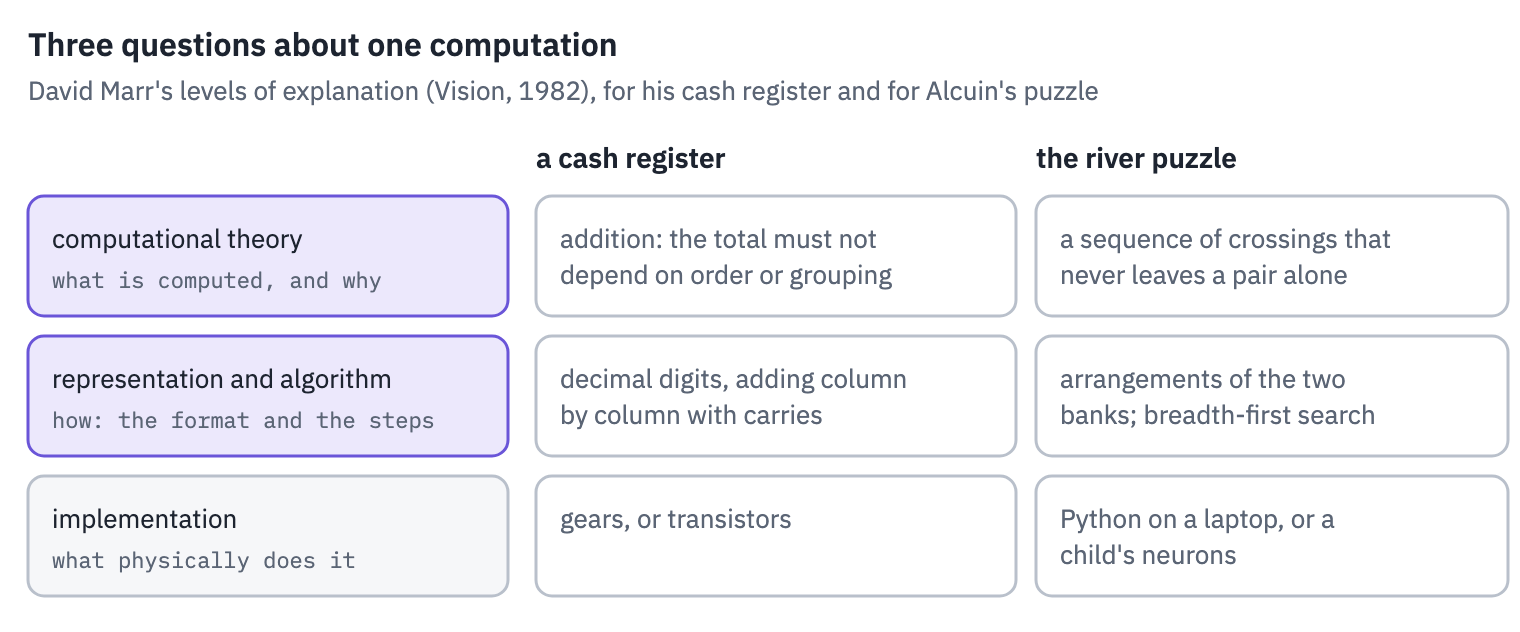
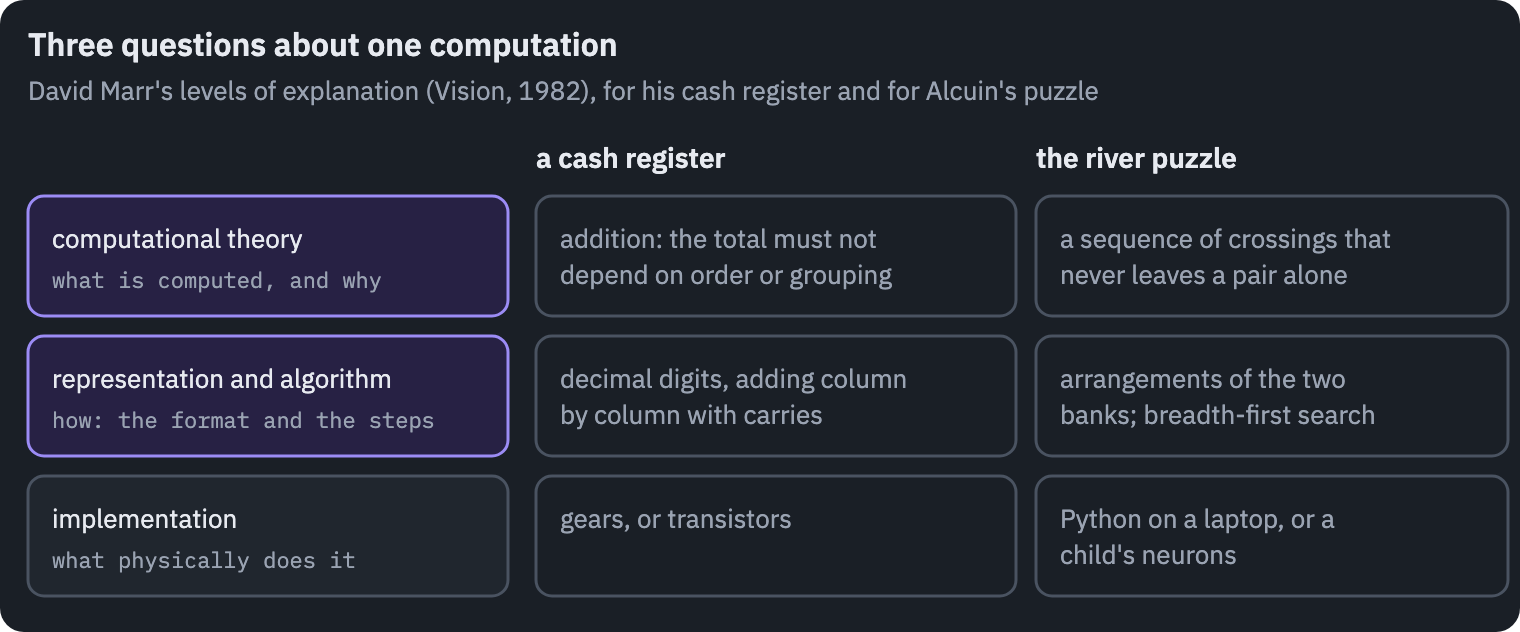
The computational theory of mind is a claim about the first two levels. It is perfectly compatible with neurons being nothing like transistors. It is also why “but the brain is not a von Neumann computer” is not an objection: nobody serious claimed that it was.
The Chinese Room
The best-known objection grants the theory everything at the level of behaviour and denies it at the level of mind. In 1980 John Searle asked you to imagine yourself locked in a room with boxes of Chinese characters and a rule book in English[11]. Questions in Chinese come in through a slot.
You look up their shapes in the book, which tells you which shapes to send back, and you send them. The answers are good enough to fool native speakers. You do not understand a word of Chinese.
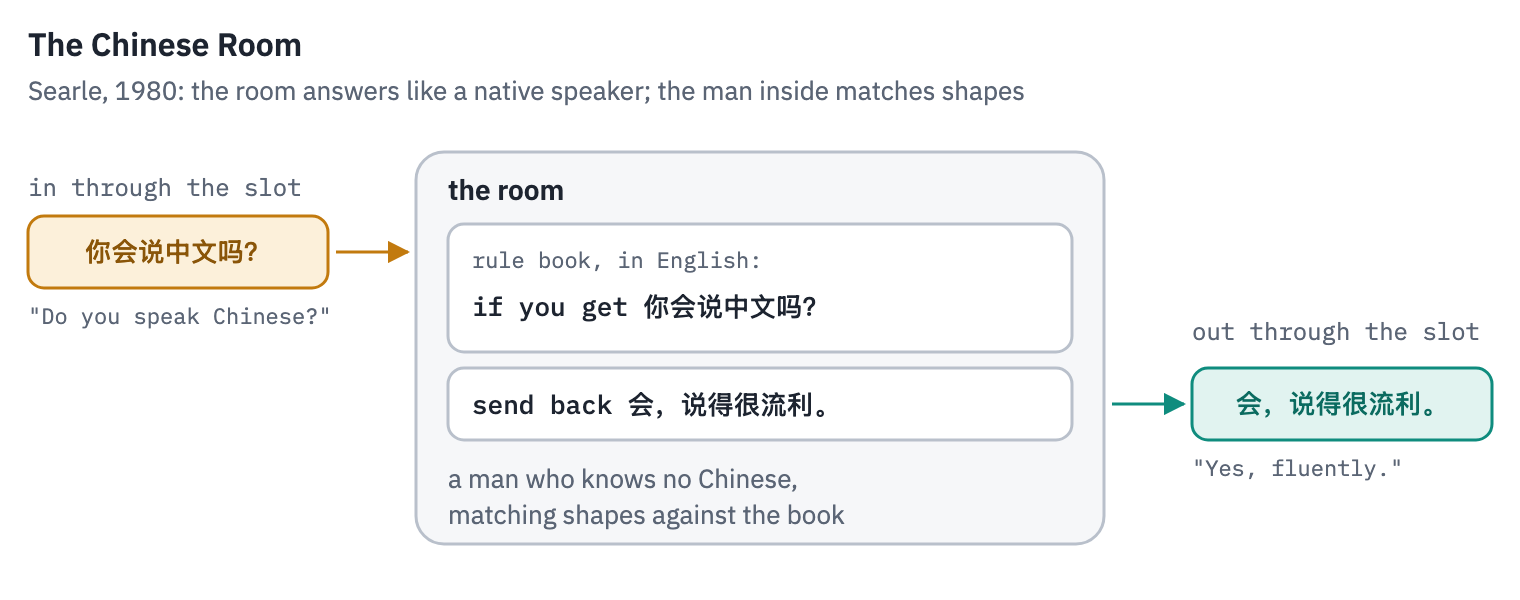
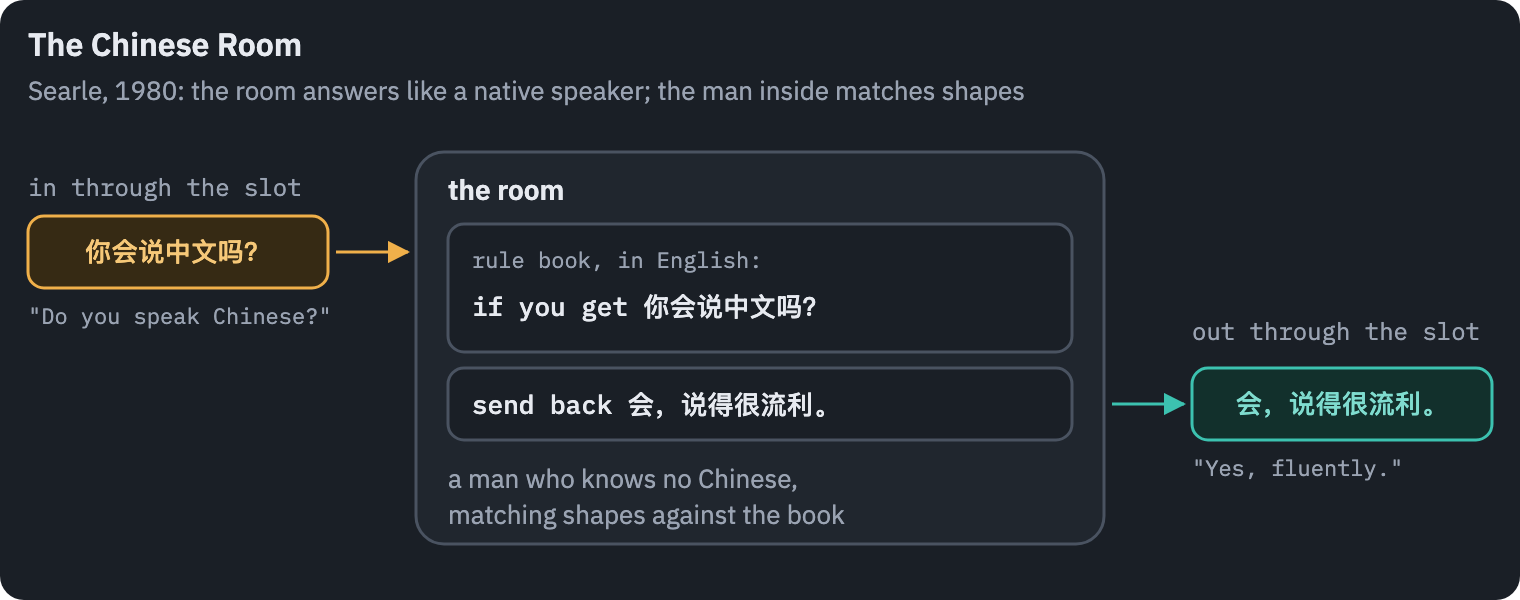
The room runs a program for understanding Chinese, Searle says, and nothing in it understands Chinese. So running a program is not sufficient for understanding.
He called the claim he was attacking strong AI: that an appropriately programmed computer literally has a mind. Weak AI, the use of computers to model and test theories of the mind, he had no quarrel with.
Searle listed the replies he had already heard and answered each one in the same paper:
- The systems reply: you do not understand Chinese, but the whole system, you plus the book plus the paper, does. Searle: then memorize the book and do the lookups in your head. Now you are the whole system, and you still understand nothing.
- The robot reply: put the program in a robot with cameras and arms, so its symbols connect to things. Searle: the man in the room now also receives symbols from cameras and sends symbols to motors. Still shapes.
- The brain simulator reply: make the program simulate the firing of a Chinese speaker’s neurons. Searle: simulate it with water pipes and valves, operated by the man. The pipes do not understand Chinese either.
The argument is still argued about. One line of reply, from Paul and Patricia Churchland, is that intuitions about rooms are a poor guide to large systems: a person waving a magnet in a dark room produces electromagnetic waves too slow to see, and would conclude, wrongly, that light is not electromagnetism[12].
Searle had also anticipated neural networks: replace the room with a “Chinese gym”, a hall full of English speakers each doing what a unit does, and still nobody understands Chinese[13].
What he established beyond doubt is narrower than his conclusion, and still important: behaviour alone does not settle the question. In 1980 he had already granted that “there could be two ‘systems,’ both of which pass the Turing test, but only one of which understands”.
Where do symbols get their meaning?
Stevan Harnad sharpened Searle’s point into a problem that any theory has to solve, not just computational ones[14]. Imagine trying to learn Chinese from a Chinese-Chinese dictionary.
Every word is defined by other words, which are defined by other words, and you go round forever without touching anything. This is the symbol grounding problem: how do the symbols of a system come to be about things in the world, rather than only about each other?
Harnad’s own answer was that some symbols must be grounded in perception, in the categories that sensory systems learn to pick out.
Language models are the dictionary-go-round built at scale. They learn from text alone, and on Harnad’s view they should have no grounded meanings at all.
Emily Bender and Alexander Koller made the argument with an octopus that taps a telegraph cable between two islands and learns to imitate one of the speakers perfectly, until someone asks it for help against a bear[15]. Form, they argue, is not enough to learn meaning.
It turns out that form carries more than this suggests. Here is a small test you can run. Take fifty colour names, and for each the colour people mean by it, from an online survey in which over five million colours were named in 222,500 sessions[16].
Place the colours in CIELAB, a space built so that equal distances look equally different. Then take Qwen2.5-1.5B, a model that has never seen a colour, give it each name in a sentence, and compare the distances between its internal states:
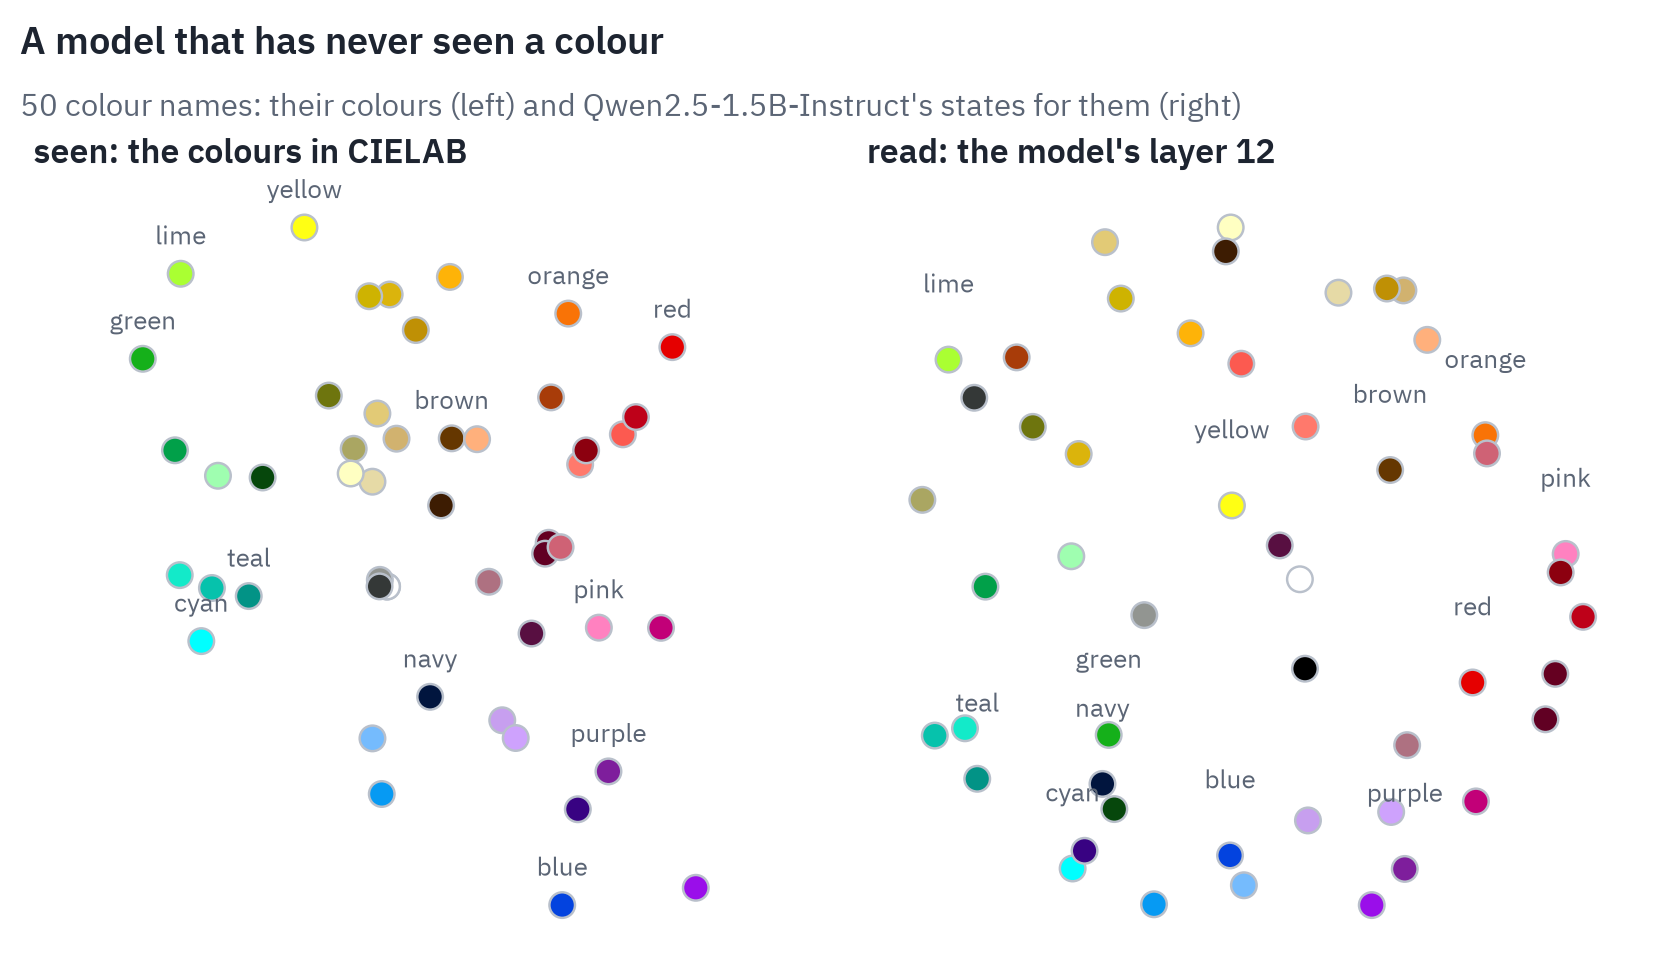
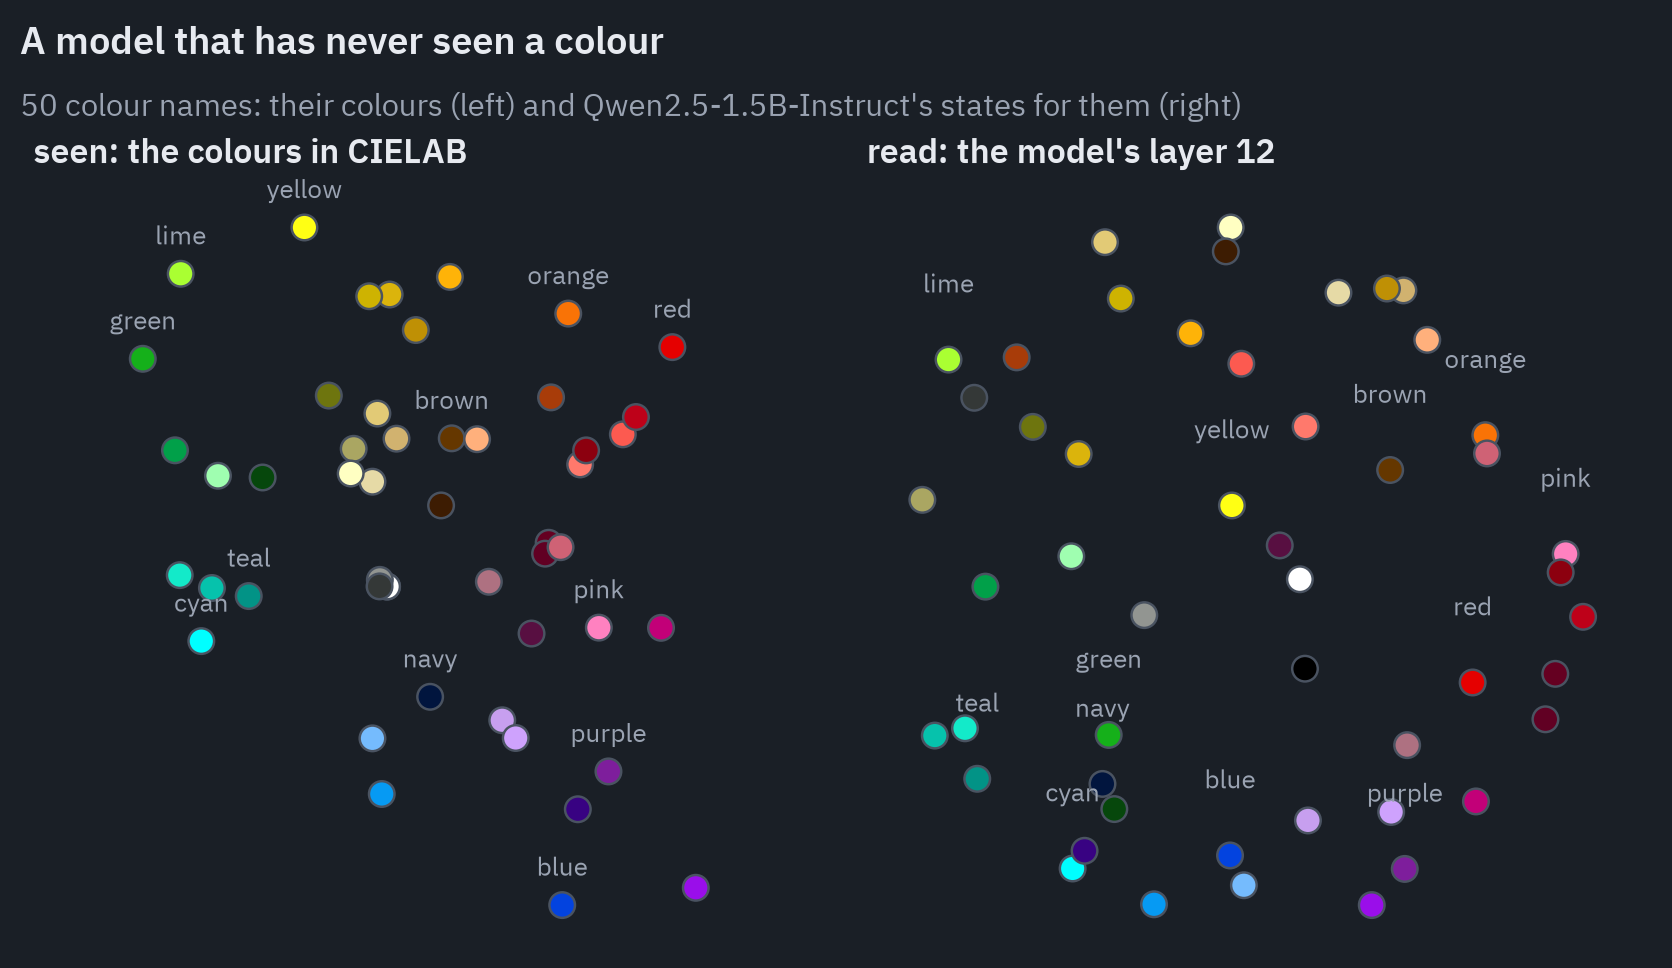
The geometry is far from perfect, but it is there. Blues sit with blues, reds with reds and pinks, teal between green and blue.
The rank correlation between the two sets of distances is 0.38, and none of 2,000 shuffles of the words comes close. It is not an accident of one layer either:
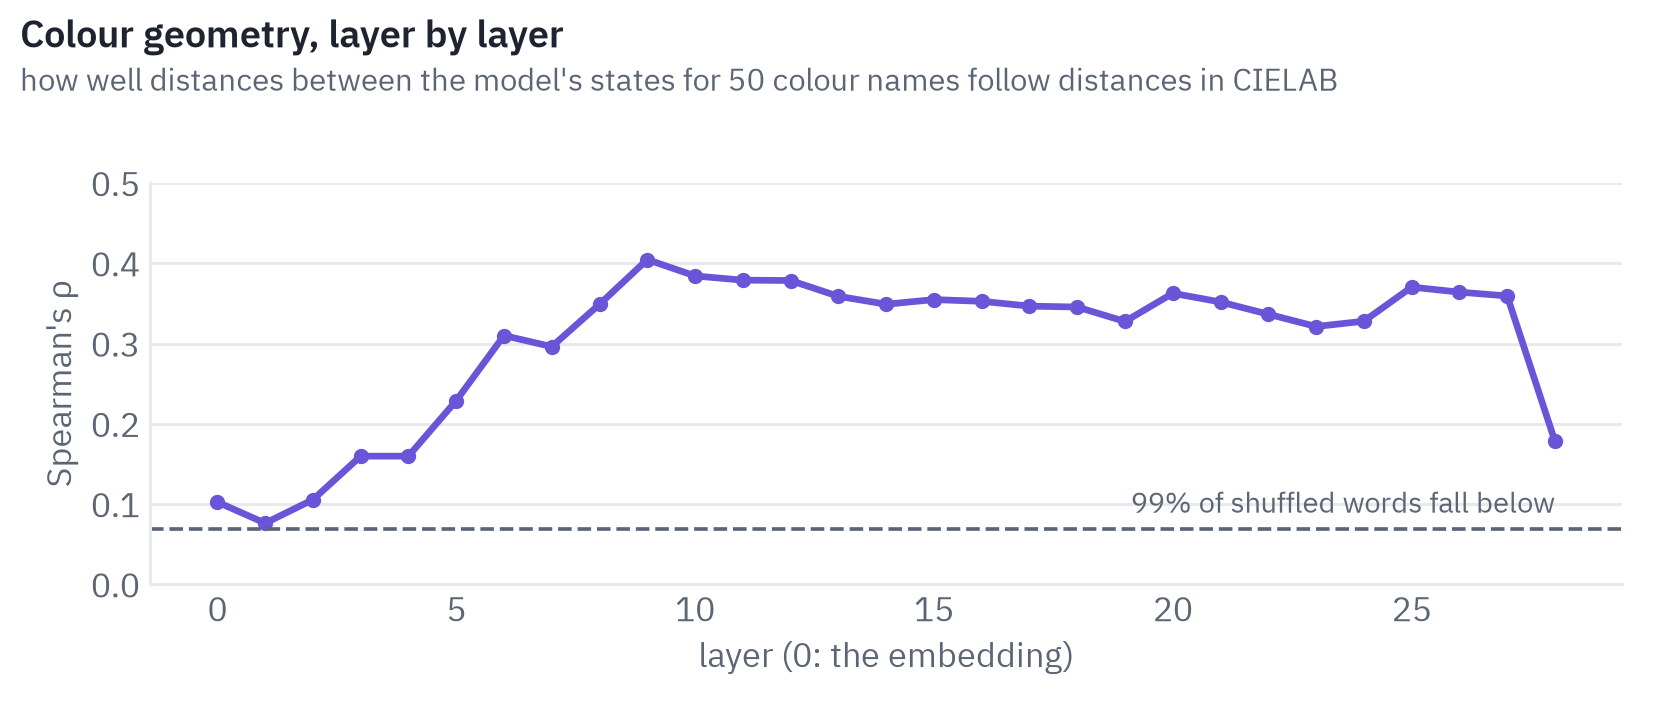
The embedding layer knows little; from the sixth layer on, the model’s states keep a stable fraction of the colour space.
Abdou et al. (2021) found a modest but significant alignment of the same kind in several language models, and GPT-4’s judgments of how similar two colours are, given only their names, agree with people’s at r = 0.79[17].
Text is not as cut off from the world as the dictionary image suggests, because people wrote it about the world: about skies that were deep blue, and teal that sits between green and blue. Congenitally blind people show the same from the other side.
Asked how similar colour words are, they produce a map that resembles the colour space of sighted people[18], and they share sighted people’s understanding of what colours are for, learned from “living among people who talk about color”[19].
None of this answers Searle. A geometry of colour words is not the experience of red, and a system can have the first without the second. What it does change is the shape of the argument.
The question is no longer whether meaning can come from symbols alone, yes or no, but how much of it does, and which part can only come from somewhere else.
Networks, systematicity and language models
Fodor and Pylyshyn’s challenge to neural networks became testable. In 2018 Brenden Lake and Marco Baroni built SCAN, a set of commands such as “jump twice and walk left”, and trained sequence-to-sequence networks on it[20].
On a random split of the data the best network got 99.8% of new commands right. When “jump” appeared in training only on its own and had to be combined with the rest of the grammar at test time, the best network got 1.2%.
People do this effortlessly. Five years later the same authors trained a standard transformer on a stream of small composition tasks, each with its own made-up grammar, and on a new task it matched the algebraic answer as often as people did, or more[21].
They wrote that they had addressed “Fodor and Pylyshyn’s challenge”, and in the same paper listed what was left: much longer outputs and new sentence structures still defeated the model. Systematicity was not built in; it was learned from practice at being systematic.
Something similar shows up inside sequence models. A transformer trained only on lists of moves in the board game Othello, never shown a board, develops an internal representation of the board that can be read out and edited: change it, and the model’s next moves change as if the board were different[22].
Read as “my stones and the opponent’s” rather than “black and white”, the board can be recovered by a simple linear probe with 99.6% accuracy[23]. Othello is a toy world, fully determined by the moves, so this shows structure rather than reference to anything outside the text.
But it does show that such a network is not only associating surface forms. It builds structured states and computes with them, which is closer to what Fodor asked for than either side expected.
What the metaphor leaves out
The computational theory never lacked critics who thought it was looking in the wrong place. Hubert Dreyfus argued from the 1970s that human expertise rests on embodied know-how, not explicit rules[24].
The enactive tradition of Francisco Varela, Evan Thompson and Eleanor Rosch put the body and its activity at the centre[25]. More recent predictive processing theories describe the brain as a hierarchy that predicts its own sensory input and learns from the errors[26, 27].
Notice, though, that most of these are still computational at Marr’s first two levels. They disagree about what is computed and in what format, not about whether the mind computes.
The numbers also remind you how different the hardware is. A human brain has about 86 billion neurons[28], weighs about 2% of the body and uses about 20% of its oxygen[29].
That comes to roughly 20 watts, “a paltry sum given that the computer on which this article is being typed requires 80 W”, as the physicist Vijay Balasubramanian put it[30].
Which brings back the test. The interrogators who picked GPT-4.5 over a person were not wrong about anything they could check: the replies were what a person would write.
Turing proposed the game because he found “Can machines think?” “too meaningless to deserve discussion”, and behaviour was all anyone could go on. Seventy-five years later that is no longer true.
We can open the model, read off the board it keeps for Othello or the geometry it keeps for colour, and ask how much of a mind is in there, piece by piece. Searle’s room had no windows. This one does.
References
- Turing, A. M. (1950). Computing machinery and intelligence. Mind, 59(236), 433–460. ↩
- Jones, C. R., & Bergen, B. K. (2025). Large language models pass the Turing test. arXiv:2503.23674. ↩
- Weizenbaum, J. (1966). ELIZA: a computer program for the study of natural language communication between man and machine. Communications of the ACM, 9(1), 36–45. ↩
- McCulloch, W. S., & Pitts, W. (1943). A logical calculus of the ideas immanent in nervous activity. Bulletin of Mathematical Biophysics, 5, 115–133. ↩
- Turing, A. M. (1936). On computable numbers, with an application to the Entscheidungsproblem. Proceedings of the London Mathematical Society, s2-42(1), 230–265. ↩
- Newell, A., & Simon, H. A. (1976). Computer science as empirical inquiry: symbols and search. Communications of the ACM, 19(3), 113–126. ↩
- Fodor, J. A. (1975). The Language of Thought. Crowell; Harvard University Press. ↩
- Bermúdez, J. L. (2014). Cognitive Science: An Introduction to the Science of the Mind (2nd ed.). Cambridge University Press. ↩
- Fodor, J. A., & Pylyshyn, Z. W. (1988). Connectionism and cognitive architecture: a critical analysis. Cognition, 28(1–2), 3–71. ↩
- Marr, D. (1982). Vision. W. H. Freeman. ↩
- Searle, J. R. (1980). Minds, brains, and programs. Behavioral and Brain Sciences, 3(3), 417–457. ↩
- Churchland, P. M., & Churchland, P. S. (1990). Could a machine think? Scientific American, 262(1), 32–37. ↩
- Searle, J. R. (1990). Is the brain’s mind a computer program? Scientific American, 262(1), 26–31. ↩
- Harnad, S. (1990). The symbol grounding problem. Physica D, 42(1–3), 335–346. ↩
- Bender, E. M., & Koller, A. (2020). Climbing towards NLU: on meaning, form, and understanding in the age of data. ACL. ↩
- Munroe, R. (2010). Color survey results; the names and colours: rgb.txt, public domain. ↩
- Marjieh, R., et al. (2024). Large language models predict human sensory judgments across six modalities. Scientific Reports, 14, 21445. ↩
- Saysani, A., Corballis, M. C., & Corballis, P. M. (2018). Colour envisioned: concepts of colour in the blind and sighted. Visual Cognition, 26(5), 382–392. ↩
- Kim, J. S., Aheimer, B., Montané Manrara, V., & Bedny, M. (2021). Shared understanding of color among sighted and blind adults. PNAS, 118(33), e2020192118. ↩
- Lake, B., & Baroni, M. (2018). Generalization without systematicity. ICML. ↩
- Lake, B. M., & Baroni, M. (2023). Human-like systematic generalization through a meta-learning neural network. Nature, 623, 115–121. ↩
- Li, K., et al. (2023). Emergent world representations: exploring a sequence model trained on a synthetic task. ICLR. ↩
- Nanda, N., Lee, A., & Wattenberg, M. (2023). Emergent linear representations in world models of self-supervised sequence models. BlackboxNLP. ↩
- Dreyfus, H. L. (1972). What Computers Can’t Do. Harper & Row. ↩
- Varela, F. J., Thompson, E., & Rosch, E. (1991). The Embodied Mind. MIT Press. ↩
- Clark, A. (2013). Whatever next? Predictive brains, situated agents, and the future of cognitive science. Behavioral and Brain Sciences, 36(3), 181–204. ↩
- Friston, K. (2010). The free-energy principle: a unified brain theory? Nature Reviews Neuroscience, 11(2), 127–138. ↩
- Azevedo, F. A. C., et al. (2009). Equal numbers of neuronal and nonneuronal cells make the human brain an isometrically scaled-up primate brain. Journal of Comparative Neurology, 513(5), 532–541. ↩
- Raichle, M. E., & Gusnard, D. A. (2002). Appraising the brain’s energy budget. PNAS, 99(16), 10237–10239. ↩
- Balasubramanian, V. (2021). Brain power. PNAS, 118(32), e2107022118. ↩
- Abdou, M., et al. (2021). Can language models encode perceptual structure without grounding? A case study in color. CoNLL.
- Stanford Encyclopedia of Philosophy: The Computational Theory of Mind, The Chinese Room Argument, The Language of Thought Hypothesis, Connectionism.
The measurement of colour in Qwen2.5-1.5B and the figures: articles/minds_as_computers.