Contents
In section 7 of the paper that introduced LoRA there is a table its authors present with the words “To our surprise”. Edward Hu and colleagues at Microsoft had adapted GPT-3, all 175 billion parameters of it, by adding a trainable low-rank matrix to the query and value projections in each of its 96 layers, and they varied the rank.
At rank 1 the change to each \(12{,}288 \times 12{,}288\) matrix is the product of one column and one row: 24,576 numbers standing in for 151 million.
With it GPT-3 reached 73.4% on WikiSQL and 91.3% on MultiNLI; at rank 64, 73.5% and 91.4%. “A rank as small as one suffices for adapting both \(W_q\) and \(W_v\) on these datasets”, the caption concludes[1].
Two years later Damjan Kalajdzievski argued that the table proves less than it seems: the way LoRA scales its update, the paper showed, slows high ranks down so much that they could not have done better[2].
And in 2024 Dan Biderman and colleagues measured the changes that full fine-tuning makes to Llama 2 and found them to have “a rank that is 10-100× greater than typical LoRA configurations”[3].
So is a fine-tuning update low-rank or not? This post works through the linear algebra LoRA rests on: rank, the singular value decomposition, and the theorem that says how well a low-rank matrix can stand in for a full one.
Then through LoRA itself: why it starts the way it does, what its gradients see, and why a constant that looks like bookkeeping, the scale \(\alpha / r\), decides what a higher rank can do.
Every formula is checked, by a few lines of code or on a real model: bert-base fine-tuned on SST-2 48 times, with ranks from 1 to 256, two scaling rules, two learning-rate ratios and one factor frozen at a time. (If the transformer itself needs a refresher, the course Transformers: from scratch to production builds one; the adapters post puts LoRA among its relatives.)
What a matrix does
A weight matrix \(W\) with \(m\) rows and \(n\) columns is a machine for turning vectors into vectors: it takes \(x\) with \(n\) coordinates and returns \(Wx\) with \(m\). In bert-base, the query projection of every attention layer takes the 768 numbers that describe a token and returns 768 others.
Matrices that size are impossible to picture, but a \(2 \times 2\) matrix can be watched at work. Feed it every point of the unit circle and see where they land:
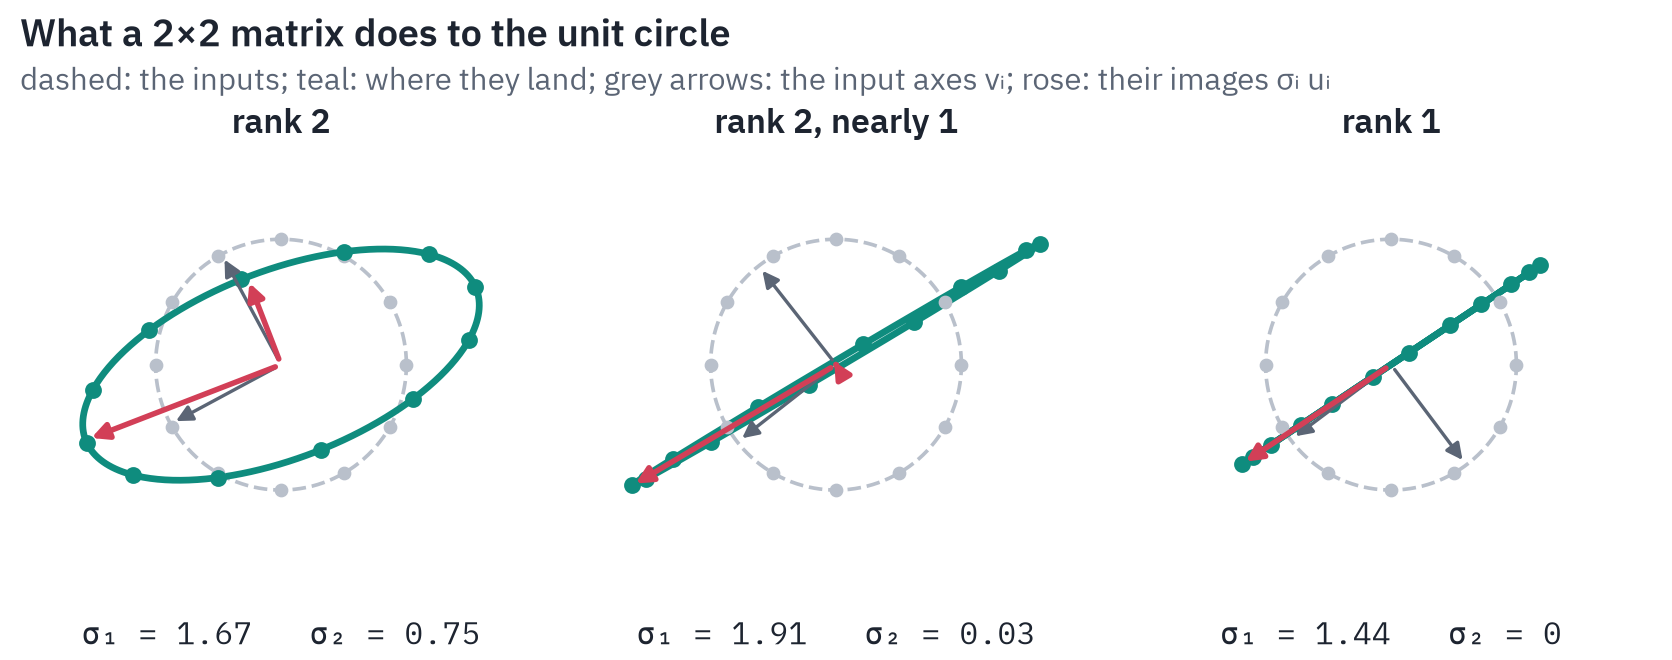
Whatever the matrix, the circle becomes an ellipse, possibly a flat one. That is a general fact, and the most useful one in this post.
Every matrix, of any shape, does three things in a row: it turns the input, stretches it along perpendicular axes, and turns the result. This is the singular value decomposition (SVD):
\[W = U \Sigma V^\top = \sum_{i=1}^{\min(m,n)} \sigma_i \, u_i v_i^\top .\]The columns \(v_i\) of \(V\) are perpendicular unit vectors in the input space (the grey arrows), and the columns \(u_i\) of \(U\) are perpendicular unit vectors in the output space. The singular values \(\sigma_1 \ge \sigma_2 \ge \dots \ge 0\) are the stretch factors: \(W v_i = \sigma_i u_i\), the rose arrows. In the left panel the input axes are stretched by 1.67 and 0.75.
The rank of \(W\) is the number of singular values that are not zero: the number of independent directions the matrix can write into. In the right panel \(\sigma_2 = 0\), and the circle collapses into a segment. Whatever the input, the output lies on one line, and pairs of points that differ only along \(v_2\) land on the same spot.
The rank is also the dimension of the space spanned by the columns of \(W\), and, less obviously, of the space spanned by its rows. The SVD shows why the two agree: the columns are combinations of \(u_1, \dots, u_r\) and the rows are combinations of \(v_1, \dots, v_r\), the same number \(r\) of vectors in both cases.
The middle panel matters most for what follows. Its rank is 2, but \(\sigma_2 = 0.03\): it is a rank-one map plus a correction too small to see.
Rank is a cliff, singular values are a slope. Matrices that come out of training are almost never exactly low-rank, but they are often close to it, and the singular values say how close.
Rank one: read one direction, write one direction
The simplest nonzero matrix is the product of a column and a row, \(u v^\top\). Applied to \(x\) it gives
\[u v^\top x = u \, (v^\top x) .\]It measures \(x\) along one direction, \(v\) (the dot product \(v^\top x\) is a single number), and writes that number along another direction, \(u\). Everything in \(x\) perpendicular to \(v\) is ignored; nothing comes out that does not point along \(u\).
A matrix of rank \(r\) is a sum of \(r\) such read–write pairs. The SVD writes every matrix as such a sum, with the pairs perpendicular to each other and sorted by strength.
A product \(BA\), with \(B\) of shape \(m \times r\) and \(A\) of shape \(r \times n\), is the same thing in different clothes: \(BAx = B(Ax)\), so \(A\) reads \(r\) numbers out of \(x\) and \(B\) writes each of them along one of its \(r\) columns. Hence the inequality that LoRA rests on:
\[\operatorname{rank}(BA) \le \min\big(\operatorname{rank}(B), \operatorname{rank}(A)\big) \le r .\]Every column of \(BA\) is a combination of the columns of \(B\), so there cannot be more independent ones than \(B\) has; every row of \(BA\) is a combination of the rows of \(A\), the same argument. Storing \(B\) and \(A\) takes \(r(m + n)\) numbers instead of \(mn\).
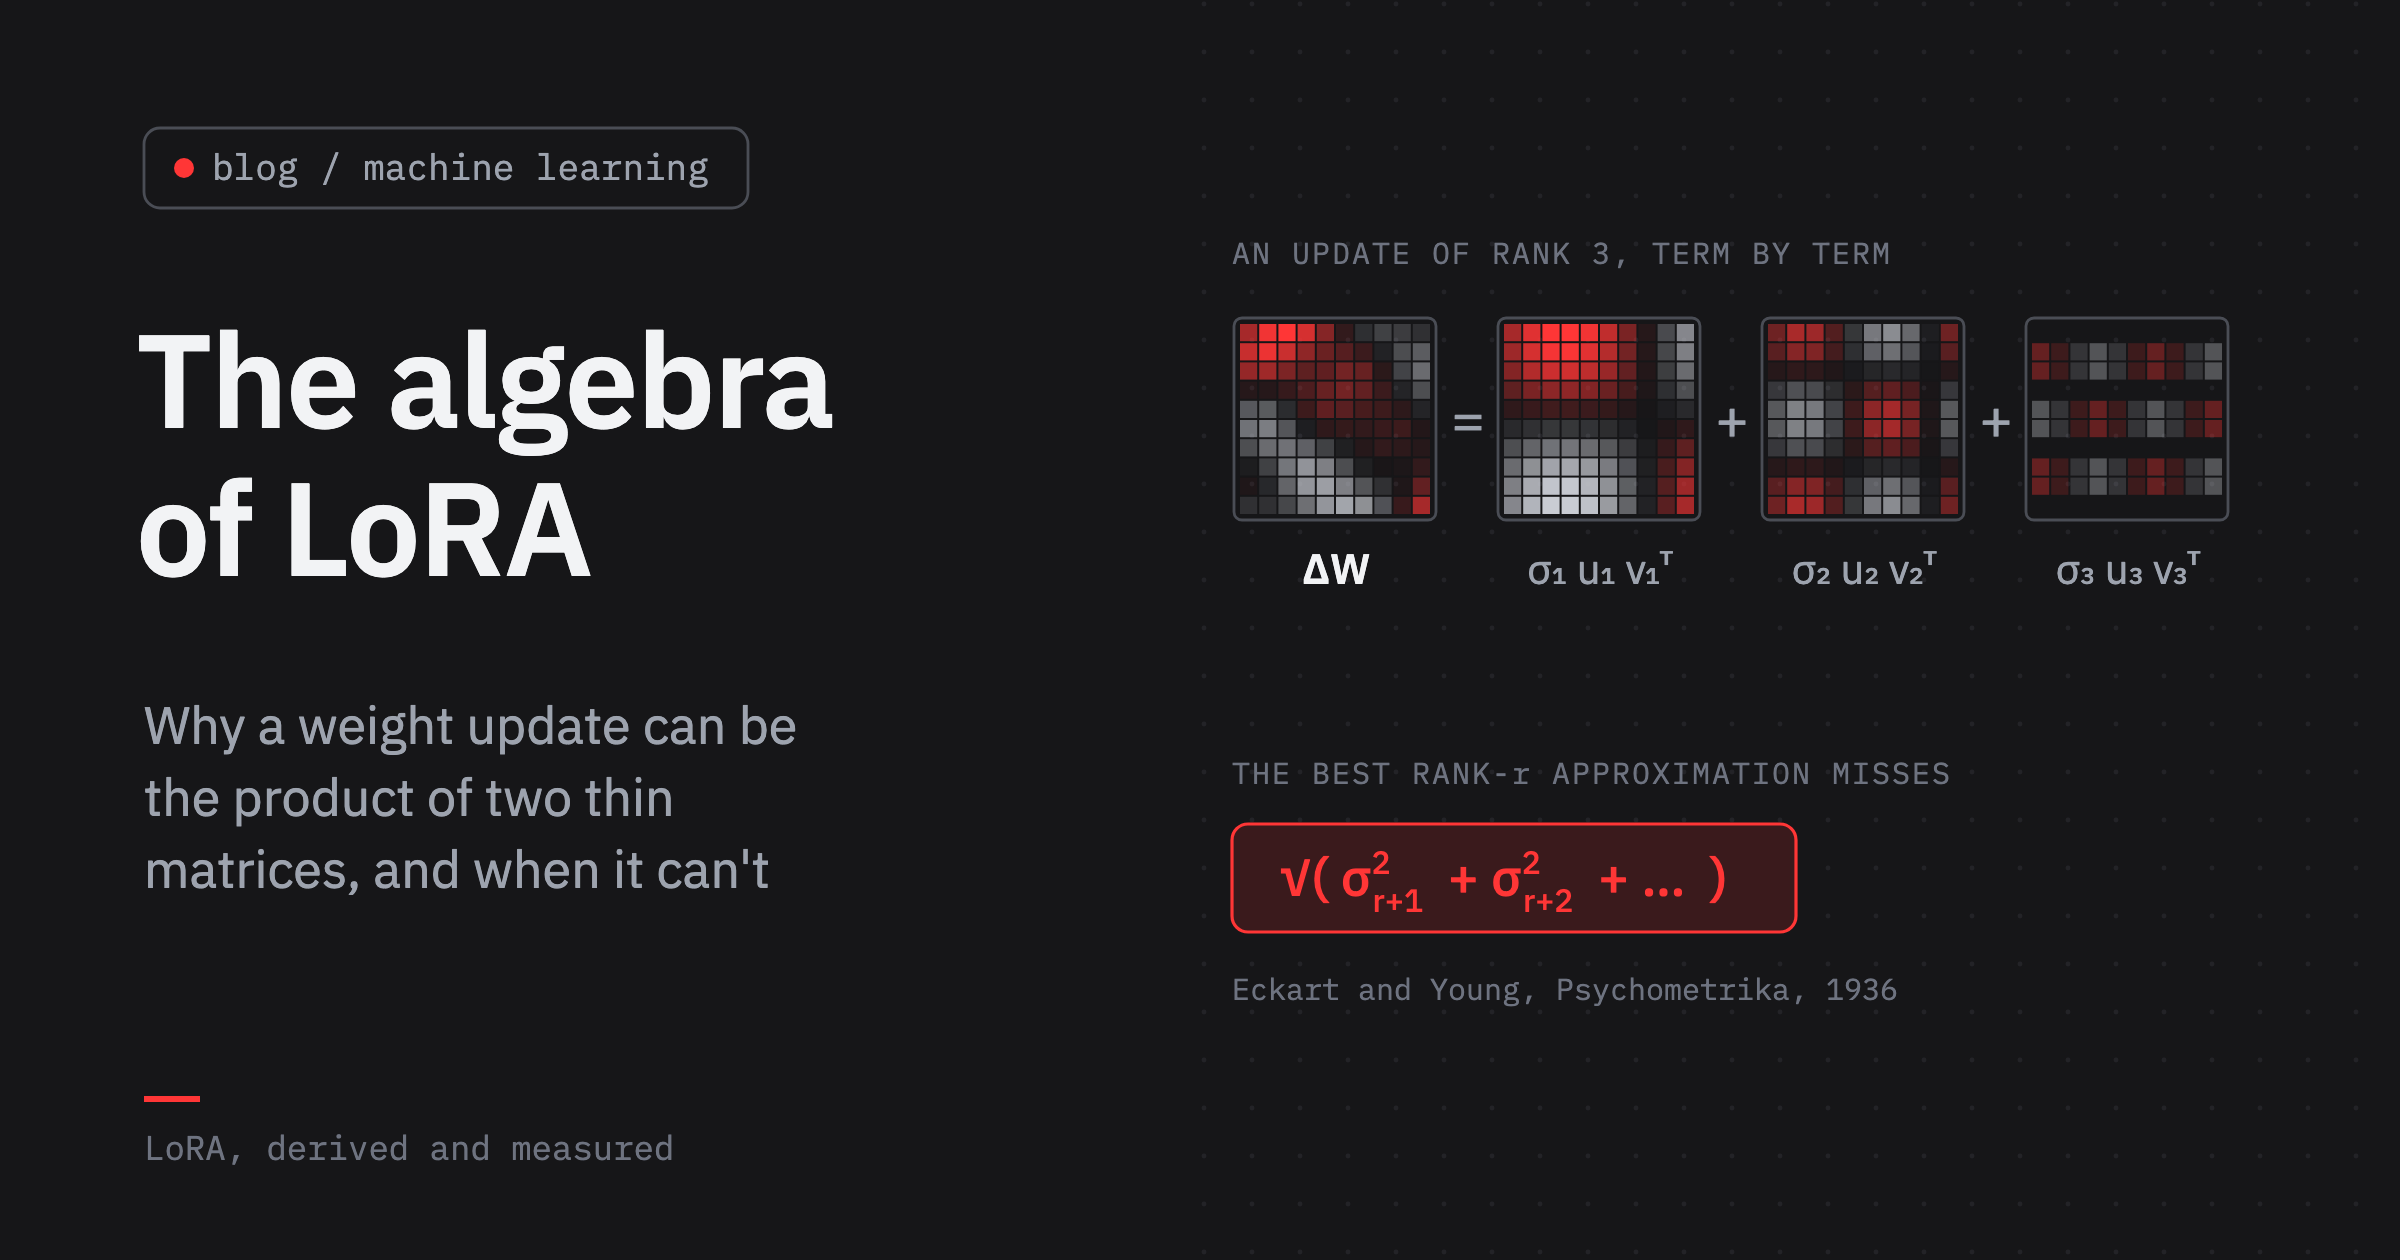
To see what a sum of rank-one layers looks like, take a matrix that is easy to look at: a grayscale photograph, 512 by 512 numbers between 0 and 1. Here it is rebuilt from the first \(k\) terms of its SVD:
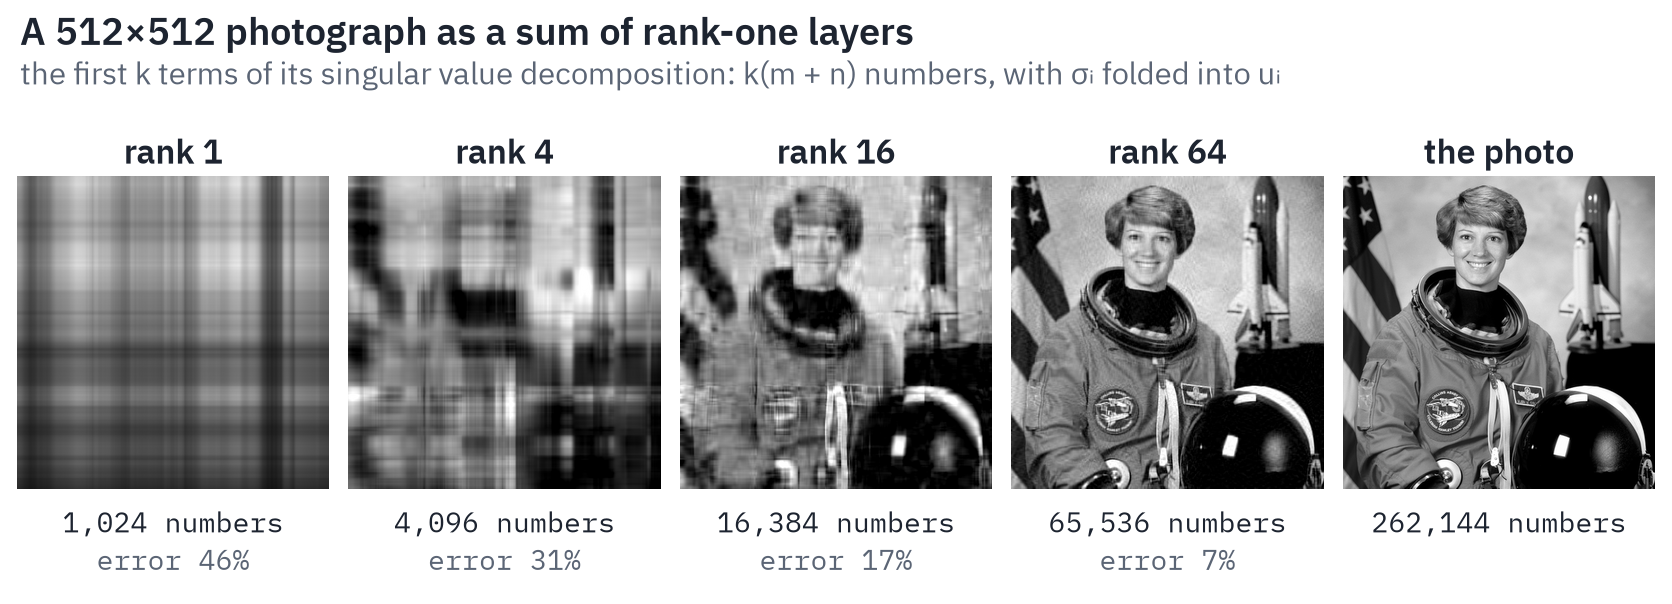
Rank 1 is a plaid: one pattern of columns times one pattern of rows, which is all a single read–write pair can draw. It still holds 79% of the photo’s “energy”, \(\sum_i \sigma_i^2\), mostly the average brightness. Each further term adds one more pair.
By rank 16 there is a face, and at rank 64, stored in a quarter of the numbers, the error is 7%.
The best you can do with r directions
Is cutting the SVD after \(k\) terms the best possible rank-\(k\) approximation, or just a convenient one? It is the best.
The theorem carries the names of Carl Eckart and Gale Young, who proved it for matrices in 1936, in the first volume of Psychometrika, a journal of psychological measurement: they needed it to approximate tables of test scores by a few underlying factors[4].
As G. W. Stewart points out in a history of the SVD, they had rediscovered a result Erhard Schmidt published in 1907 for integral equations[5].
For a matrix \(M\) with singular values \(\sigma_1 \ge \sigma_2 \ge \dots\) and its truncation \(M_k = \sum_{i \le k} \sigma_i u_i v_i^\top\),
\[\min_{\operatorname{rank}(X) \le k} \lVert M - X \rVert_F = \lVert M - M_k \rVert_F = \sqrt{\sigma_{k+1}^2 + \sigma_{k+2}^2 + \dots + \sigma_{\min(m,n)}^2} ,\]where \(\lVert \cdot \rVert_F\), the Frobenius norm, is the square root of the sum of the squares of all entries. Leon Mirsky extended the theorem in 1960 to every norm that does not change when the matrix is rotated[6].
In the spectral norm, the largest stretch a matrix applies to any unit vector, the smallest error is simply \(\sigma_{k+1}\).
Why squares under a square root? Because the rank-one layers are perpendicular to each other, as matrices. The inner product of two matrices, entry by entry, is \(\langle u_i v_i^\top, u_j v_j^\top \rangle = (u_i^\top u_j)(v_i^\top v_j)\), which is 0 for \(i \ne j\) and 1 for \(i = j\).
So Pythagoras applies: \(\lVert M \rVert_F^2 = \sum_i \sigma_i^2\), and dropping some layers leaves an error whose square is the sum of the squares of what was dropped.
The squares matter. The plain sum \(\sigma_{k+1} + \sigma_{k+2} + \dots\) is the error in another norm, the nuclear norm, and as a Frobenius error it is far too big: for the photograph at \(k = 16\) it gives 509, almost twice the size of the whole photograph, \(\lVert M \rVert_F = 272\), while the true error is 45.
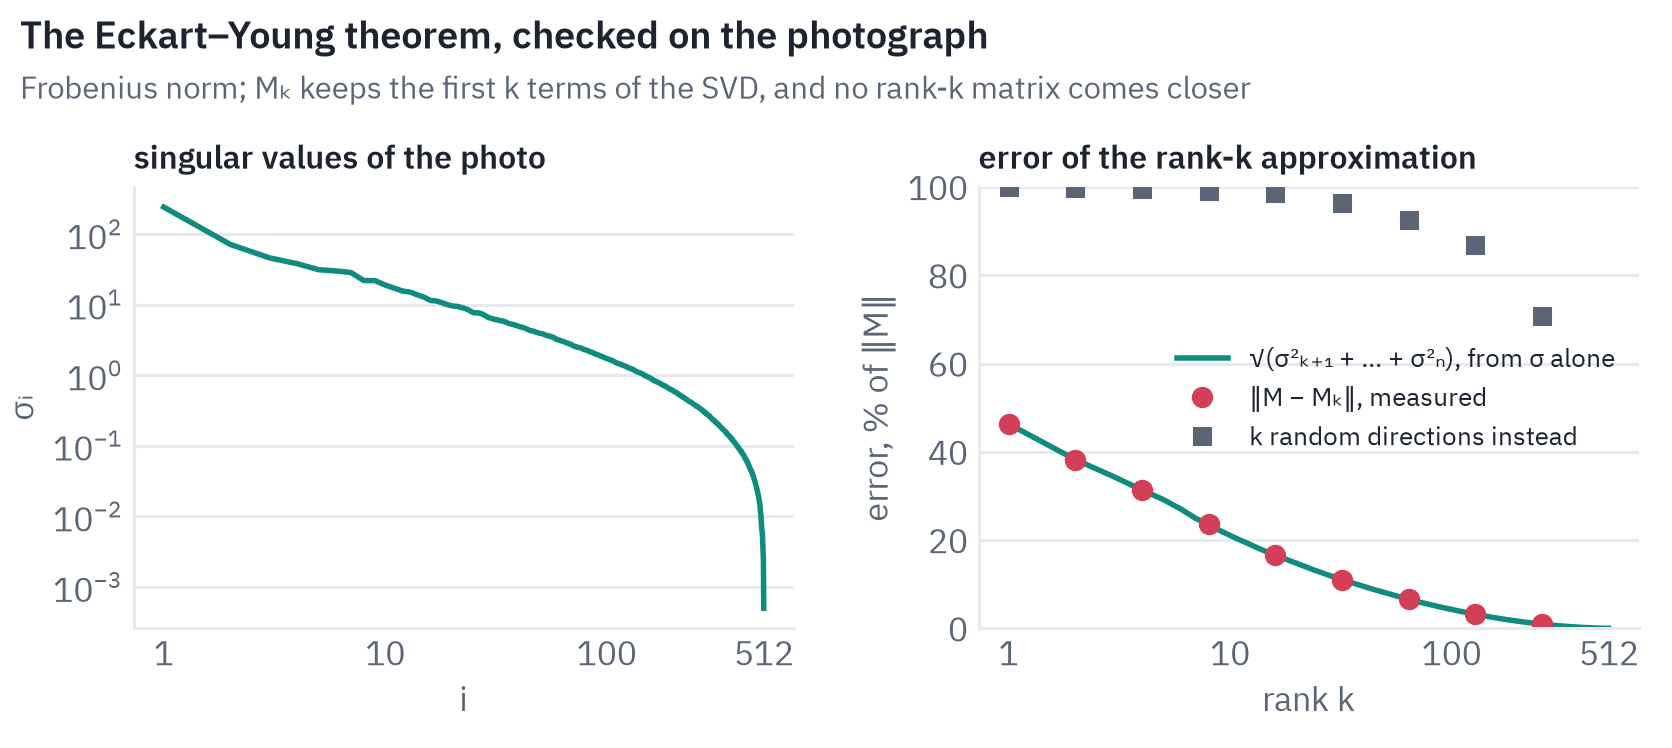
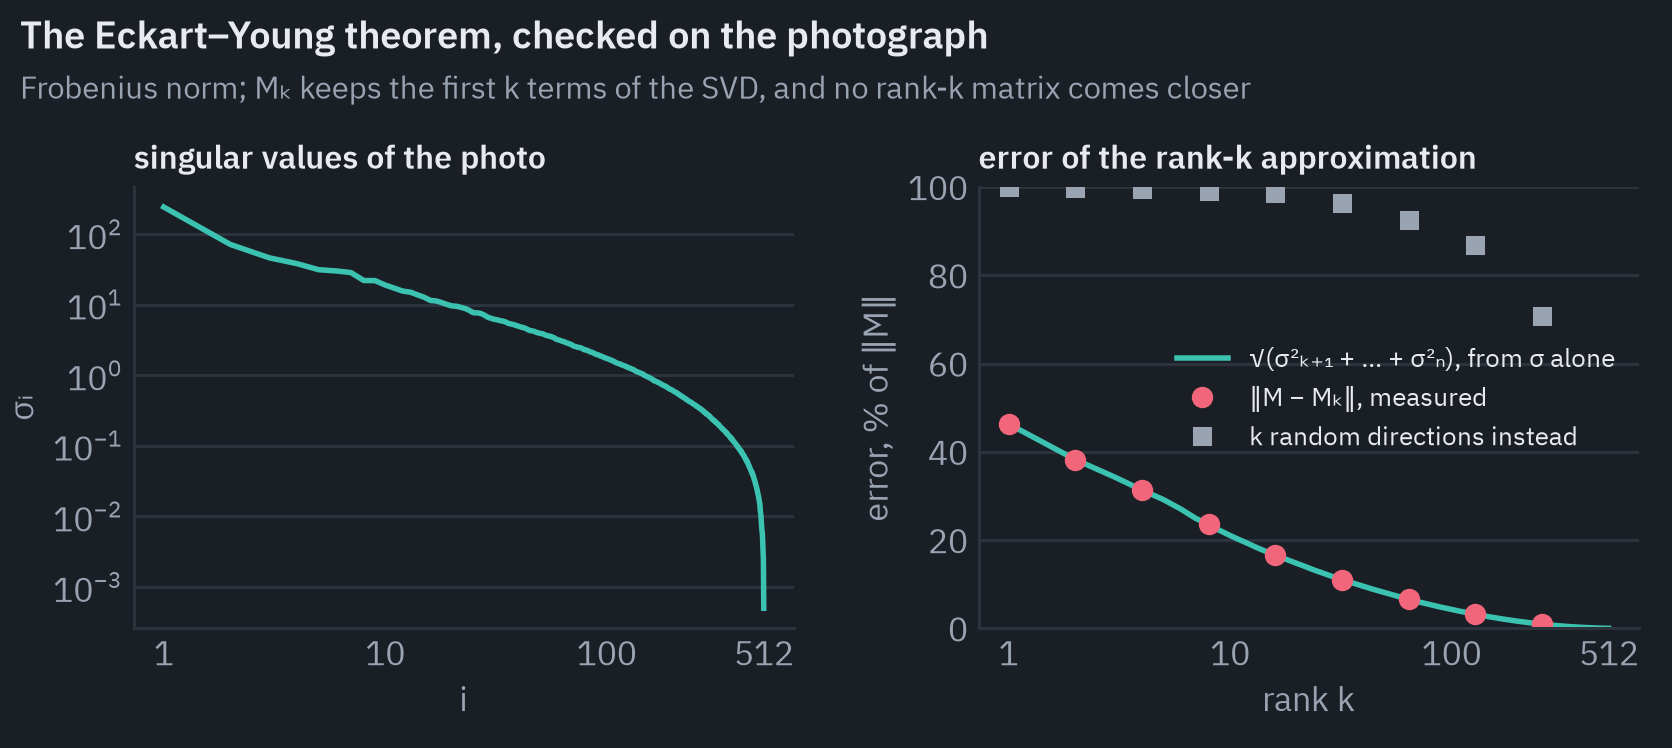
The dots are errors measured by subtracting \(M_k\) from the photograph; the line is computed from the singular values alone, without looking at the approximation. They coincide, as the theorem says. The squares show what is lost by choosing the directions badly: keep 64 random directions instead of the best 64, and the error is 93%, not 7%.
Key point
If the change a task needs, \(\Delta W\), has singular values that fall quickly, a matrix of rank \(r\) can hold most of it, and the theorem says exactly how much is missed. That is the whole linear-algebra case for LoRA. Whether real updates have quickly falling singular values is a question about training, which linear algebra cannot answer.
LoRA’s bet
The bet has a history. In 2018 Chunyuan Li and colleagues trained networks while letting the optimizer move only inside a random low-dimensional slice of the parameter space.
They called the smallest dimension that still reached 90% of the full solution the problem’s intrinsic dimension, and found it far smaller than the number of parameters: a small fully connected network for MNIST with 199,210 weights needed 750[7].
In 2020 Armen Aghajanyan, Luke Zettlemoyer and Sonal Gupta did the same with fine-tuning. RoBERTa-Large, with 355 million parameters, reached 90% of its full fine-tuning result on the paraphrase task MRPC by training about 200 numbers in such a slice[8].
Edward Hu and colleagues turned this into a parameterization[1]. Their hypothesis, in their words: “the change in weights during model adaptation also has a low ‘intrinsic rank’”. So instead of training \(W\), freeze it and train a low-rank change to it:
\[W = W_0 + \Delta W = W_0 + \frac{\alpha}{r} B A, \qquad B \in \mathbb{R}^{m \times r}, \; A \in \mathbb{R}^{r \times n} .\]The saving depends on the shape. For a square \(n \times n\) matrix the full update has \(n^2\) numbers and the rank-\(r\) one \(2rn\), a ratio of \(n / 2r\):
| matrix | shape | full update | rank \(r\) | LoRA’s numbers | ratio |
|---|---|---|---|---|---|
| bert-base, query | 768 × 768 | 589,824 | 8 | 12,288 | 48× |
Llama 3 8B, q_proj | 4,096 × 4,096 | 16,777,216 | 16 | 131,072 | 128× |
| GPT-3 175B, \(W_q\) | 12,288 × 12,288 | 150,994,944 | 1 | 24,576 | 6,144× |
For the whole model the ratio is larger still, because LoRA usually touches only some matrices and everything else is frozen. Hu et al. report that on GPT-3 175B it cut the number of trainable parameters by 10,000 times, and the GPU memory needed for training by 3 times.
One layer, forward and back
Here is what happens inside one adapted layer, written with \(\gamma = \alpha / r\) for the scale:
\[h = W_0 x + \gamma \, B (A x) .\]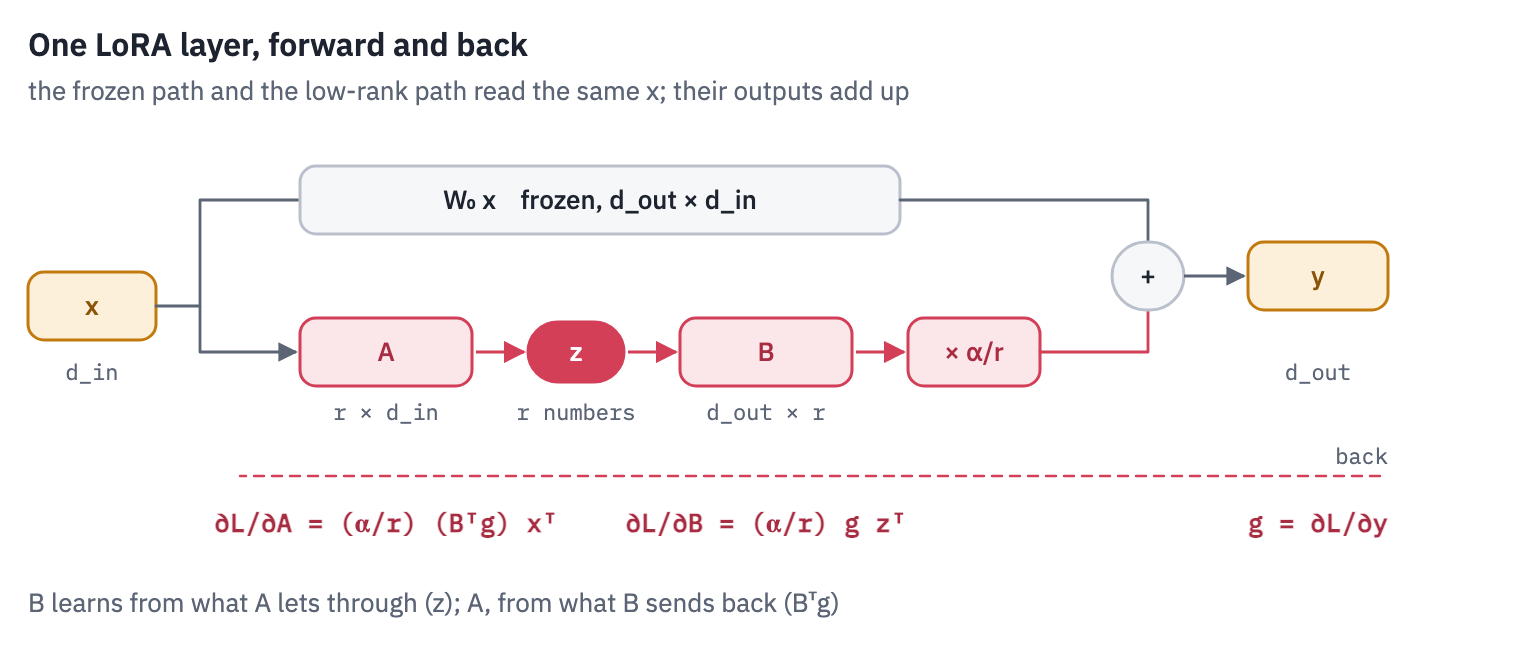
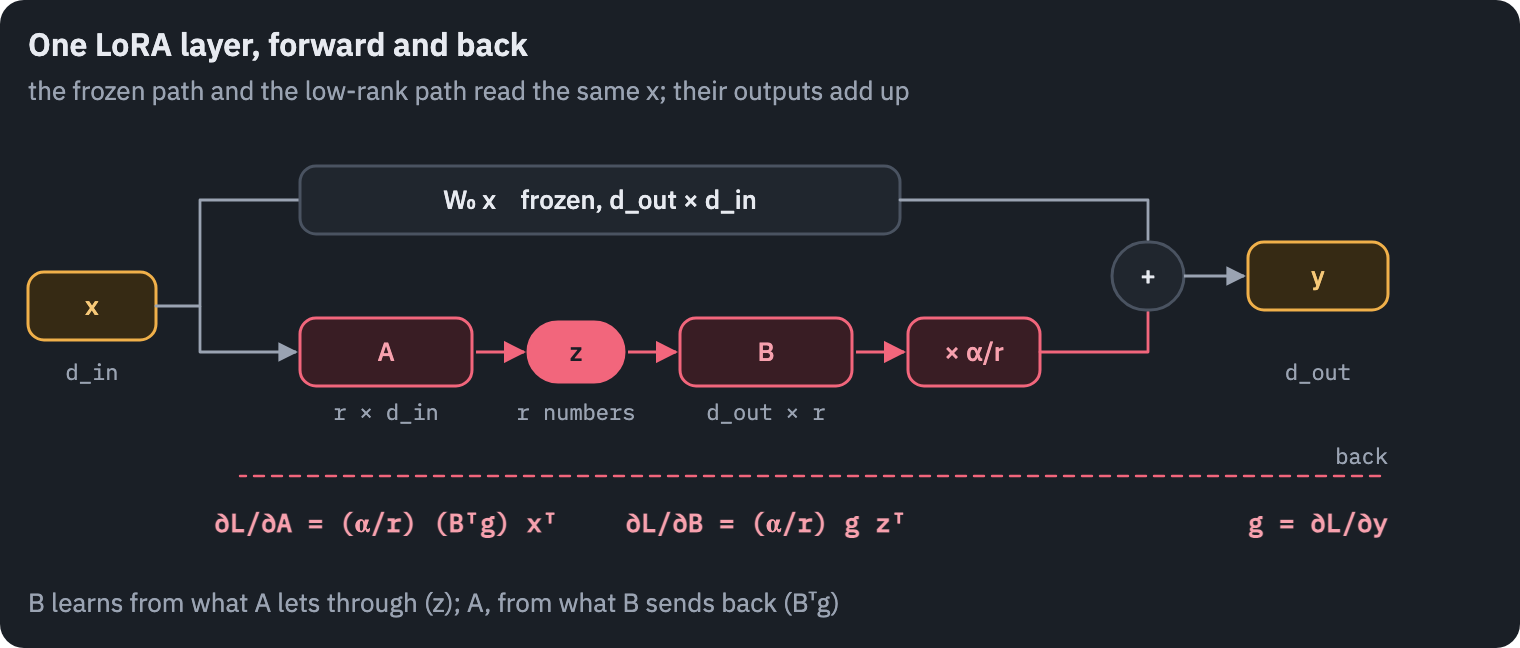
Training needs the gradients of the loss \(L\) with respect to \(B\) and \(A\). Write \(g = \partial L / \partial h\) for the gradient that arrives at the layer’s output, and \(z = Ax\) for the \(r\) numbers in the middle. Then \(h\) depends on \(B\) through \(\gamma B z\), and on \(A\) through \(z\), and the chain rule gives
\[\frac{\partial L}{\partial B} = \gamma \, g z^\top = \gamma \, g x^\top A^\top , \qquad \frac{\partial L}{\partial A} = \gamma \, B^\top g \, x^\top .\]Summed over a batch, \(\sum g x^\top\) is exactly \(G = \partial L / \partial W\), the gradient that full fine-tuning would use to update \(W\). So
\[\nabla_B L = \gamma \, G A^\top , \qquad \nabla_A L = \gamma \, B^\top G .\]Key point
LoRA computes the same gradient \(G\) as full fine-tuning and lets each factor see it through the other: \(B\) sees \(G\) through the \(r\) directions \(A\) reads, \(A\) sees it through the \(r\) directions \(B\) writes.
Formulas like these are easy to get wrong by a transpose, so here they are checked against PyTorch’s autograd:
import torch

torch.manual_seed(0)
d_out, d_in, r, gamma = 6, 5, 2, 0.5
W0 = torch.randn(d_out, d_in)
A = torch.randn(r, d_in, requires_grad=True)
B = torch.randn(d_out, r, requires_grad=True)  # not zero here, so that both gradients are nonzero
x = torch.randn(d_in, 4)  # four inputs, as columns

h = W0 @ x + gamma * B @ (A @ x)
loss = h.square().sum() / 2  # any loss would do; for this one dL/dh = h
loss.backward()

G = h.detach() @ x.T  # dL/dW: the gradient full fine-tuning would get
print(torch.allclose(B.grad, gamma * G @ A.T), torch.allclose(A.grad, gamma * B.T @ G))
True True
Why one factor starts at zero
Hu et al. start \(A\) random and \(B\) at zero. The formulas explain both halves of that choice.
\(B = 0\) makes \(\Delta W = BA = 0\), so training starts exactly from the pretrained model: no noise is added to a network that already works.
Why not set \(A = 0\) as well? Because then both gradients vanish, \(\nabla_B L = \gamma G A^\top = 0\) and \(\nabla_A L = \gamma B^\top G = 0\), and the factors never move: zero is a stationary point of the product.
With one factor random, the other one gets a gradient. At the first step that is \(B\): since \(B = 0\), \(\nabla_A L = 0\), so \(A\) stays where it was and only \(B\) moves.
The reverse, \(B\) random and \(A\) at zero, would also start at \(\Delta W = 0\) and also train; it is just not what the paper or the libraries do. The paper draws \(A\) from a Gaussian; Microsoft’s loralib and Hugging Face’s peft use a Kaiming-uniform distribution.
The first step, and why the scale matters
Follow the first steps of training with plain gradient descent at learning rate \(\eta\). On step one only \(B\) moves, to \(B_1 = -\eta \gamma \, G A_0^\top\), and the update becomes
\[\Delta W_1 = \gamma B_1 A_0 = -\eta \gamma^2 \, G A_0^\top A_0 .\]Full fine-tuning would have taken the step \(-\eta G\). LoRA takes the same gradient and multiplies it, on the right, by \(A_0^\top A_0\): a square \(n \times n\) matrix of rank \(r\).
What does that matrix look like? Its entry \((j, k)\) is \(\sum_{i=1}^{r} a_{ij} a_{ik}\), a sum of \(r\) products of entries of \(A_0\).
If the entries are independent with mean 0 and variance \(\sigma^2\), the diagonal entries are sums of \(r\) squares, \(r\sigma^2\) on average, and the off-diagonal ones are sums of products of independent numbers, 0 on average. So
\[\mathbb{E}\big[A_0^\top A_0\big] = r \sigma^2 I , \qquad \mathbb{E}\big[\Delta W_1\big] = -\eta \, \gamma^2 r \sigma^2 \, G .\]On average, the first LoRA step is the full fine-tuning step, shrunk or stretched by the factor \(\gamma^2 r \sigma^2\). One draw of \(A_0\) is not its average, though:
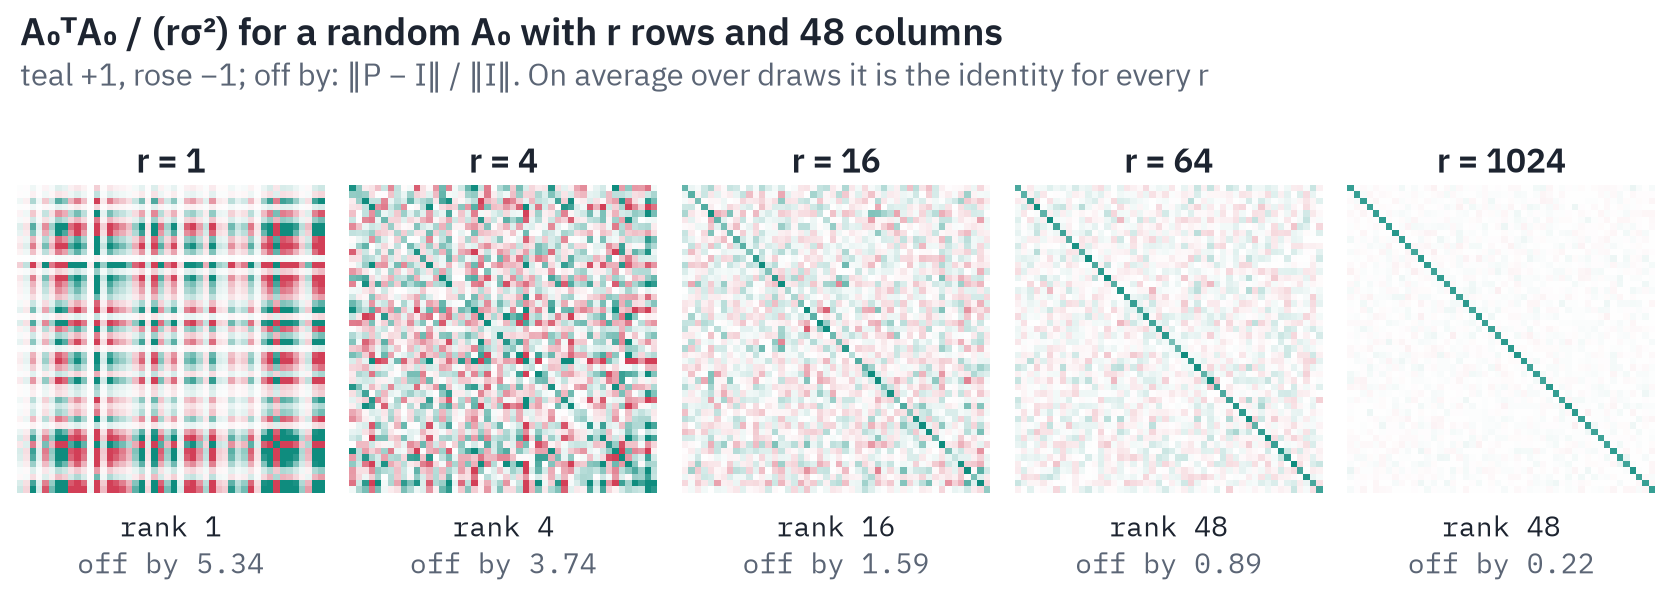
With \(r\) rows, \(A_0^\top A_0\) keeps the components of the gradient along \(r\) random directions and drops the rest; its fluctuations around the identity shrink like \(1/\sqrt{r}\). In a 768-dimensional layer with \(r = 8\), the first step sees the full gradient through eight random windows.
Later steps are not so simple, because \(B\) is no longer zero and \(A\) starts to move too. To first order in \(\eta\), a general step changes the update by
\[\Delta W_{t+1} - \Delta W_t \approx -\eta \gamma^2 \left( G A^\top A + B B^\top G \right) ,\]the full gradient, filtered on the right through the directions \(A\) reads and on the left through the directions \(B\) writes.
The scale
Now look at the size of that first step: it is proportional to \(\gamma^2 r\). With the paper’s \(\gamma = \alpha / r\) it is \(\alpha^2 / r\), so doubling the rank halves the effective learning rate, and a rank-256 adapter starts 256 times slower than a rank-1 one.
This is the argument of Damjan Kalajdzievski’s rsLoRA[2]. The paper proves, for gradient descent and in the limit of large \(r\), that the only scale under which an adapter’s outputs and gradients neither blow up nor die out as the rank grows is \(\gamma = \alpha / \sqrt{r}\), which keeps \(\gamma^2 r = \alpha^2\) for every rank.
And it draws the conclusion that brings us back to the start. The \(\alpha / r\) rule “slows the learning such that LoRA fine-tuning using larger ranks performs no different than that with very small ranks”, and this “may have led the authors of (Hu et al., 2022) to inaccurately conclude that very low ranks (e.g. 4,8,16) ‘suffice’”.
a higher ranka smaller scale α/ra slower starthigher ranks look no better
Almost nobody trains LoRA with plain gradient descent, though. The usual optimizer is Adam, which divides every coordinate’s gradient by a running estimate of its size, so that each parameter moves by about \(\eta\) per step whatever the scale of its gradient. That changes the arithmetic.
Now every entry of \(B\) moves by about \(\eta\), and every entry of \(\Delta W = \gamma B A\) is a sum of \(r\) such moves multiplied by entries of \(A\), with signs that mostly do not line up.
A sum of \(r\) terms of random sign grows like \(\sqrt{r}\). So under Adam the size of the update grows like \(\gamma \sqrt{r}\) instead of \(\gamma^2 r\), and the conclusion is the same: \(\alpha / r\) makes it shrink like \(1/\sqrt{r}\), \(\alpha / \sqrt{r}\) keeps it constant.
It also explains a remark of Hu et al.: “When optimizing with Adam, tuning α is roughly the same as tuning the learning rate if we scale the initialization appropriately.” Under Adam, \(\gamma\) multiplies the size of every step, just as \(\eta\) does.
Measuring it
All of this can be checked on a real model. I fine-tuned bert-base-uncased on SST-2, sentences from film reviews labelled positive or negative[9], with LoRA on the query and value projections of all 12 layers. For reference, full fine-tuning of all 110 million parameters reaches 91.4%.
The runs differ only in the algebra:
- the rank, from 1 to 256;
- the scale, \(\alpha / r\) with \(\alpha = 16\) as in the paper, or \(\alpha' / \sqrt{r}\) with \(\alpha'\) chosen so that the two agree at \(r = 8\);
- which factor learns, and how fast.
The training setup: data, optimizer, seeds and the code
The setting is that of the adapters post: 10,000 training sentences, three epochs, AdamW at a learning rate of \(5 \times 10^{-4}\), batches of 32, three seeds per configuration, accuracy on the 872 validation sentences.
The 48 runs took 40 minutes of training on a Kaggle T4 (experiment.py).
Rank under the two scales
First, the size of the update, \(\lVert \Delta W \rVert_F\) averaged over the 24 adapted matrices, as training goes:
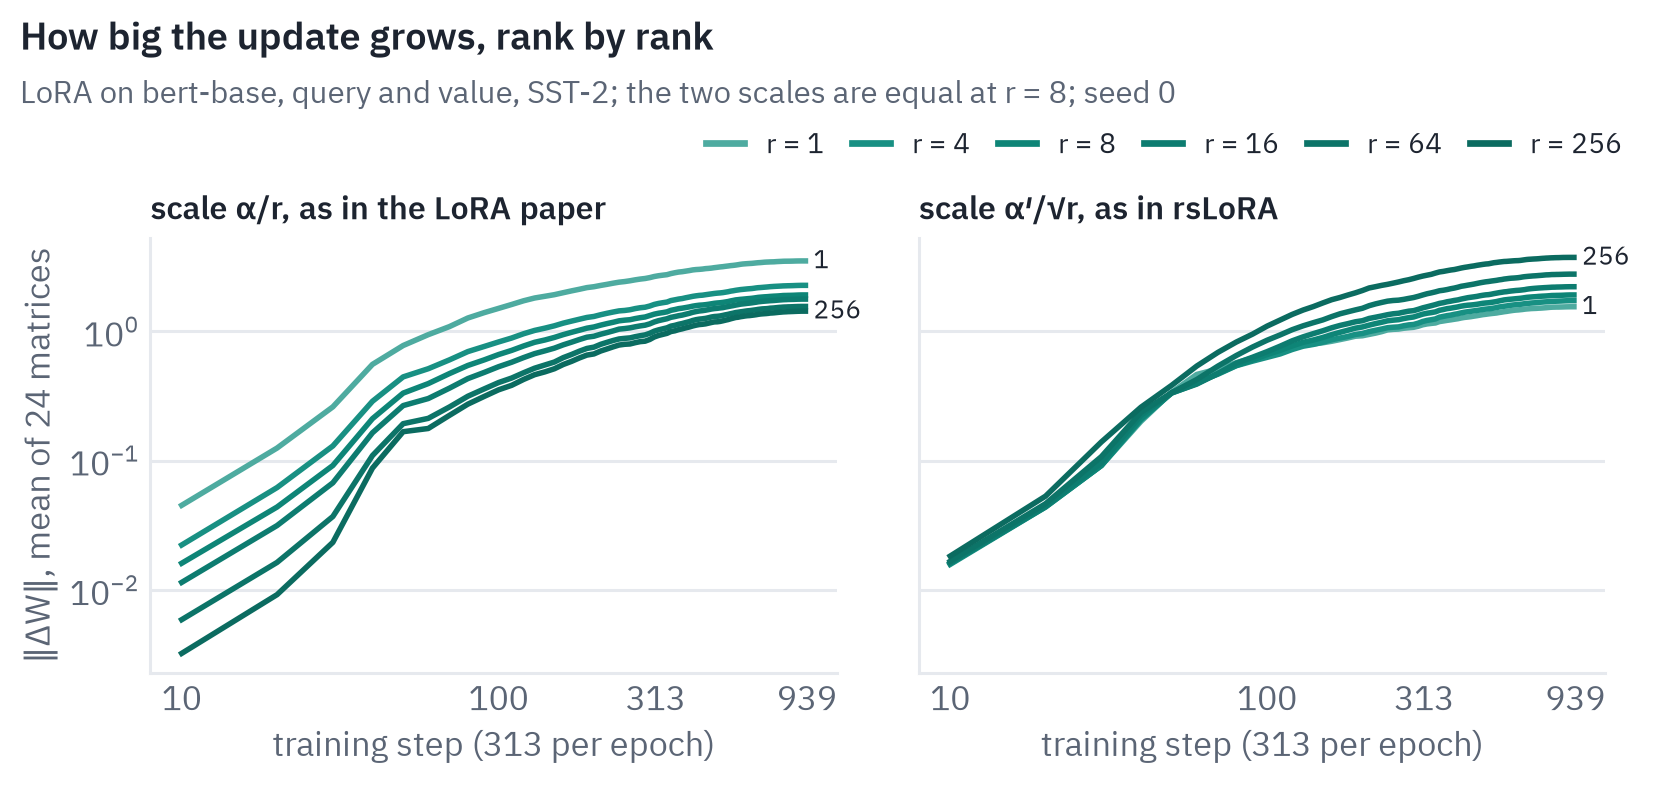
At step 10 the prediction holds almost to the digit. Under \(\alpha / r\) the update of rank 1 has size 0.045 and that of rank 256 has 0.003, fifteen times smaller; the \(\gamma \sqrt{r}\) rule predicts \(\sqrt{256} = 16\). Under \(\alpha' / \sqrt{r}\) all six ranks start between 0.016 and 0.018.
Later the two pictures turn upside down. Under \(\alpha / r\) the lowest rank stays ahead all the way; under \(\alpha' / \sqrt{r}\) the highest ranks pull ahead, because they have more directions to grow in. What does that do to learning?
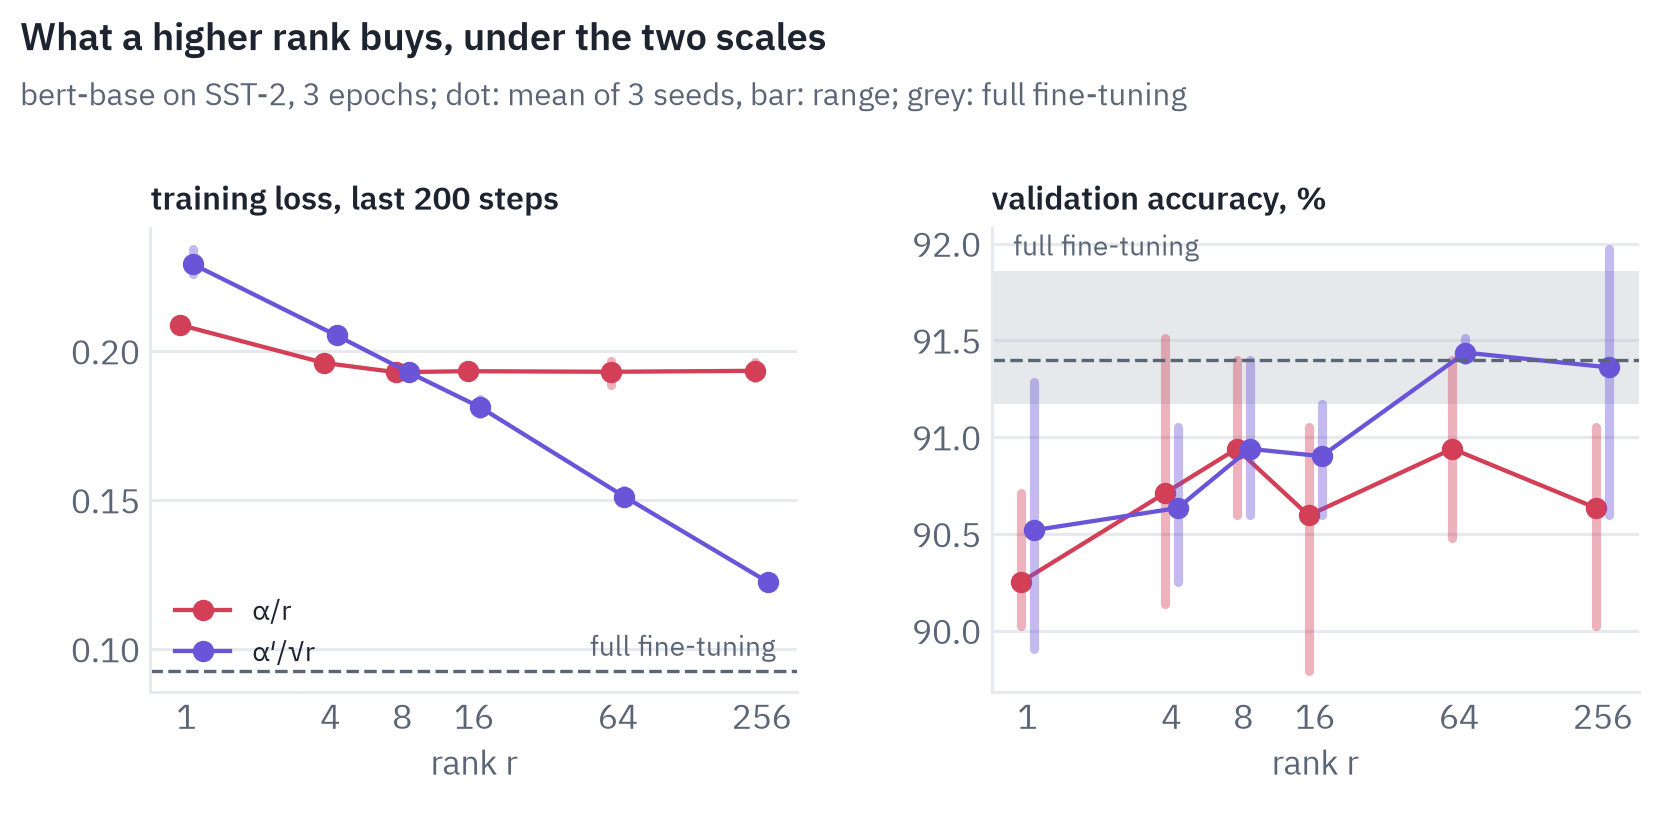
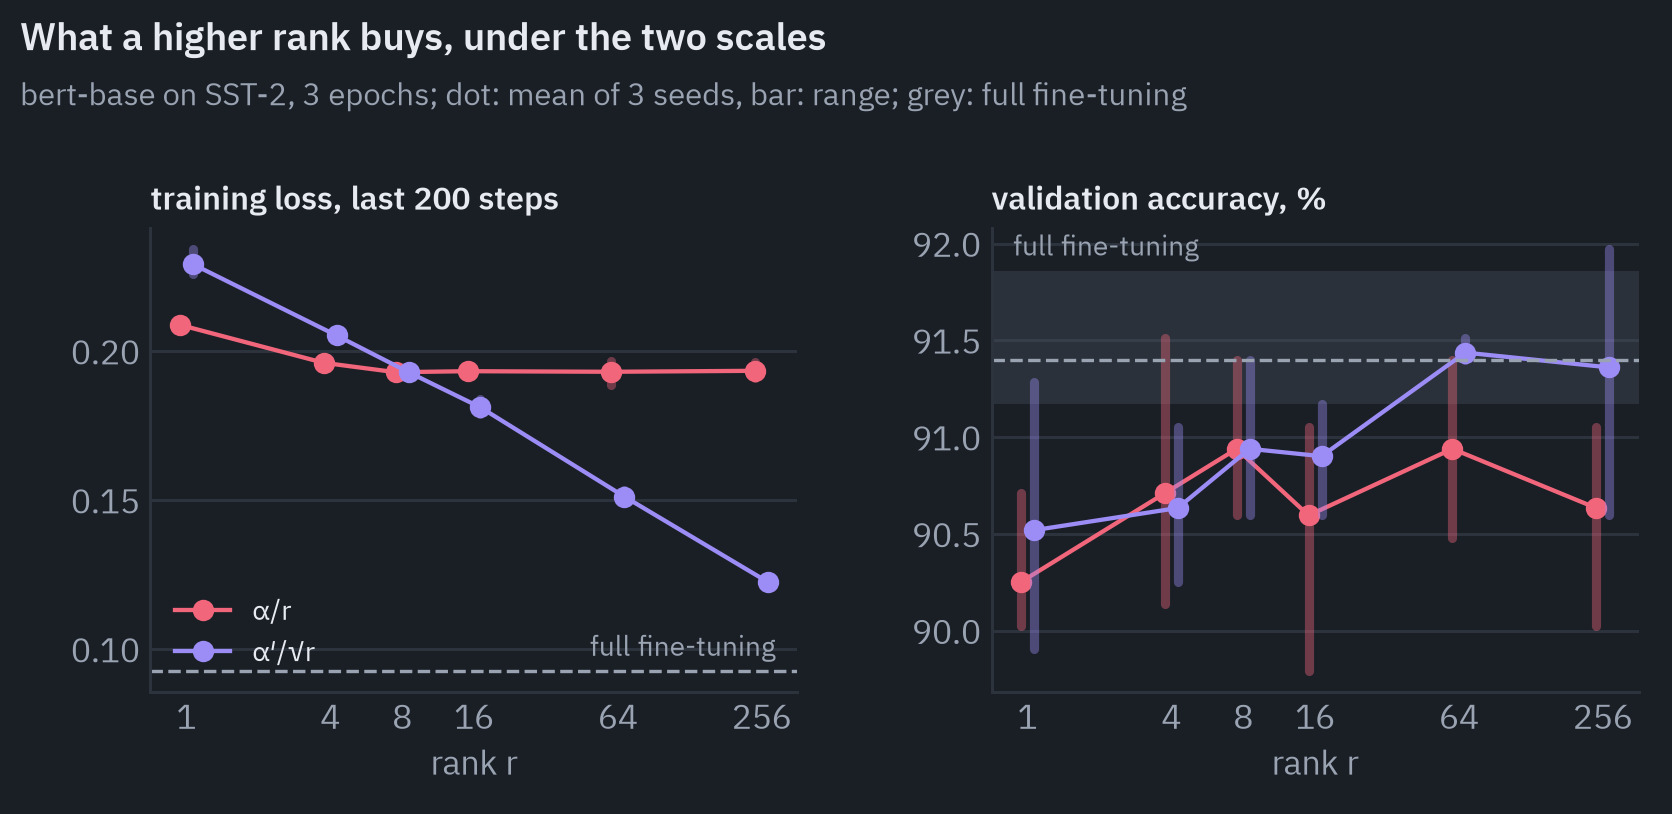
On the training set the two rules tell opposite stories. Under \(\alpha / r\) the loss at the end is the same for every rank from 4 to 256, 0.19: more rank buys nothing, the flat shape of Hu et al.’s table.
Under \(\alpha' / \sqrt{r}\) the loss keeps falling with rank, from 0.23 at \(r = 1\) to 0.12 at \(r = 256\): the extra directions are used.
On held-out sentences the effect is smaller, because SST-2 is easy for BERT and a few directions are enough to tell praise from complaint. Under \(\alpha / r\) accuracy stays between 90.3% and 90.9% at every rank, about half a point under full fine-tuning. Under \(\alpha' / \sqrt{r}\) it climbs to 91.4% at ranks 64 and 256, level with full fine-tuning.
The gap is small: three seeds per point, and a single validation sentence is worth 0.11%. But compared seed by seed at ranks 64 and 256, the rank-stabilized run is ahead five times out of six, and the sixth is a tie.
So both papers are right about different things. On this task a low rank does suffice, as Hu et al. found; and the \(\alpha / r\) rule does hide what higher ranks could add, as Kalajdzievski argued.
In practice
If you raise the rank, either switch the scale or raise \(\alpha\) with it.
In Hugging Face’s peft the corrected scale is one flag.
from peft import LoraConfig

config = LoraConfig(r=64, lora_alpha=16, target_modules=["query", "value"],
                    use_rslora=True)  # scale lora_alpha / sqrt(r) instead of lora_alpha / r
Two factors, two learning rates
The initialization treats the factors differently, and two later papers argue that training should too.
Jiacheng Zhu and colleagues found that “A extracts features from the input, while B uses these features to create the desired output”, and that “a random untrained A should perform nearly as well as a fine-tuned one”[10].
Soufiane Hayou, Nikhil Ghosh and Bin Yu showed that in very wide networks one learning rate cannot be right for both factors, and proposed LoRA+: give \(B\) a learning rate \(\lambda\) times that of \(A\)[11].
The best \(\lambda\) depends on the model, the task and the initialization. With LoRA’s standard start they found it around 4 to 8, and up to 16 with the factors’ roles swapped.
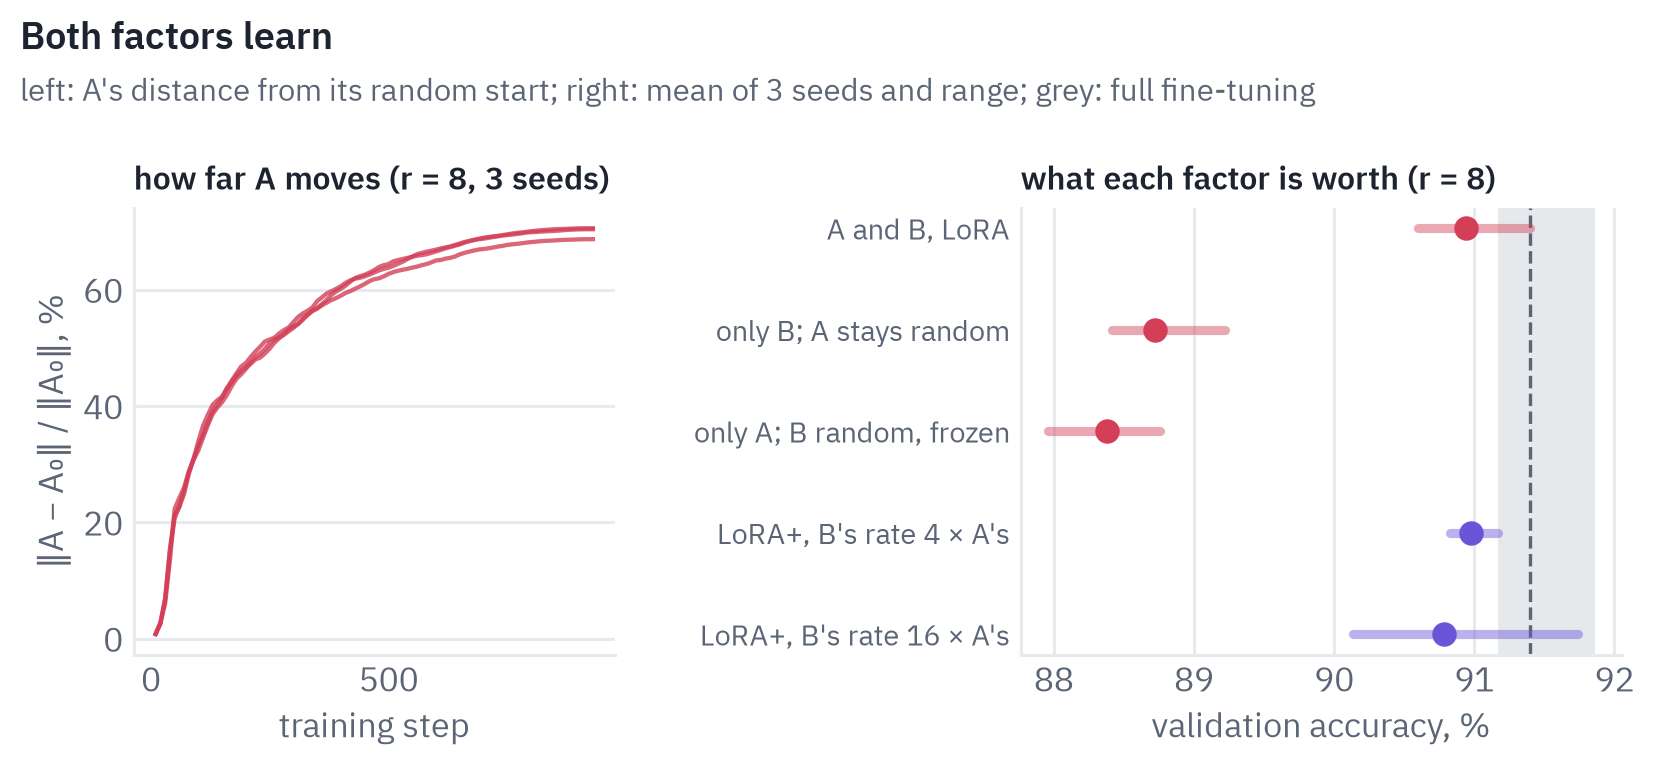
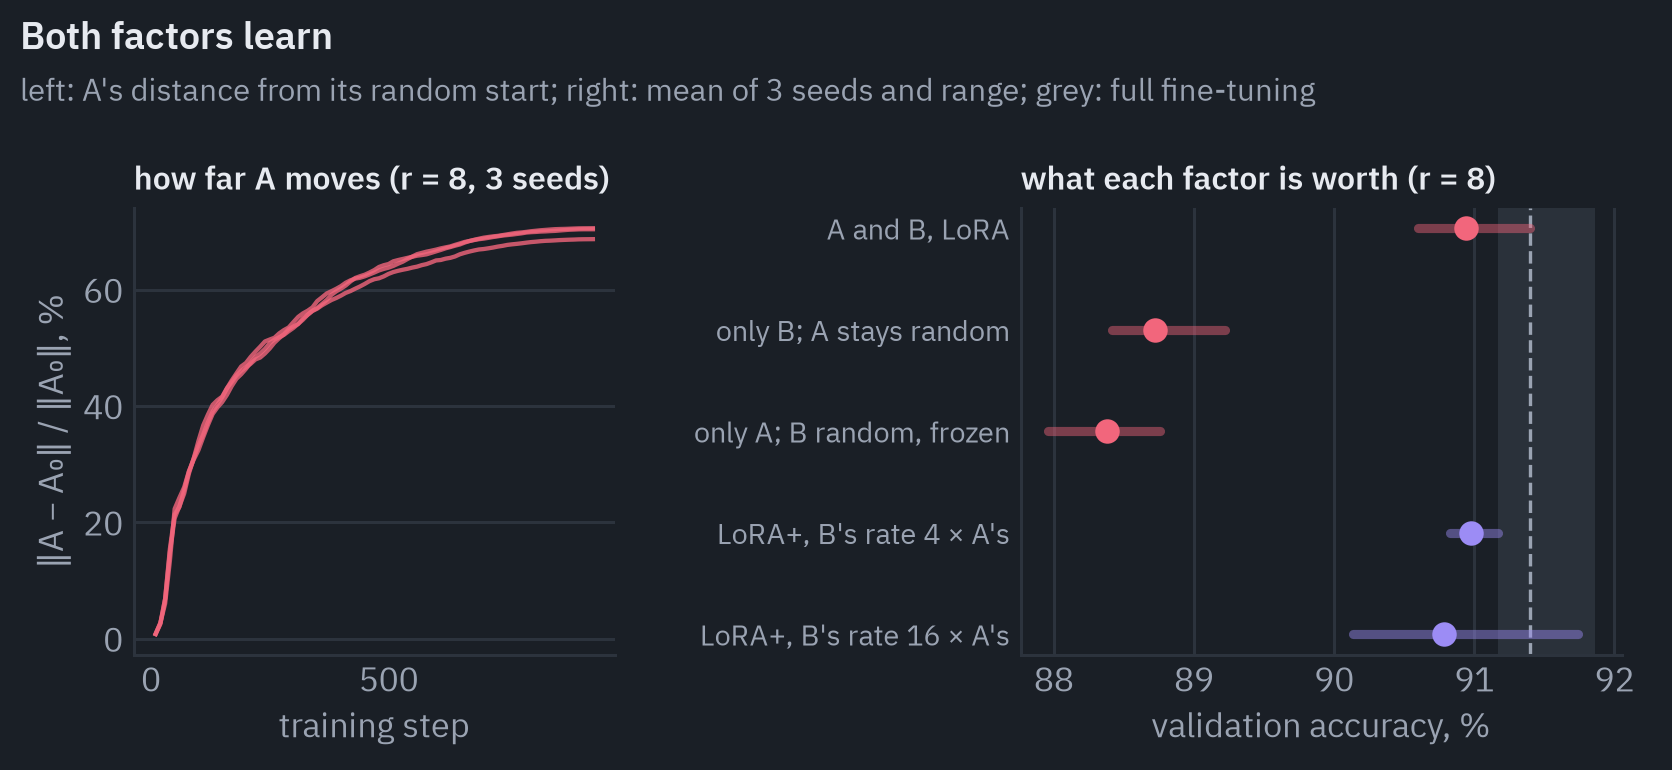
On BERT and SST-2 neither shortcut pays.
\(A\) does not stay near its random start: by the end of training it has moved by 70% of its initial size.
Freezing it costs 2.2 points (88.7% against 90.9%), with half as many trained numbers; freezing \(B\) and training \(A\) costs 2.6. The asymmetry Zhu et al. describe is there, but it is small next to the price of freezing either factor.
LoRA+ with \(\lambda = 4\) reaches 91.0% against 90.9%, and after the first epoch 90.1% against 89.9%; with \(\lambda = 16\) it is a little worse. Hayou et al. write that the benefits are larger “for ‘hard’ tasks such as MNLI … (compared to SST2 for instance)”, and this is SST-2.
What the update looks like
Hu et al. ended their paper with questions about \(\Delta W\) itself: does a higher rank find new directions or the same ones, and how does \(\Delta W\) relate to \(W\)? Both can be asked of BERT.
For the first, they compared the subspaces spanned by \(A\) in a rank-8 and a rank-64 run, with a measure that is 1 when one subspace contains the other and 0 when they are perpendicular:
\[\varphi(i, j) = \frac{\lVert U_i^\top U_j' \rVert_F^2}{\min(i, j)} ,\]where \(U_i\) holds the top \(i\) right singular vectors of one \(A\) and \(U_j'\) the top \(j\) of the other. In plain words, it is the average squared cosine between the two sets of directions.
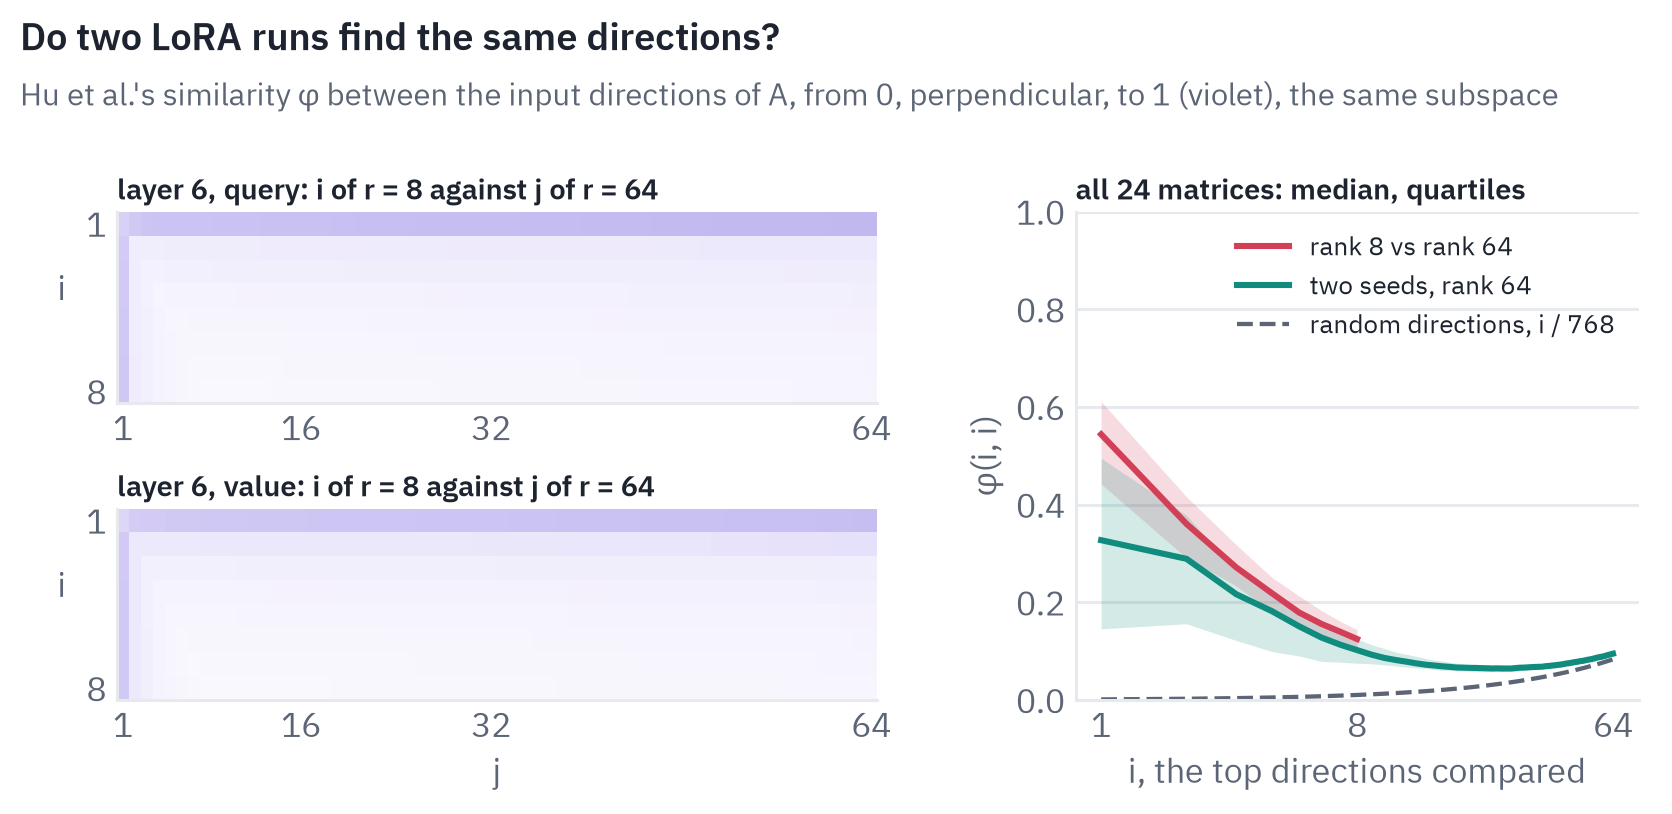
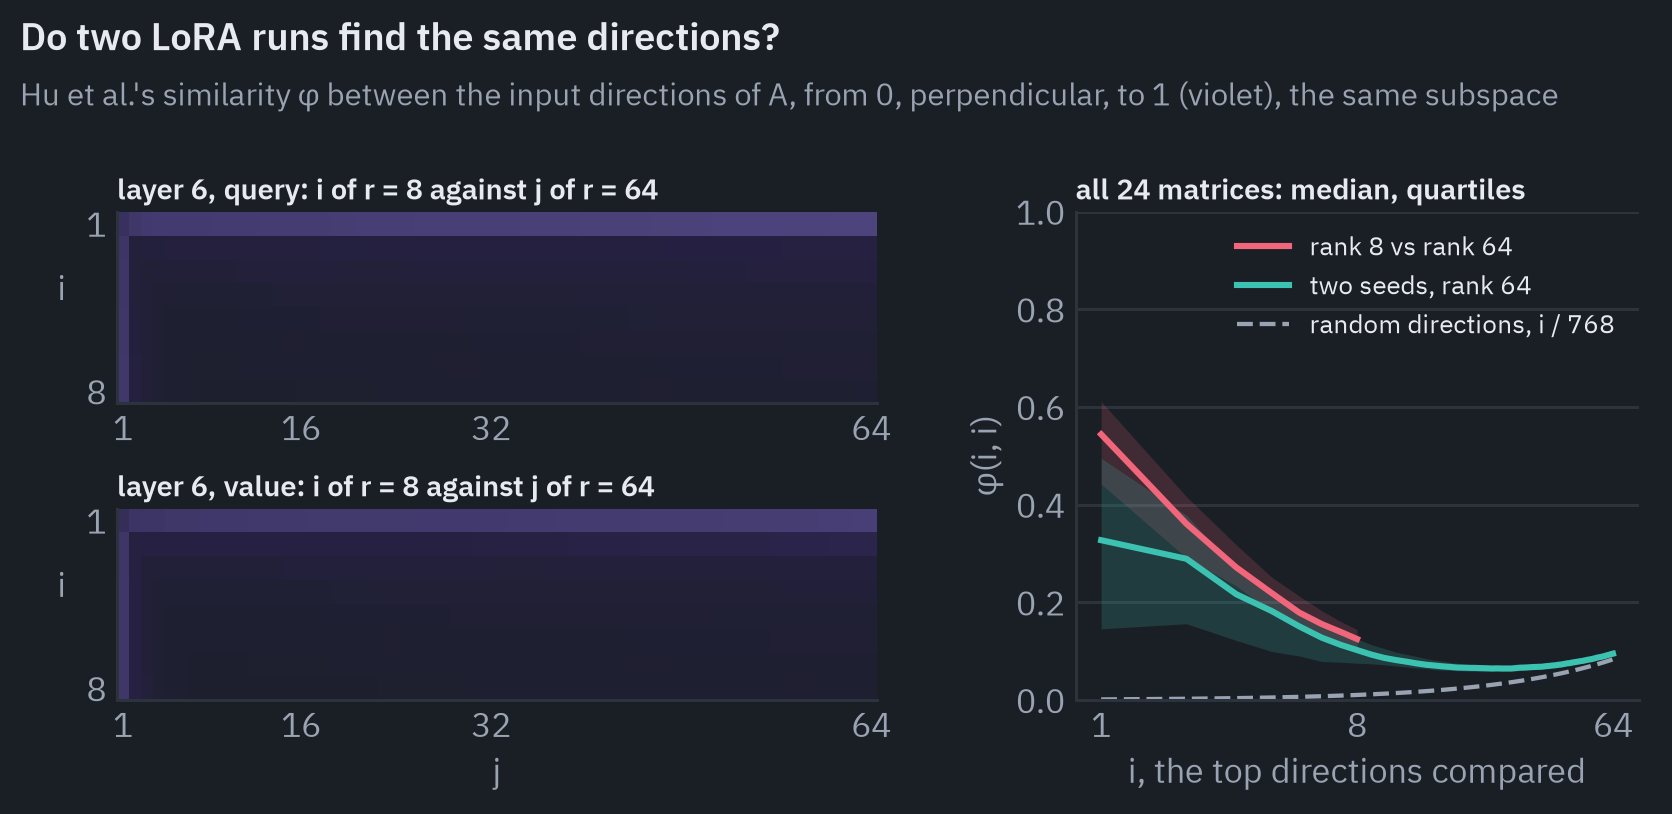
The result repeats theirs. The single strongest direction of the rank-8 run lies largely inside the rank-64 run: the median \(\varphi(1, 1)\) over the 24 matrices is 0.54, where Hu et al. report “> 0.5” for GPT-3.
The agreement fades quickly after it. By \(i = 8\) it is 0.13, more than ten times the 0.01 that random directions would give but far from 1. Two rank-64 runs with different seeds share less, 0.33 for the top direction.
Hu et al. read the pattern as a sign that the top directions carry the adaptation, while the others “potentially contain mostly random noises accumulated during training”.
For the second question, project \(W\) onto the update’s top \(r\) directions, \(\lVert U^\top W V \rVert_F\) with \(U, V\) the update’s singular vectors, and compare it with \(\lVert \Delta W \rVert_F\). Hu et al. call the ratio the amplification factor: a large one means the update makes a big change in directions where \(W\) itself is weak.
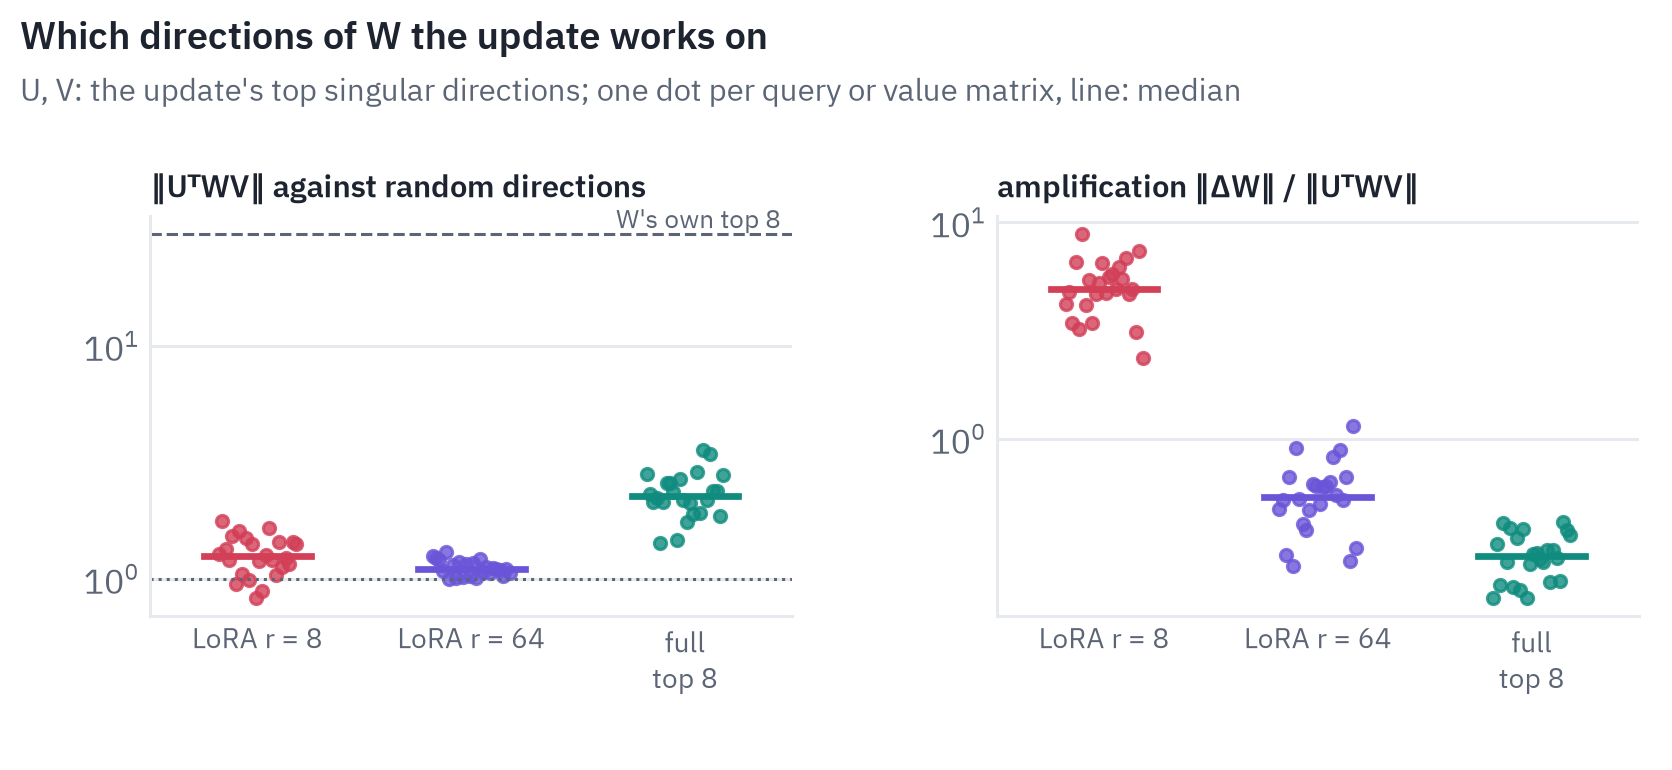
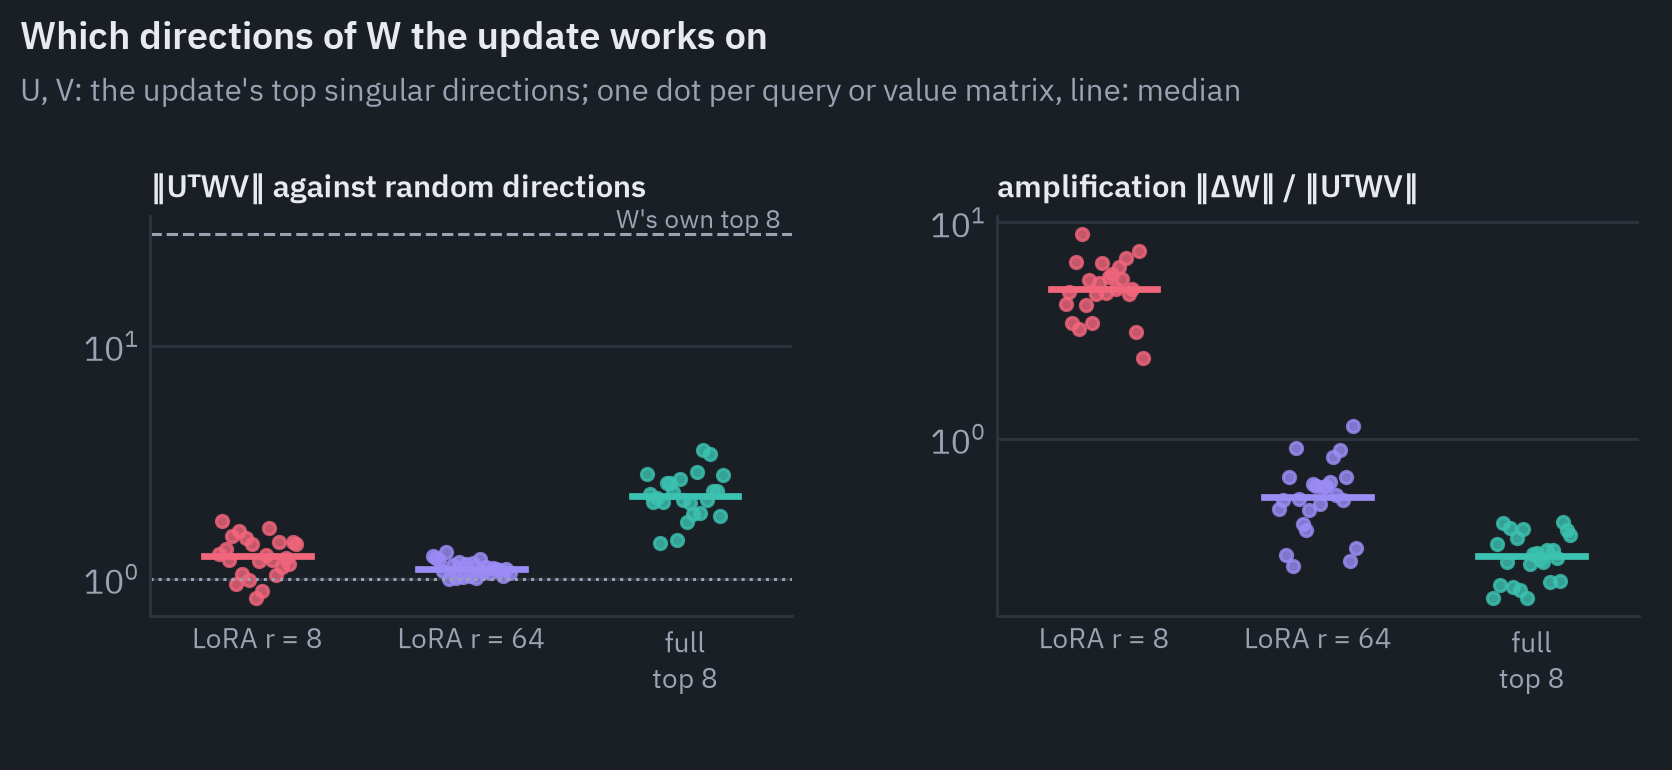
The shape again matches theirs, at a smaller scale. The rank-8 update’s directions are barely more aligned with \(W\) than random ones (1.2 times, while \(W\)’s own top 8 directions carry 28 times more), so the update does not reinforce what \(W\) already does strongly.
In those directions it is about five times larger than \(W\): the median factor is 4.9, where Hu et al. measured 21.5 for rank 4 on GPT-3.
At rank 64 the factor drops below 1, as in their paper it dropped to about 2. Full fine-tuning behaves differently: its top 8 directions are more aligned with \(W\) (2.3 times random), and the update in them is small, a third of \(W\) there.
Finally, the singular values, where the rank inequality from the beginning becomes visible:
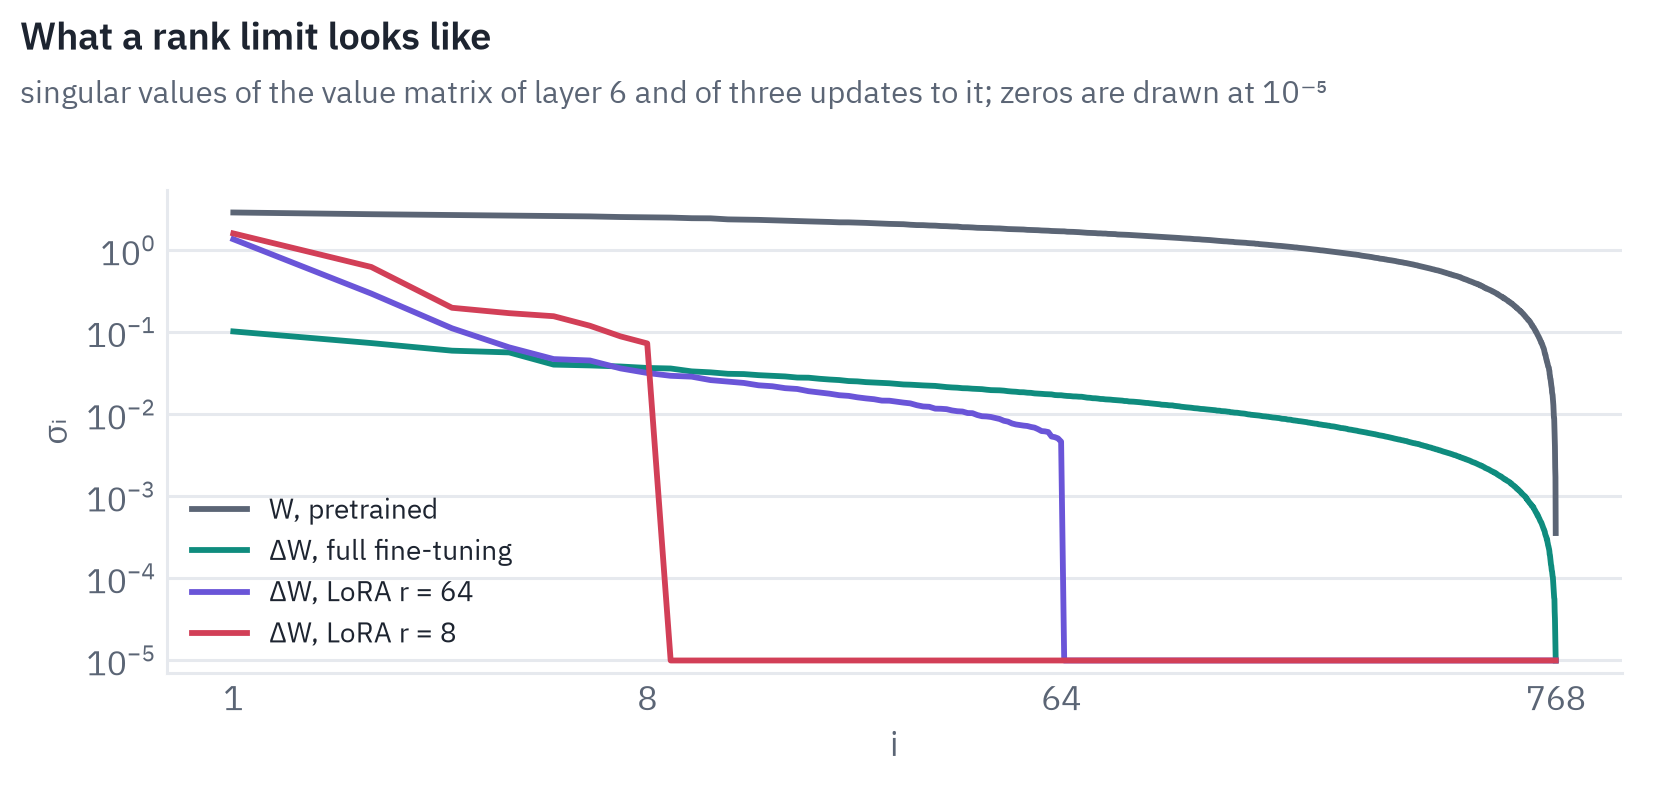
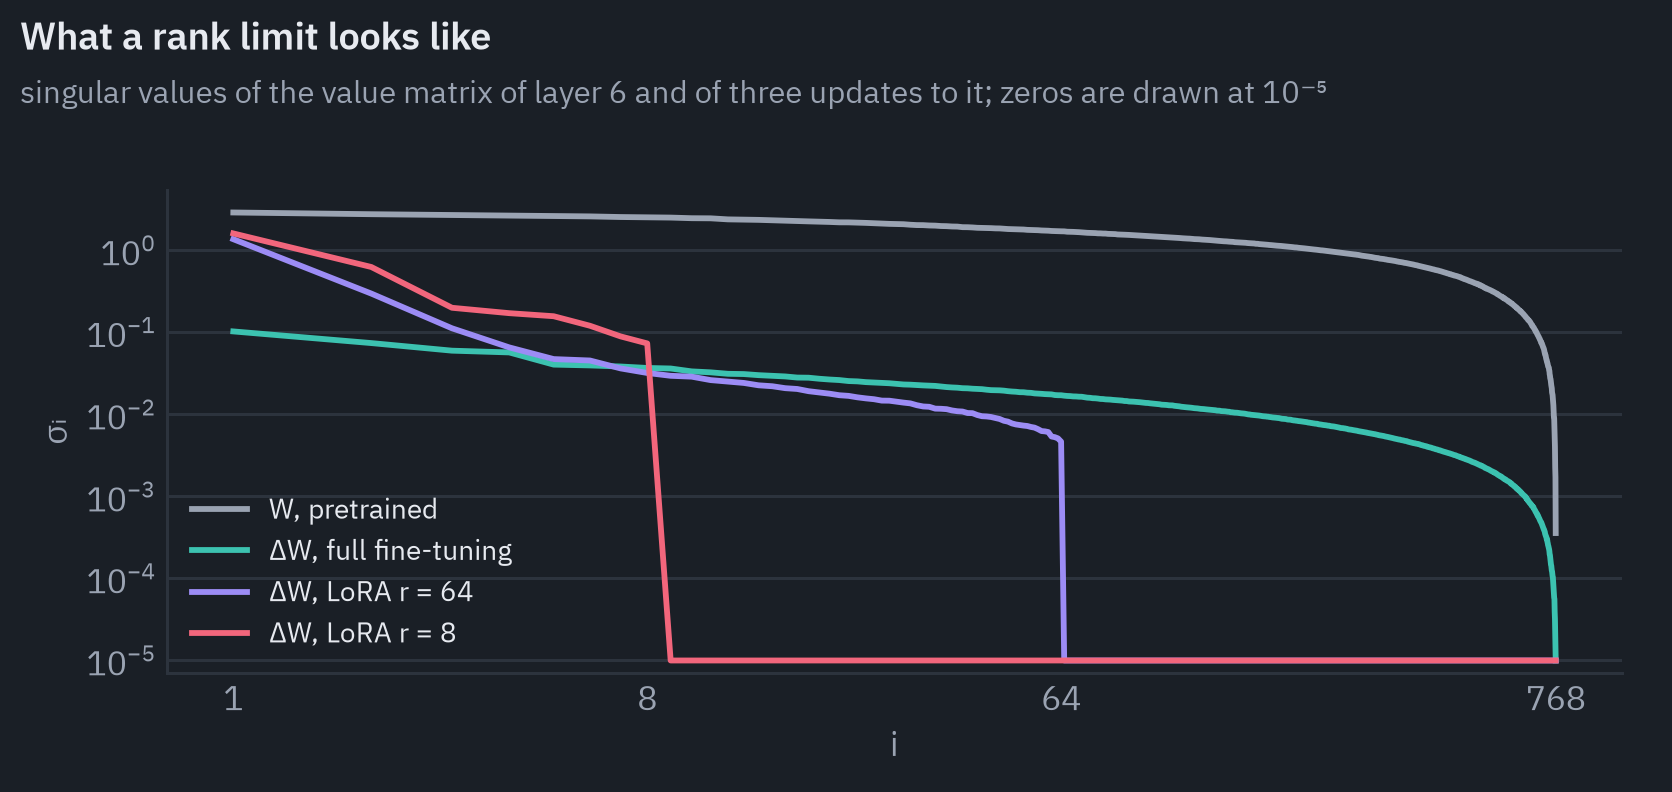
The rank-8 update has eight singular values and then a cliff to \(10^{-9}\), rounding error: \(\operatorname{rank}(BA) \le 8\), measured.
The update full fine-tuning makes has no cliff: its top 8 directions hold 37% of its energy, its top 64 hold 70%, and reaching 90% takes 193 directions.
These are the same numbers as in the adapters post’s separate run. The full update is also small: its norm is a sixth of LoRA’s (0.31 against 1.9 on average), since LoRA trains with a 25 times larger learning rate and packs the change into fewer directions.
And the two updates mostly point to different places: only 16% of full fine-tuning’s update (by norm) lies in the subspaces the rank-8 LoRA chose, against 1% for random subspaces of that size.
Biderman et al. draw the same line between the two questions: “the rank needed to reconstruct the weight matrix is higher than the rank needed for a downstream task.”
After training: merge, swap, add
When training ends, \(\gamma BA\) is just a matrix of the same shape as \(W_0\). Adding it in, \(W = W_0 + \gamma BA\), gives an ordinary model with no extra layers and no extra cost at inference: “no inference latency … by construction”, in the paper’s words.
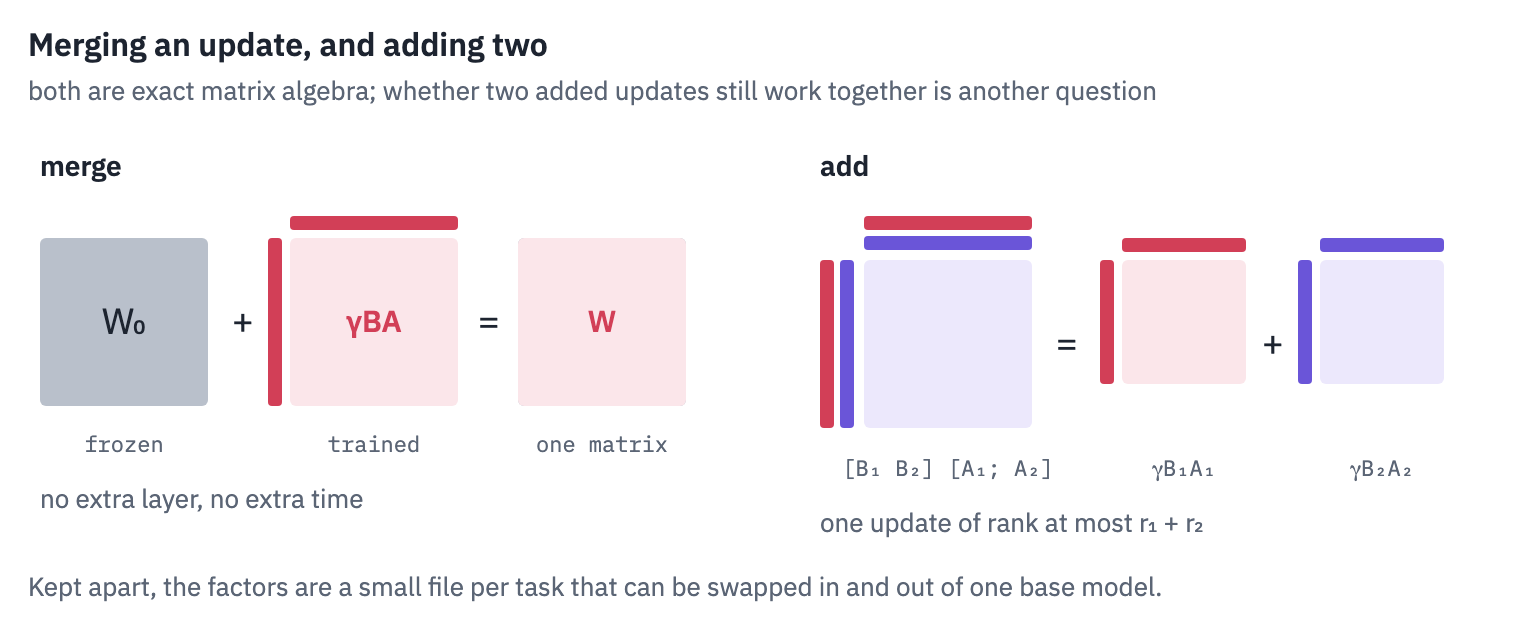
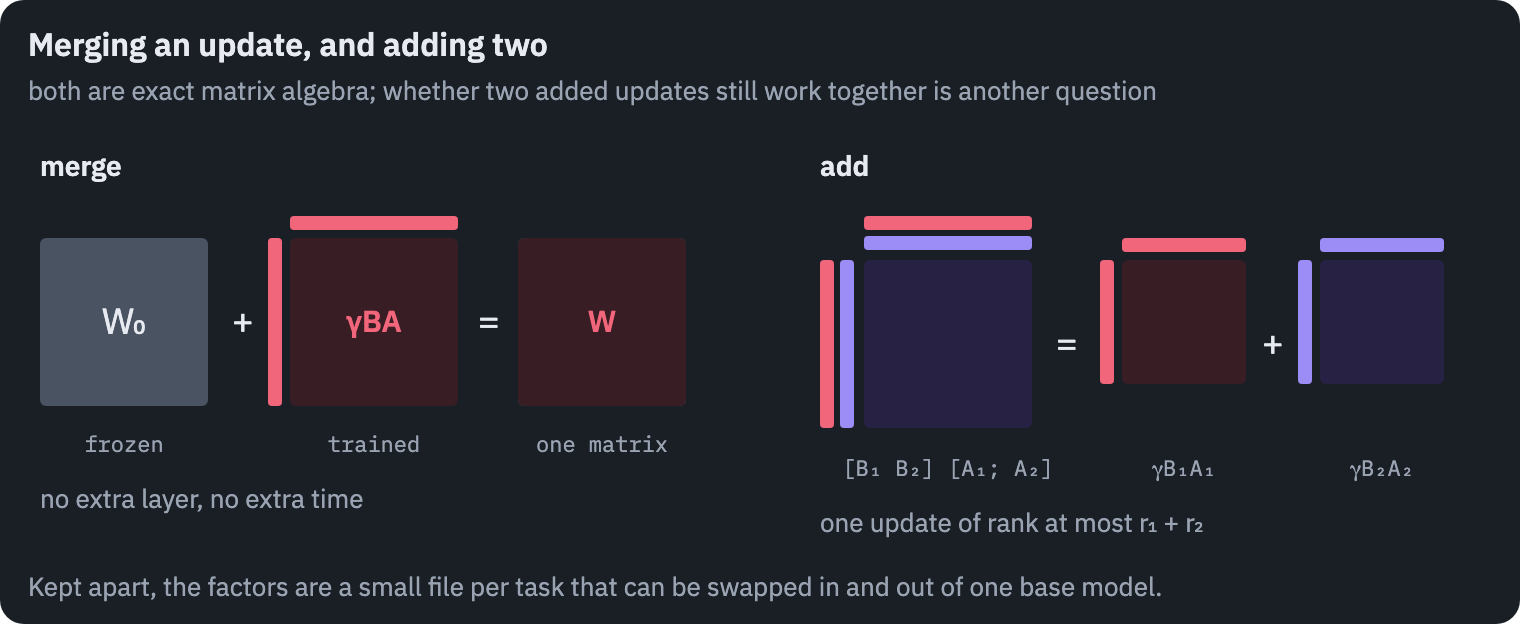
Merging is exact. In the adapters post the merged BERT gave the same outputs as the unmerged one to within \(2.1 \times 10^{-6}\), rounding error in 32-bit arithmetic.
Unmerged, the factors are a small file. On GPT-3, with \(r = 4\) on \(W_q\) and \(W_v\), a task costs 35 MB instead of a 350 GB copy of the model, so one base model and a hundred tasks take 354 GB instead of 35 TB.
Since merging and unmerging are exact, a server can keep one base model and swap updates in and out. The catch, which Hu et al. state themselves: once \(BA\) is folded into \(W\), “it is not straightforward to batch inputs to different tasks with different A and B in a single forward pass”.
Keep the factors separate instead, and every request in a batch can use its own: \(h = W_0 x + \gamma B_k A_k x\) costs two thin products per request. S-LoRA turned that into a serving system that keeps thousands of adapters in memory and batches requests that use different ones[12].
Updates can also be added. Two of them, \(\gamma B_1 A_1 + \gamma B_2 A_2\), are one LoRA of rank \(r_1 + r_2\):
\[B_1 A_1 + B_2 A_2 = \begin{bmatrix} B_1 & B_2 \end{bmatrix} \begin{bmatrix} A_1 \\ A_2 \end{bmatrix} ,\]so “stacking” adapters adds nothing a larger rank could not do. The algebra of the sum is exact; whether the sum works is a different question.
- Gabriel Ilharco and colleagues added whole fine-tuning updates (“task vectors”) for different image tasks. They found the updates “typically close to orthogonal”, and speculated that this is what lets them be added “with minimal interference”[13].
- When updates do overlap, they fight. TIES-Merging traces the losses to redundant changes and to disagreements in sign[14].
- LoraHub learns weights for combining LoRA modules from a few examples, and mixes the factors, \((\sum_i w_i B_i)(\sum_j w_j A_j)\)[15]. That is not the same as mixing the updates: the product expands into \(\sum_i w_i^2 B_i A_i\) plus cross terms \(w_i w_j B_i A_j\) that belong to neither adapter.
The family
Most of LoRA’s many descendants change one piece of the algebra above. A short map:
| method | what it changes | the update |
|---|---|---|
| rsLoRA[2] | the scale | \(\frac{\alpha}{\sqrt{r}} BA\) |
| LoRA+[11] | the learning rates | \(B\) learns \(\lambda\) times faster than \(A\) |
| AdaLoRA[16] | the rank, per matrix, during training | \(P \Lambda Q\), entries of \(\Lambda\) pruned by importance |
| DoRA[17] | length and direction, separately | \(m \, \frac{W_0 + BA}{\lVert W_0 + BA \rVert_c}\) |
| VeRA[18] | which factors are trained | \(\Lambda_b B \Lambda_d A\), with \(B, A\) random, frozen and shared |
| PiSSA[19] | the initialization | \(BA\) starts as the top-\(r\) SVD of \(W_0\) |
| QLoRA[20] | the frozen part | \(W_0\) stored in 4 bits |
The first two were measured above. The others, in a few words each.
AdaLoRA writes the update in the shape of an SVD, \(P \Lambda Q\), with a penalty that keeps \(P\) and \(Q\) close to orthogonal. During training it zeroes the “singular values” in \(\Lambda\) whose removal would hurt the loss least, so that important matrices end up with a higher rank[16].
DoRA splits each column of the weight matrix into a length \(m\) and a direction (\(\lVert \cdot \rVert_c\) is the length of each column). It trains the lengths directly and the directions with LoRA[17].
VeRA goes further than “only B”: both factors are random, frozen and shared by all layers, and each layer trains two vectors that scale their rows and columns. A layer then costs \(d + r\) numbers instead of \(2dr\)[18].
PiSSA is Eckart–Young put to work. It starts \(B\) and \(A\) from the top \(r\) singular directions of \(W_0\) itself and freezes the remainder, the error matrix of the best rank-\(r\) approximation, so that training starts on the directions in which \(W_0\) is largest[19].
LoftQ uses the same theorem to choose \(B\) and \(A\) so that they compensate for the error of quantizing \(W_0\)[21].
QLoRA leaves the algebra alone and changes the storage: the frozen \(W_0\) is kept in 4 bits, the factors in 16, so a 65-billion-parameter model can be fine-tuned on one 48 GB GPU[20].
Summing up
LoRA rests on one inequality, \(\operatorname{rank}(BA) \le r\), and one theorem, Eckart and Young’s, which says what a matrix of rank \(r\) can and cannot hold.
The rest follows from writing the update as a product: gradients that see the full gradient through two narrow windows, a start that must set one factor to zero and not both, and a scale that quietly decides how fast each rank learns.
On BERT and SST-2 the measurements side with both camps. A rank between 1 and 8 gets within a point of full fine-tuning, as Hu et al. found on GPT-3. And the original \(\alpha / r\) makes higher ranks look useless when, scaled by \(\alpha / \sqrt{r}\), they keep improving.
The change full fine-tuning makes is not low-rank. The change a task needs is often close to it, and how close depends on the task: Hu et al. themselves warn that “we do not expect a small r to work for every task or dataset”.
References
- Hu et al., 2021. arxiv.org. ↩
- Kalajdzievski, 2023. arxiv.org. ↩
- Biderman et al., 2024. arxiv.org. ↩
- Eckart & Young, 1936. doi.org. ↩
- Stewart, 1993. doi.org. ↩
- Mirsky, 1960. doi.org. ↩
- Li et al., 2018. arxiv.org. ↩
- Aghajanyan et al., 2021. arxiv.org. ↩
- Socher et al., 2013. aclanthology.org. ↩
- Zhu et al., 2024. arxiv.org. ↩
- Hayou et al., 2024. arxiv.org. ↩
- Sheng et al., 2023. arxiv.org. ↩
- Ilharco et al., 2023. arxiv.org. ↩
- Yadav et al., 2023. arxiv.org. ↩
- Huang et al., 2023. arxiv.org. ↩
- Li et al., 2024. arxiv.org. ↩