System Design
3 posts · all posts
It works on my laptop: a reproducible Docker image of a model
Ship a model so that it runs the same next year: a lock file with hashes, an image pinned by digest, builds that give the same bytes twice, GitHub Actions publishing to GHCR, the image pulled and run without Docker, and the model exported to ONNX for a free in-browser demo.
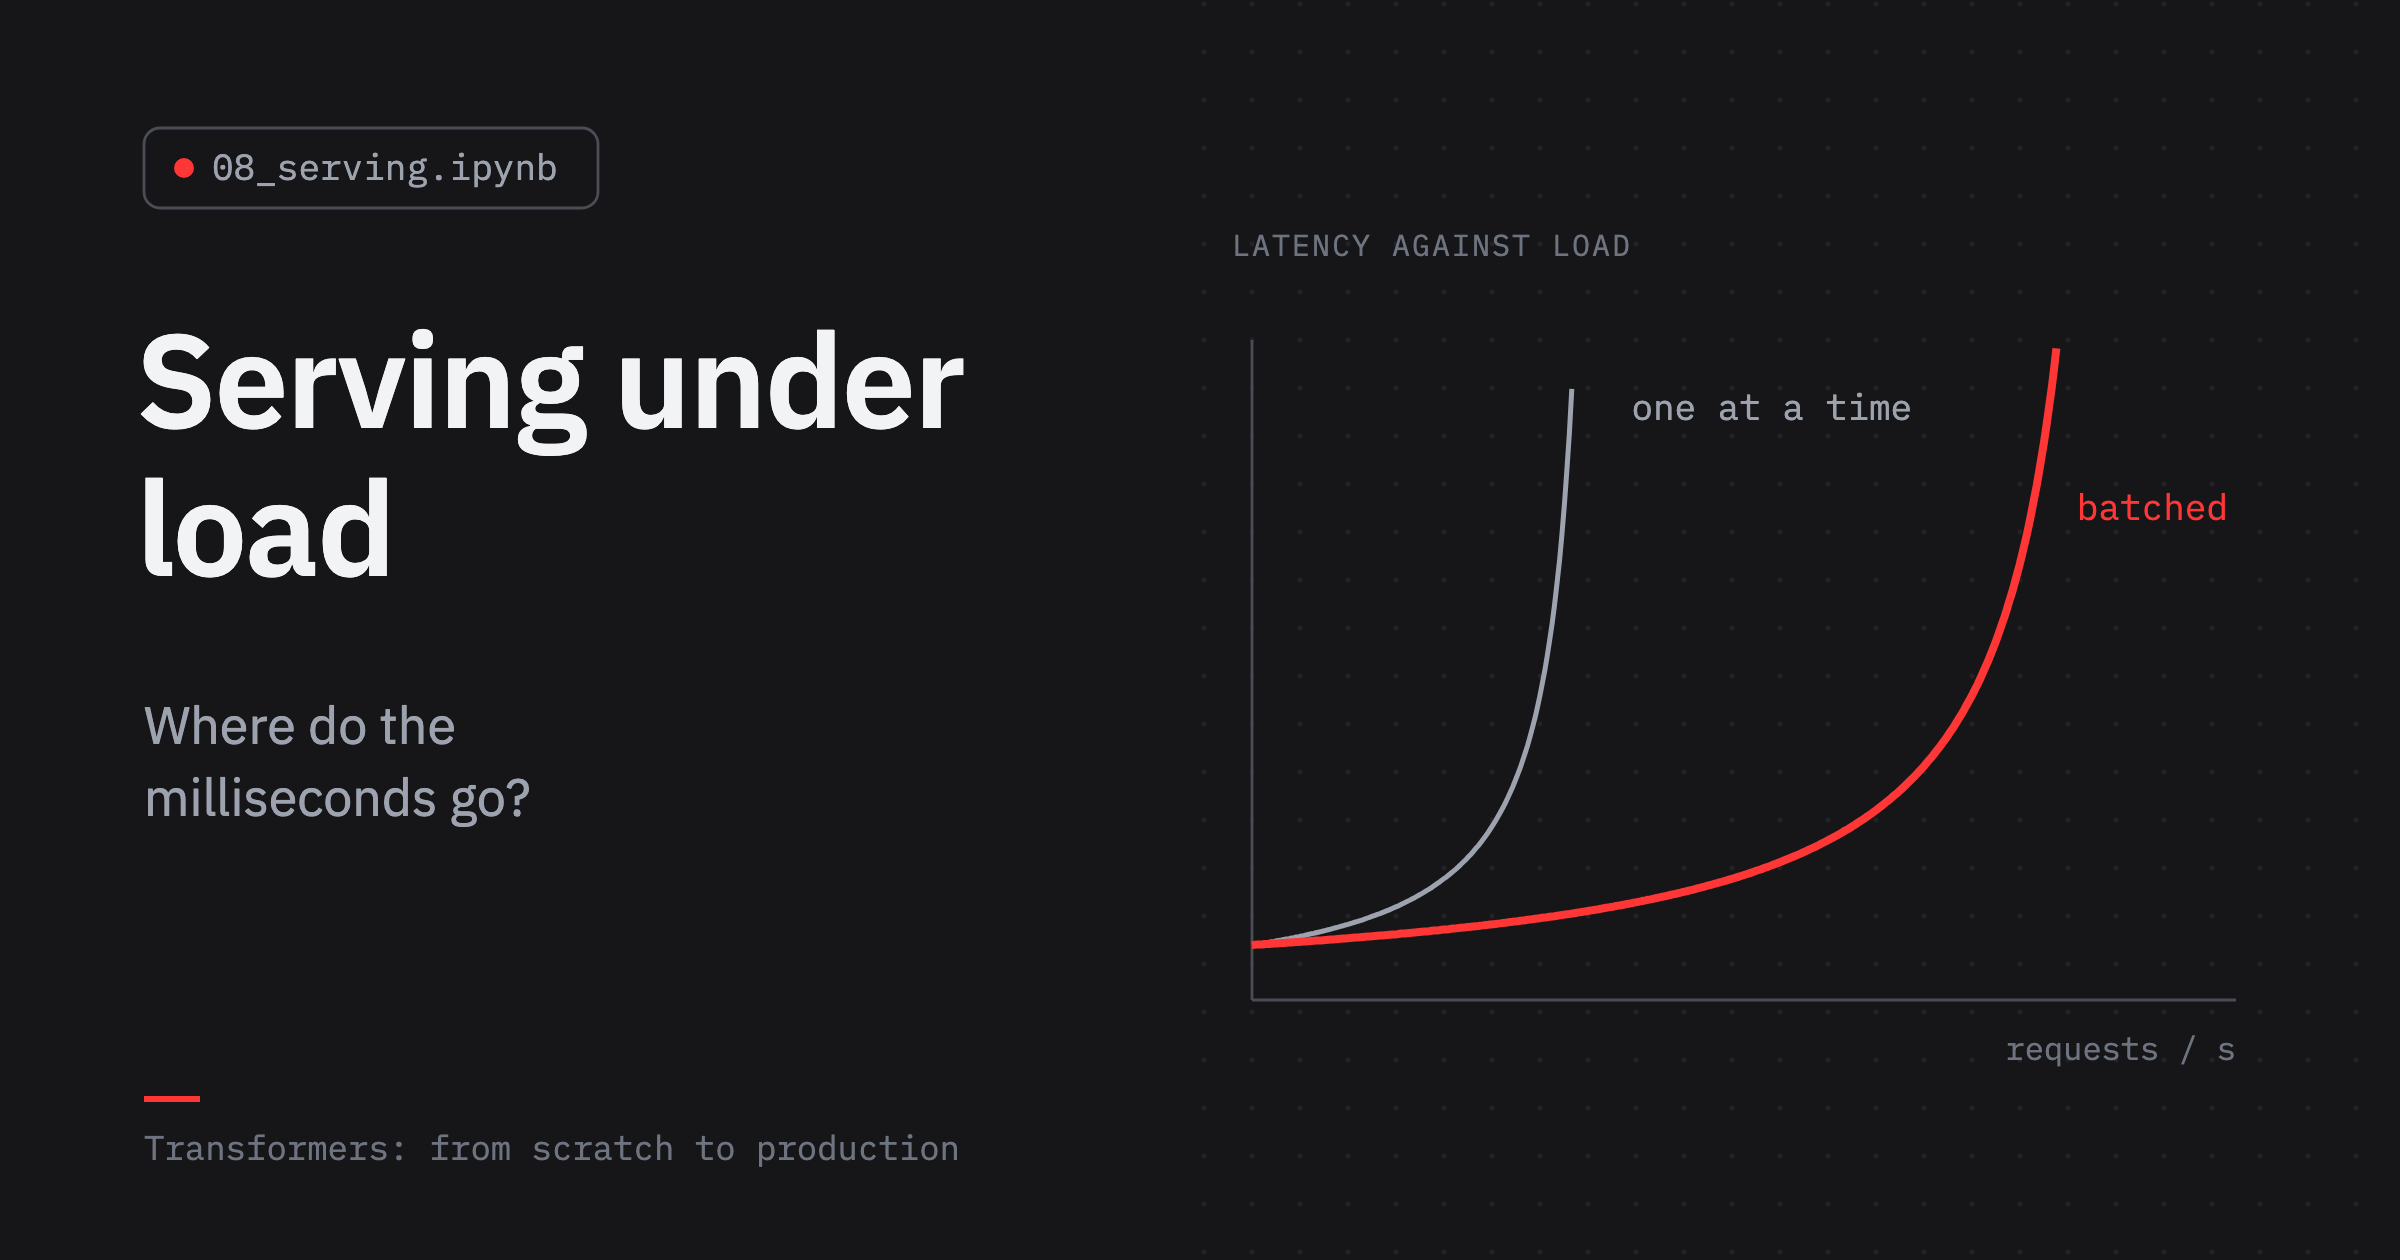
Serving a Transformer with FastAPI and Gradio: latency under load
Put a Transformer behind an HTTP API and measure it the way users meet it: a KV cache in beam search, int8 quantization that doesn't pay off, FastAPI and asyncio, open-loop load tests, queueing theory checked against the measurements, dynamic batching, and a Gradio page.
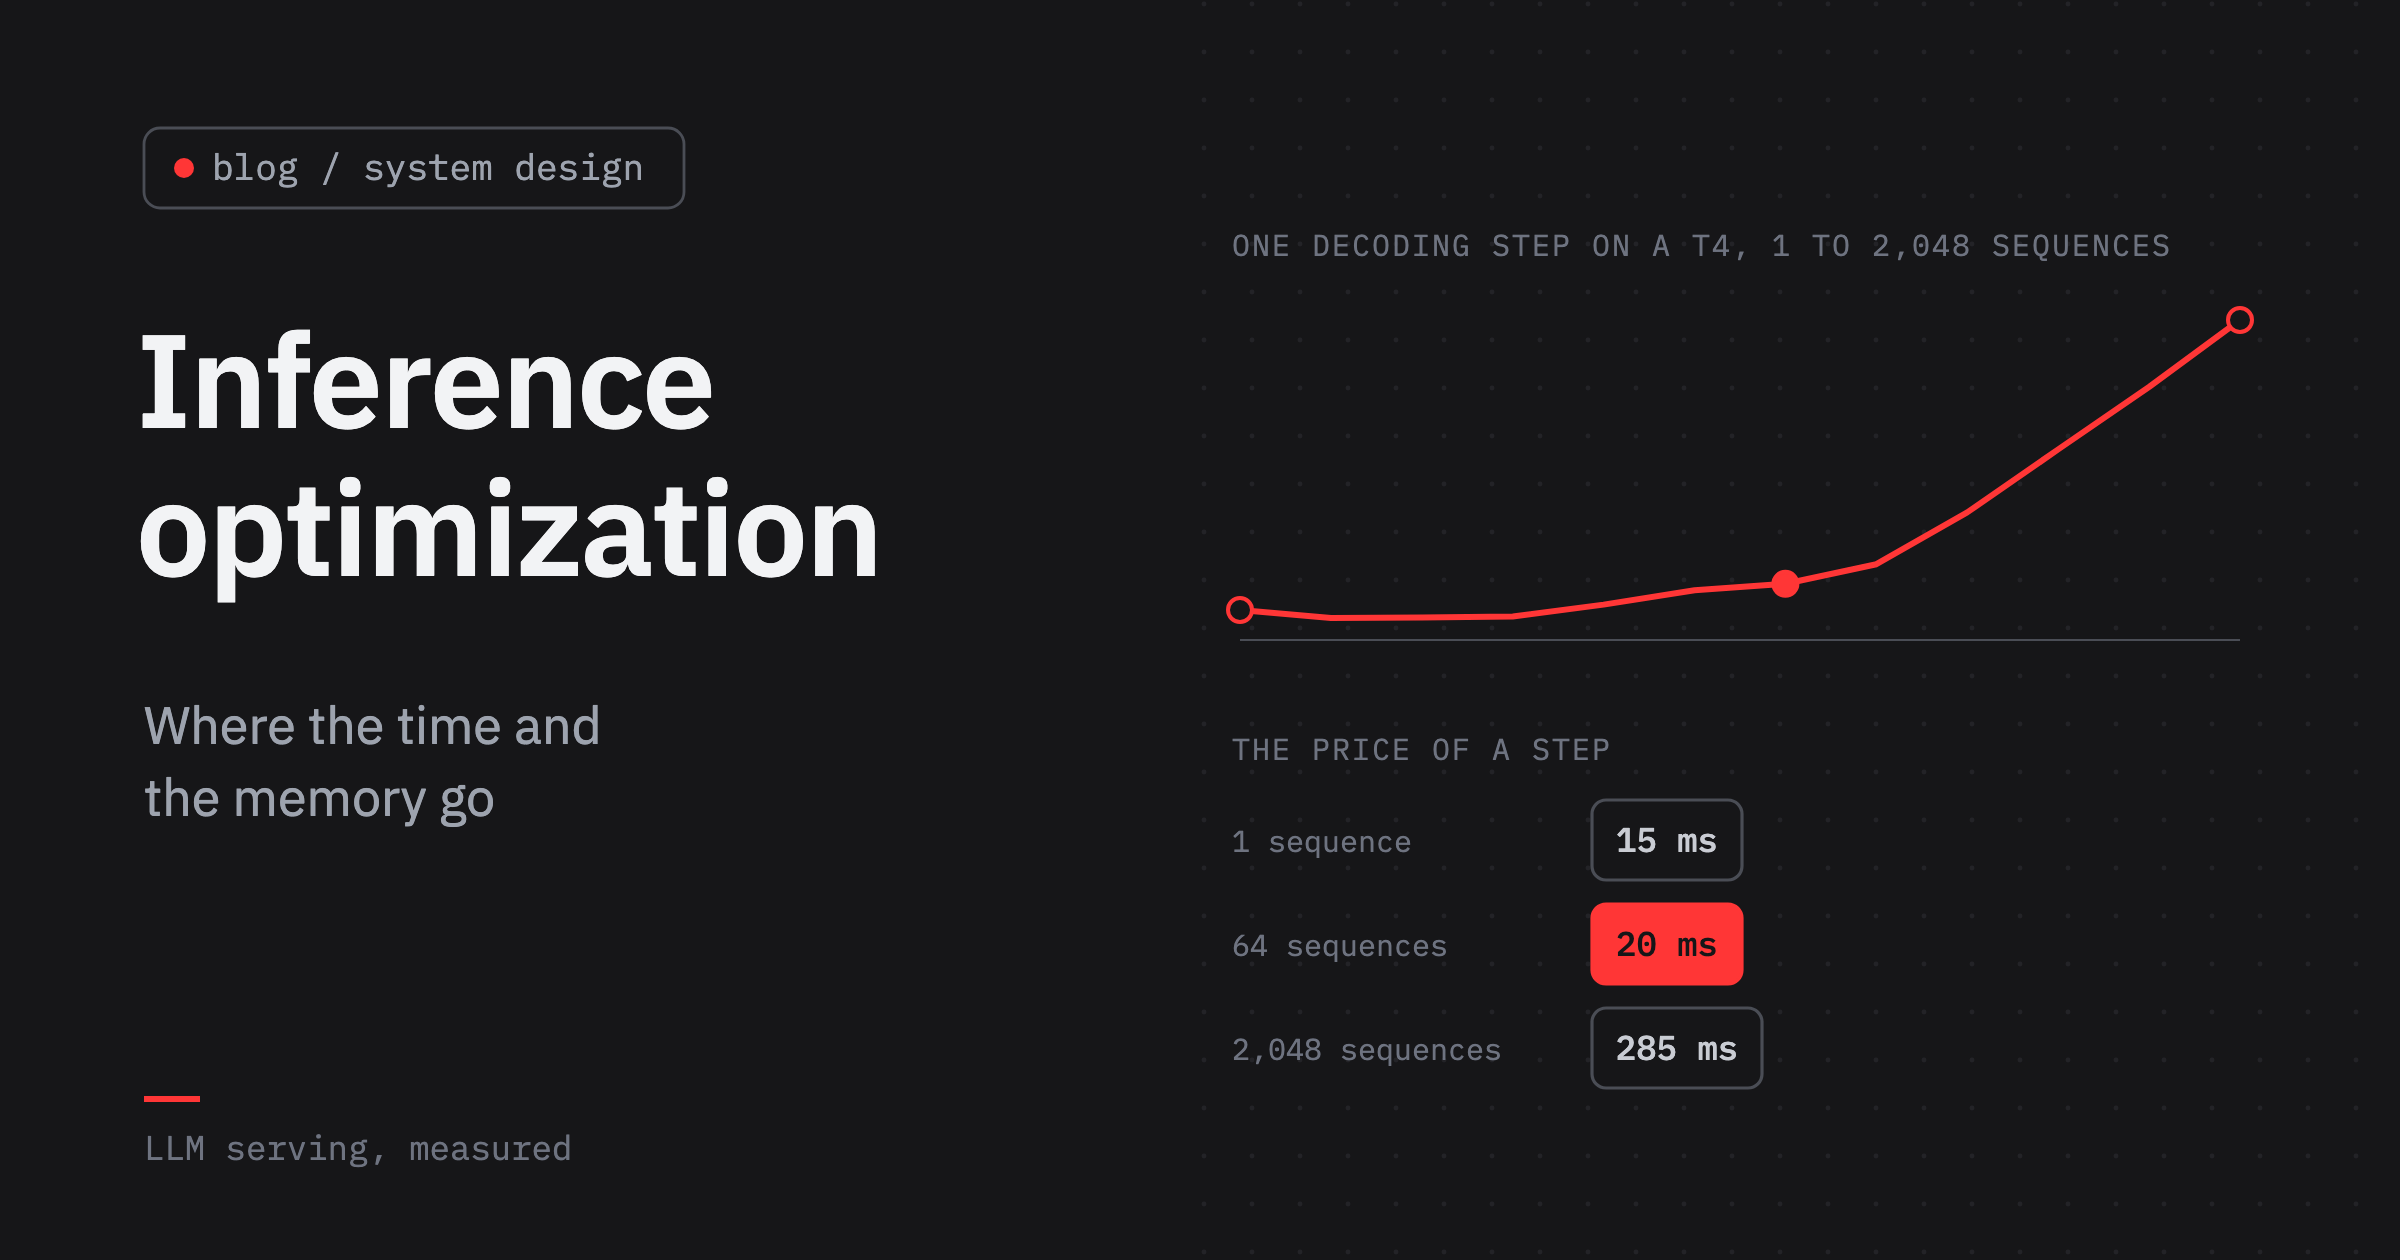
LLM inference optimization: where the time and memory go
Why generating text is limited by memory rather than arithmetic, measured on a free GPU, and what serving engines like vLLM do about it: the KV cache, continuous batching, quantization and speculative decoding