Contents
Open the price list of a large model API and compare two columns. On Anthropic’s, an output token costs five times as much as an input token, for every model on the list.
An input token the provider has already seen, a cache hit, costs a tenth of a fresh one or less. These ratios are not a marketing decision.
They are the physics of a GPU running a transformer, handed down to you: reading a prompt is cheap, writing an answer is expensive, and remembering a conversation takes memory that someone has to pay for.
You can watch the same physics from the other side. I took a model with one and a half billion parameters, Qwen2.5-1.5B-Instruct, put it on the free T4 GPU that Kaggle gives everyone, and let it generate text for one user. nvidia-smi reported the GPU 100% busy.
The GPU did 0.3% of the arithmetic it is built for. Then I gave it 1,024 users at once. nvidia-smi still said 100%, and this time the GPU did a hundred times more work.
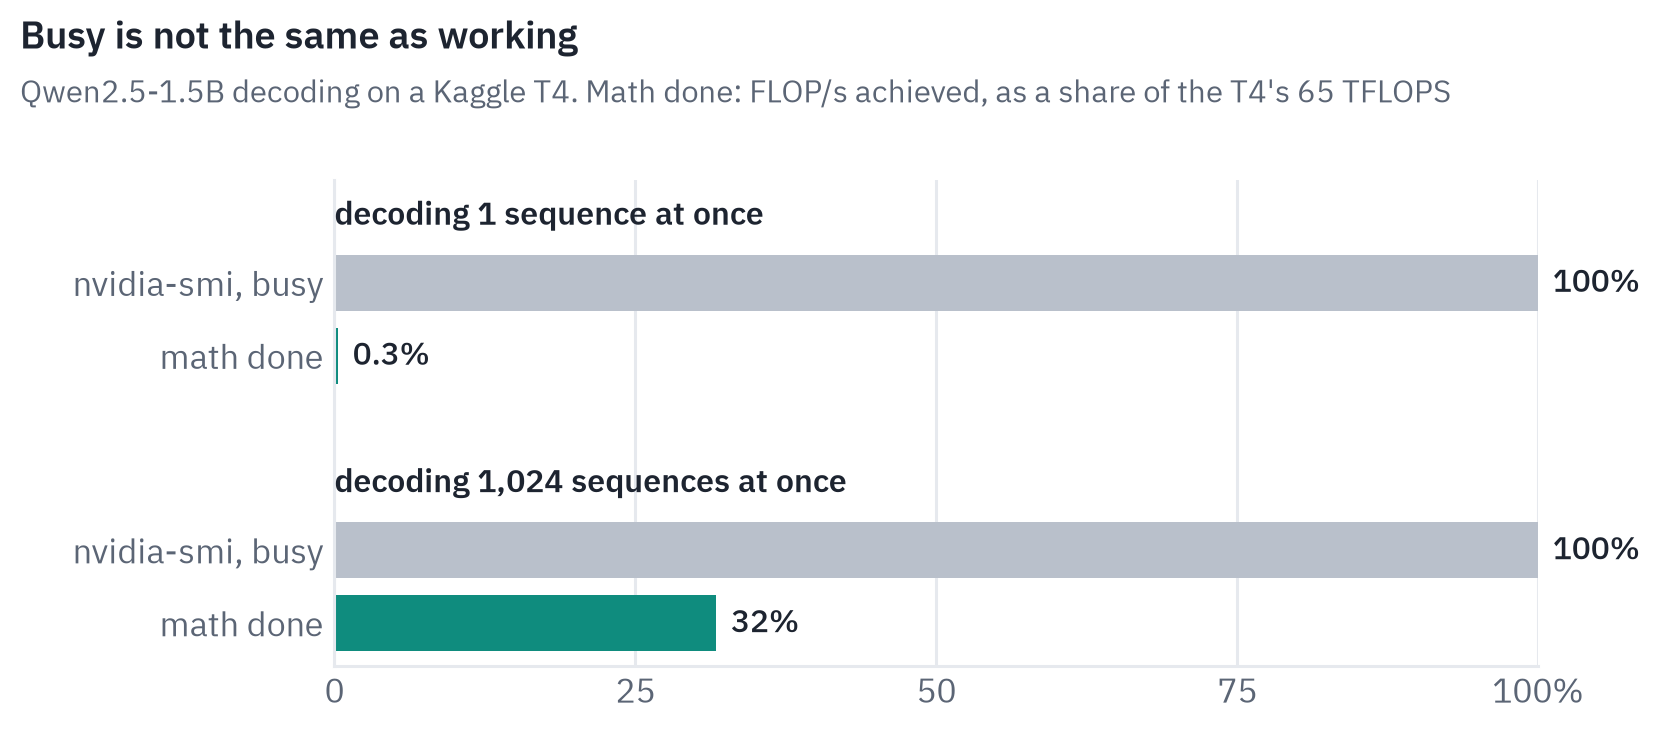
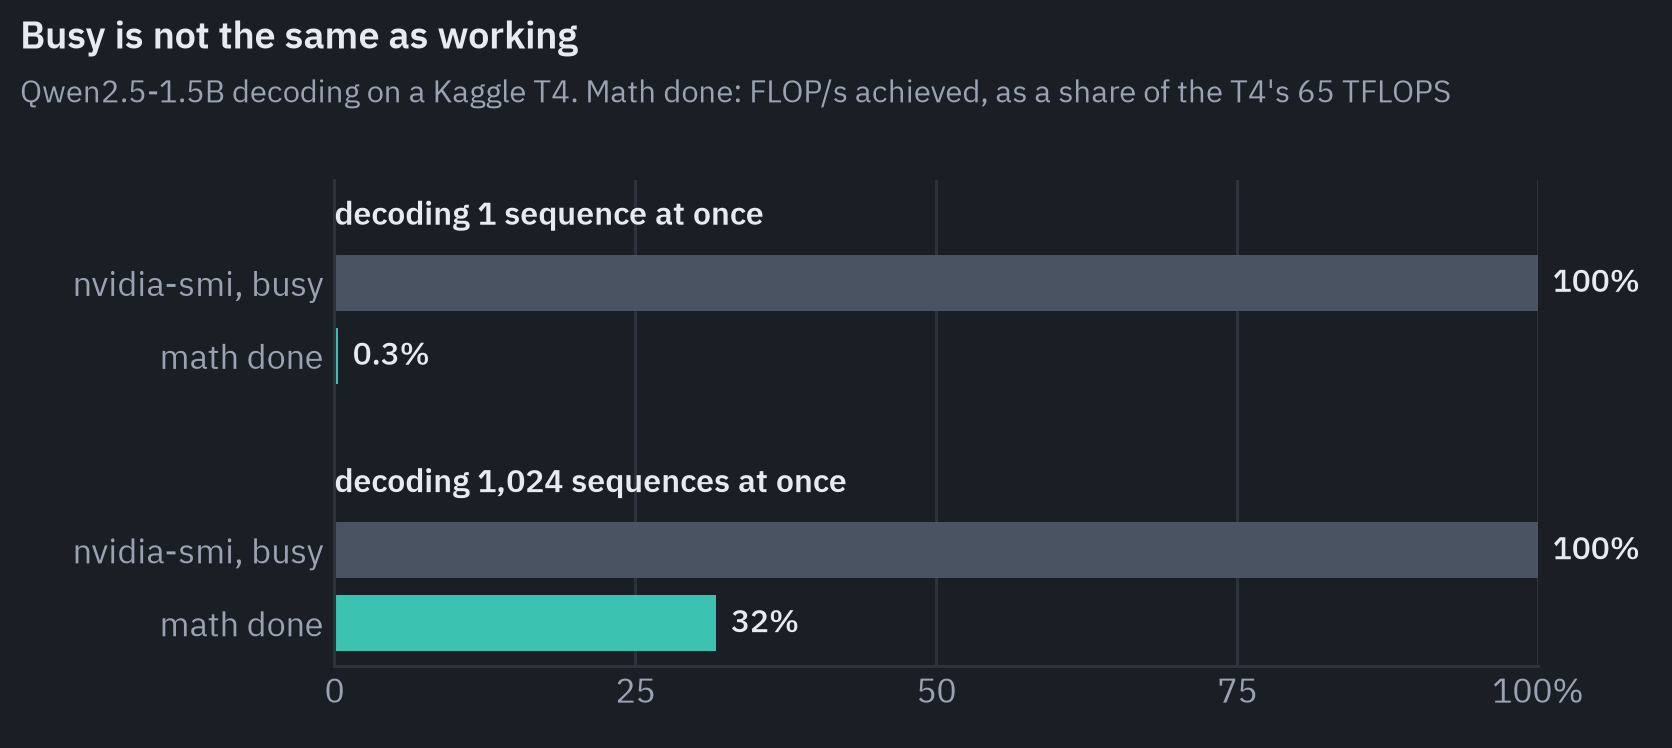
Inference optimization lives in the gap between these two runs. Below, in order: what a request does on the GPU, why generating text is limited by memory rather than by arithmetic, where the memory goes, and what serving engines such as vLLM, SGLang and TensorRT-LLM do about each part.
Then the system around the engine: streaming, queues, scaling and the numbers to watch. Every measurement comes from one script that runs on the same free GPU, and every figure is drawn from its output by code you can rerun.
Two phases of one request
A request starts with a prompt. The engine turns it into tokens and runs the model over all of them in a single forward pass. This is the prefill: every layer computes keys and values for every prompt token, in parallel, and the last position yields the probabilities of the first new token.
Then comes the decode: the model takes the token it has just produced, runs one more forward pass and gets the next one. One token per pass, each pass waiting for the one before it, until an end-of-sequence token or the length limit.
In code the two phases are the same model(...) call. On the hardware they behave nothing alike. Here is one request on the T4, drawn to scale: a 1,024-token prompt and a 64-token answer.
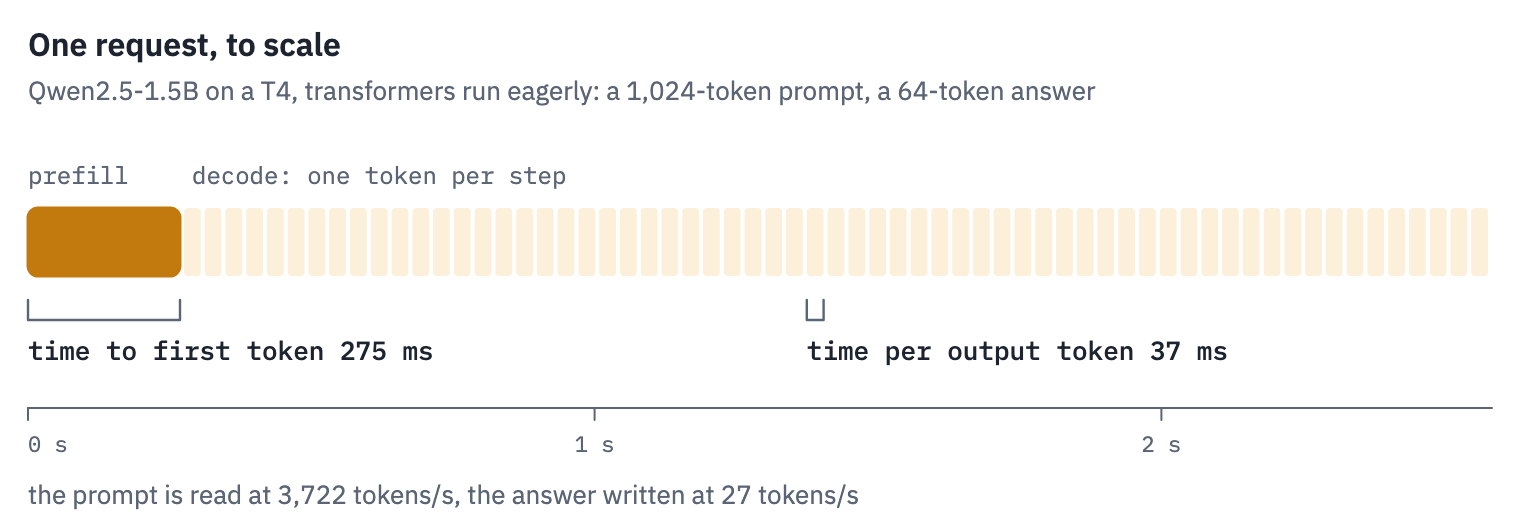
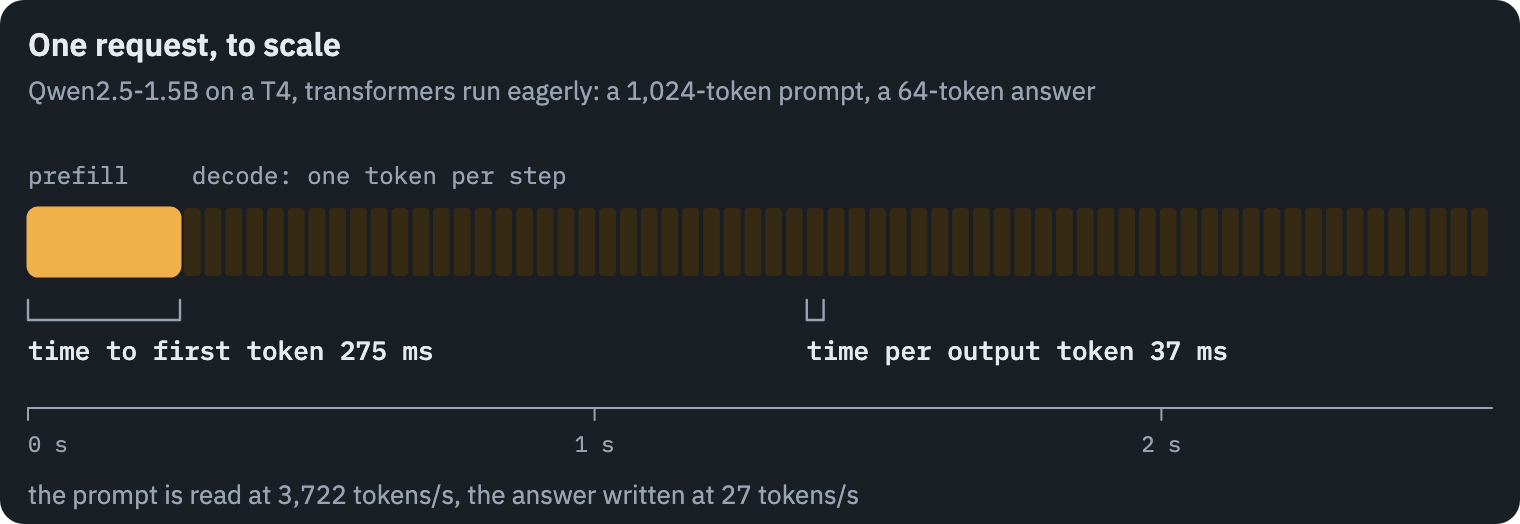
Reading the prompt took 275 ms, about 3,700 tokens per second. Each token of the answer took 37 ms, 27 tokens per second.
The answer is sixteen times shorter than the prompt and took eight times longer.
Two numbers describe how fast a request feels, one per phase:
- Time to first token (TTFT): the wait before anything appears. It is the time in the queue plus the prefill, so it grows with the prompt.
- Time per output token (TPOT), also called inter-token latency: the pace of the stream after that. It is one decoding step.
A third number describes the service rather than one user: throughput, tokens per second over all requests together.
The DistServe paper adds a fourth, closer to what a business wants: goodput, the request rate a GPU can serve while keeping, say, 90% of requests within their TTFT and TPOT targets. A server can raise its throughput by making everyone wait. Goodput doesn’t let it.
The price list now reads differently. An input token goes through the prefill together with thousands of others.
An output token gets a forward pass of its own. The next section is about why that pass costs so much.
Why decoding is slow: the memory wall
A GPU has two resources that matter here. It does arithmetic, measured in floating-point operations per second, and it moves data between its memory and its compute units, measured in bytes per second. From the datasheets:
| GPU | 16-bit tensor math | memory bandwidth | FLOPs per byte to stay busy |
|---|---|---|---|
| T4 | 65 TFLOPS | 320 GB/s | 203 |
| A100 80GB SXM | 312 TFLOPS | 2,039 GB/s | 153 |
| H100 SXM | 989 TFLOPS | 3,350 GB/s | 295 |
The A100 and H100 pages print 624 and 1,979 TFLOPS. Those figures assume structured sparsity, which a dense model doesn’t use; without it the throughput is half.
The last column is the ratio of the other two, the ridge point. A kernel that does fewer operations per byte it reads than the ridge point waits for memory, however many TFLOPS the GPU has. A kernel that does more waits for arithmetic.
Now count for one decoding step. A weight matrix \(W\) of shape \(d_{\text{out}} \times d_{\text{in}}\) is applied to \(B\) token vectors, one for each sequence in the batch. Each output number takes \(d_{\text{in}}\) multiplications and as many additions, so the step does \(2 B d_{\text{in}} d_{\text{out}}\) operations.
To do them, the GPU reads the matrix from memory once: \(2 d_{\text{in}} d_{\text{out}}\) bytes in 16-bit precision. The inputs and outputs are \(B\) short vectors and small next to the matrix. The arithmetic intensity, operations per byte, is
\[I = \frac{2 B \, d_{\text{in}} d_{\text{out}}}{2 \, d_{\text{in}} d_{\text{out}}} = B .\]One sequence, one operation per byte. The H100 needs 295 to keep its tensor cores busy, so decoding a single sequence can use at most a third of a percent of its arithmetic.
The roofline model puts both limits into one bound. A step that reads \(M\) bytes and does \(F\) operations takes at least
\[t \;\ge\; \max\left(\frac{M}{\text{bandwidth}},\; \frac{F}{\text{peak}}\right).\]The first term is the time to read the data, the second the time to compute on it. The larger one is the bottleneck, and speeding up the other changes nothing. Drawn as attainable FLOP/s against intensity, the bound is a slope that turns flat at the ridge point:
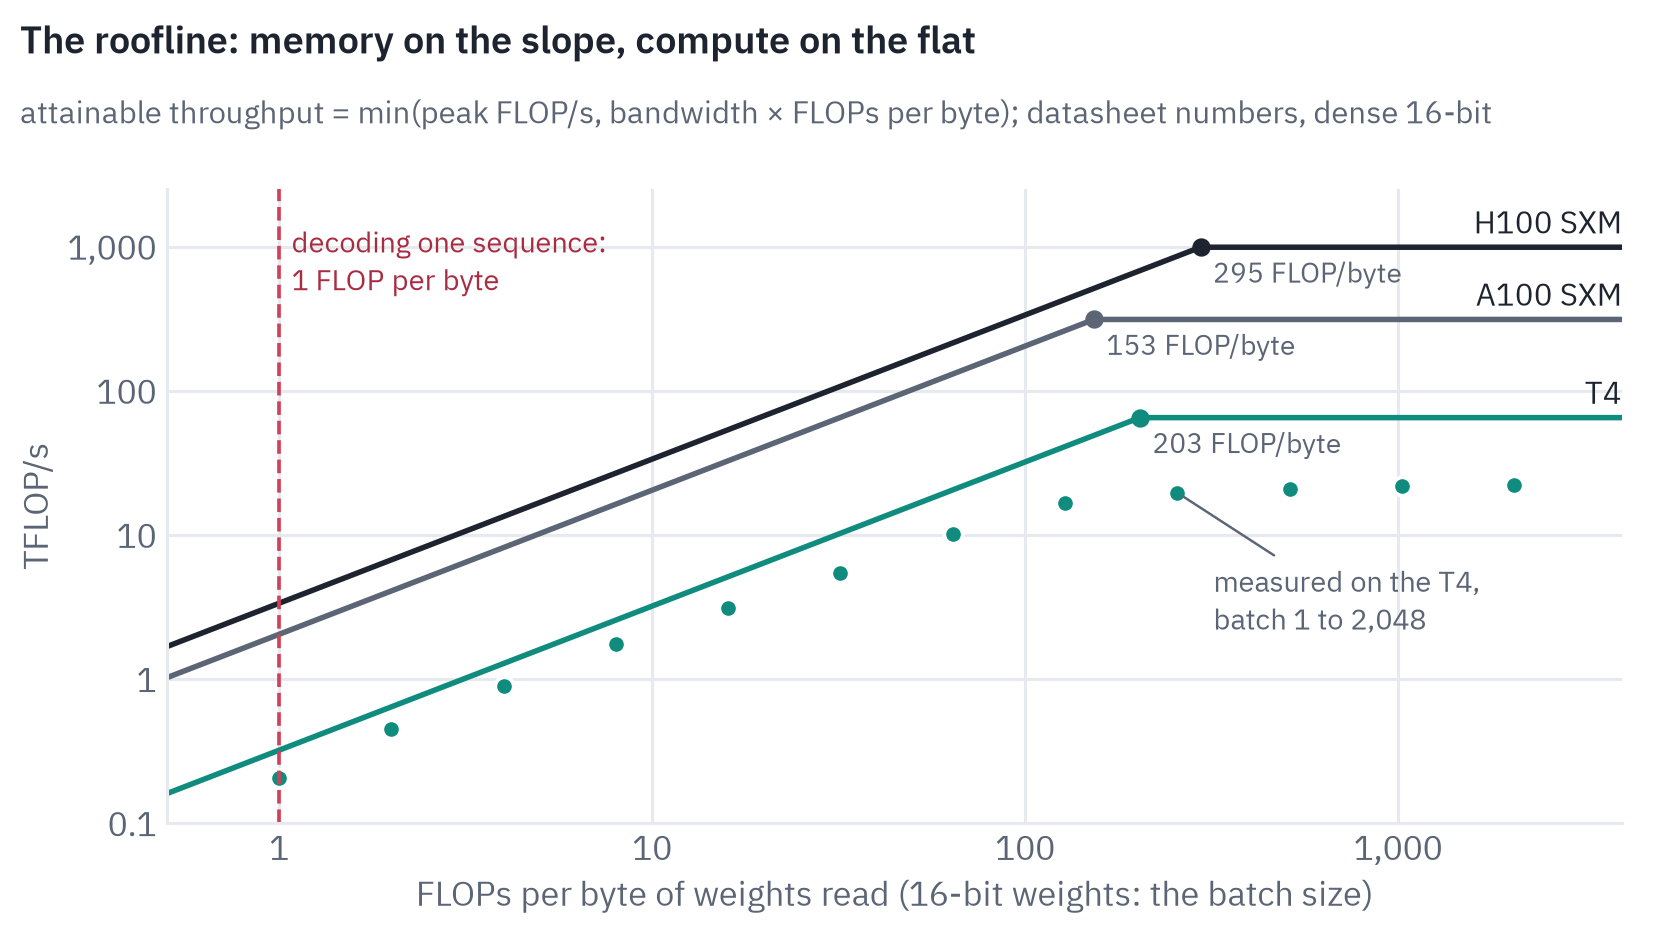
The dots are the T4, measured: every weight matrix of Qwen2.5-1.5B applied to a batch of 1 to 2,048 new tokens, recorded as a CUDA graph so that the timing holds GPU work only (more on that below).
They climb the slope and bend where the roofline says they should, below it. Measured memory bandwidth peaked at 224 GB/s, 70% of the datasheet’s 320, and the arithmetic at 22 TFLOP/s, a third of 65.
During the run the T4 sat at its 70 W power limit, and nvidia-smi showed its clock at 600 to 800 MHz. Datasheet numbers are ceilings; plan with measured ones.
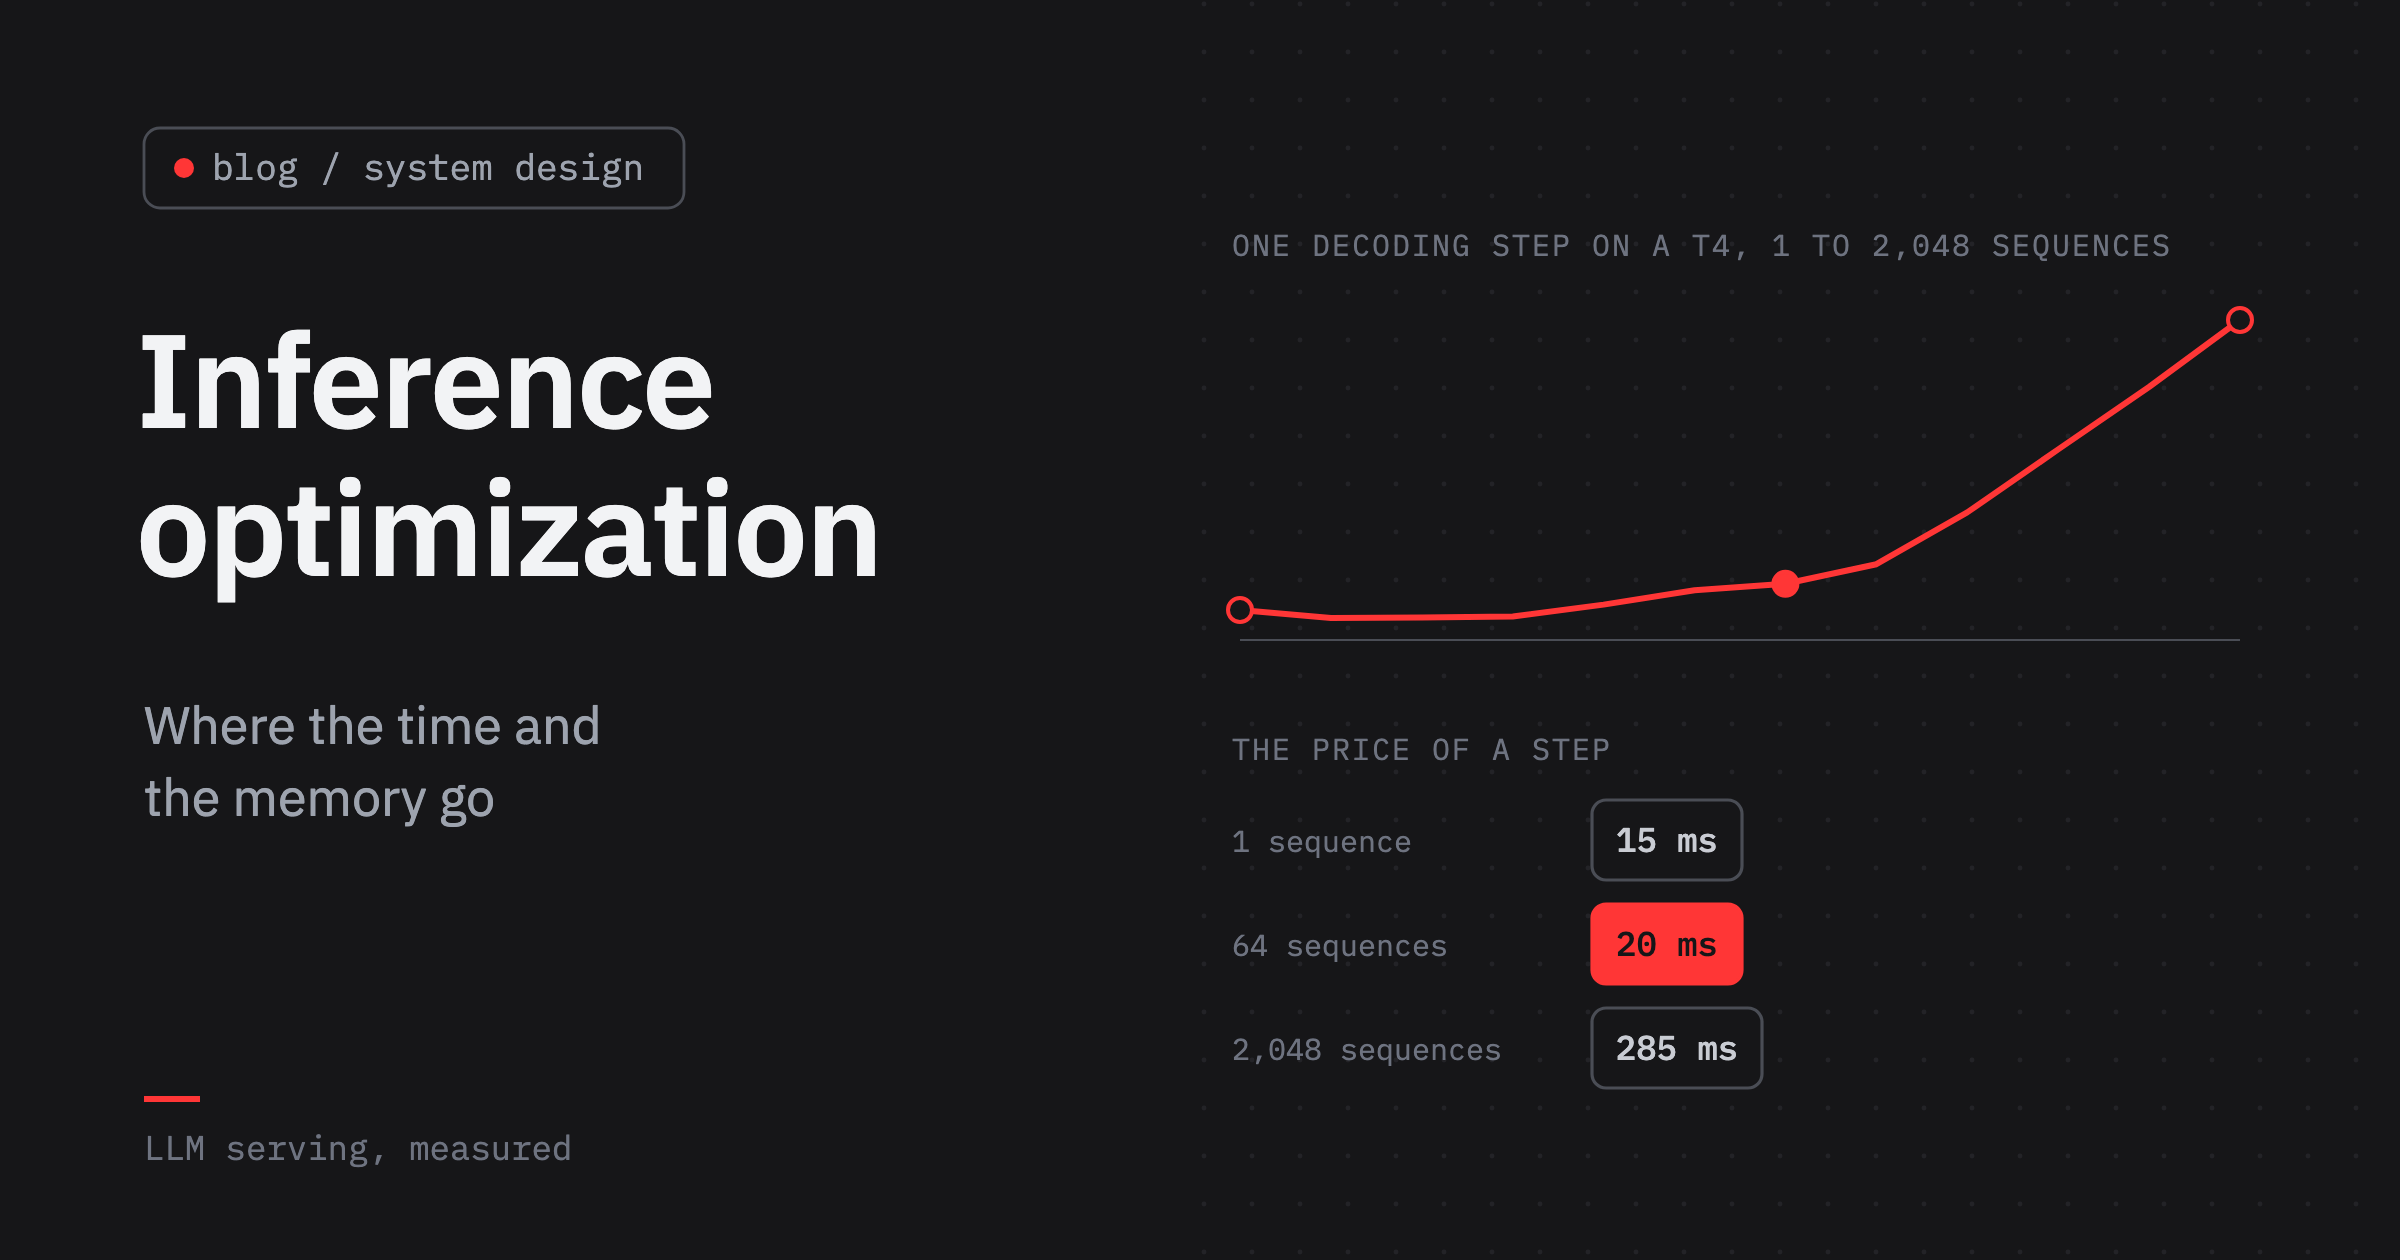
In time per step the same measurement looks like this:
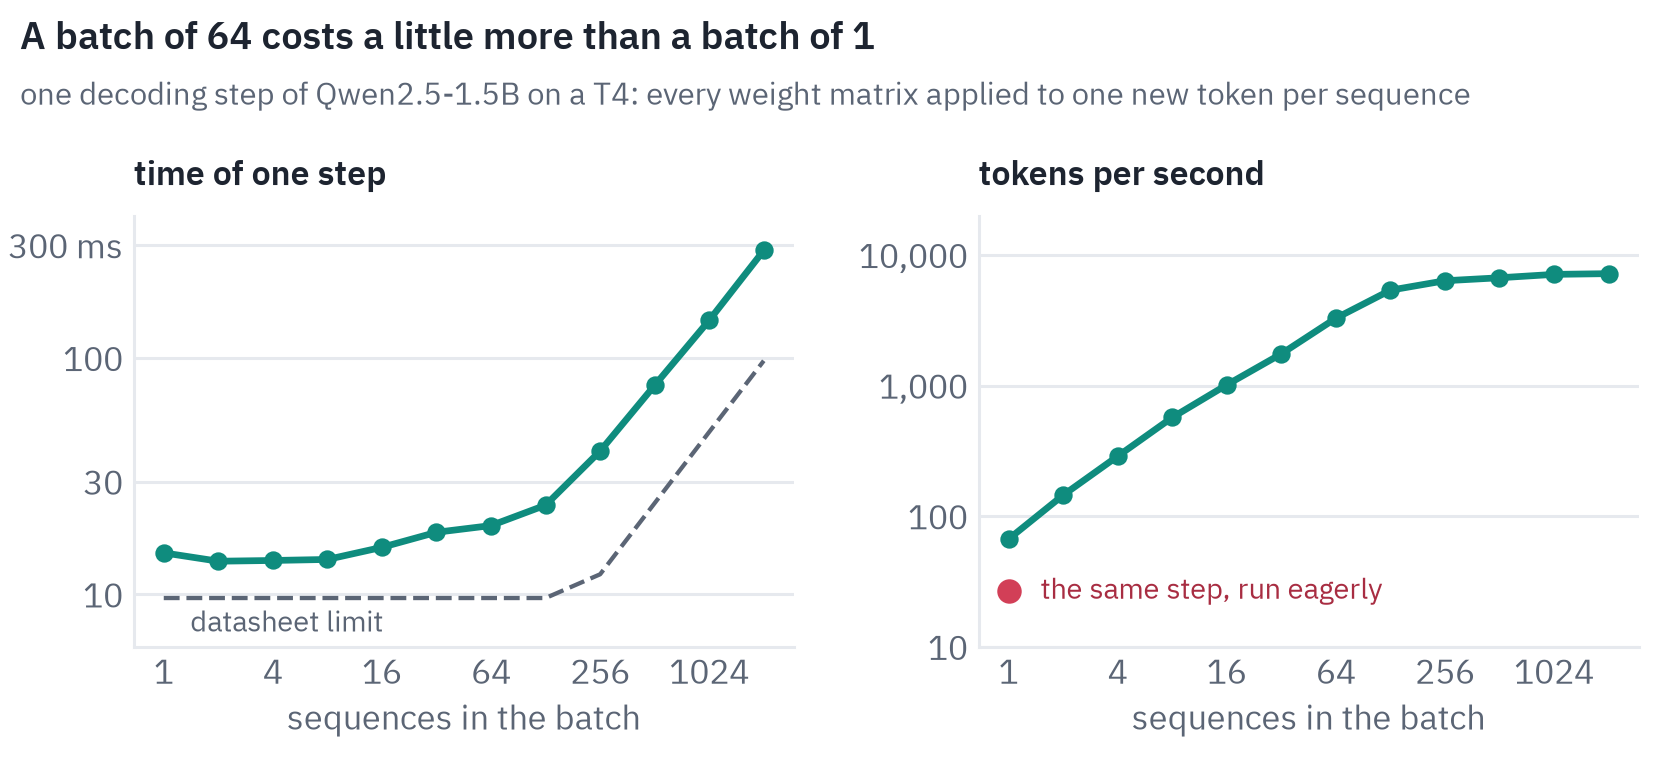
One step for one sequence took 15 ms. For 64 sequences it took 20 ms. Sixty-three more users cost 30% more time, because the expensive part, reading 3.1 GB of weights, happens once per step whatever the batch.
From about 256 sequences on the step is compute-bound, its time grows in proportion to the batch, and the throughput levels off at about 7,000 tokens per second.
Key point
The central fact of serving language models: a single sequence leaves almost all of a GPU’s arithmetic unused, and the way to use it is to decode many sequences in the same step. Most of what follows is about making large batches possible: fitting their memory, keeping them full, and not letting one request hold up the rest.
The same fact gives a ceiling you can compute before renting anything. One sequence can’t decode faster than the GPU reads all the weights:
def decode_ceiling(params, bytes_per_param, bandwidth):
    # every decoding step reads every weight once
    return bandwidth / (params * bytes_per_param)

print(f"{decode_ceiling(8.03e9, 2, 3.35e12):.0f} tokens/s")  # Llama 3.1 8B, bf16, one H100
209 tokens/sReal engines land below it: attention adds the reads of the KV cache, and no kernel reaches the datasheet’s bandwidth.
What nvidia-smi measures. Its GPU-Util is, in NVIDIA’s words, the “percent of time over the past sample period during which one or more kernels was executing on the GPU”. It counts time, not work.
A kernel that streams weights at full bandwidth while the tensor cores stand idle counts as 100%. In the same runs another column of nvidia-smi, memory utilization, the share of time memory was being read or written, was closer to the truth: 100% for one sequence, 36% for 1,024.
To see how much of the chip is working, use the profiling metrics of DCGM: DCGM_FI_PROF_SM_ACTIVE, DCGM_FI_PROF_PIPE_TENSOR_ACTIVE, “the fraction of cycles the tensor (HMMA / IMMA) pipe was active”, and DCGM_FI_PROF_DRAM_ACTIVE.
What Python costs. The same decoding step run by transformers the usual way, eagerly, took 37 ms instead of 15: the red dot on the right.
The model and the kernels are the same. The difference is that Python launches hundreds of small kernels one after another, and with one sequence the GPU finishes each before the next one arrives.
Serving engines record the decoding step once as a CUDA graph and replay the whole step with a single launch; vLLM does it by default, for a range of batch sizes. On a small model the launches can cost more than the math.
The KV cache: what the model has to remember
Attention lets a new token look at every token before it, and for that it needs their keys and values in every layer. Those don’t change once computed, since a causal model never lets an early token see a later one, so the engine keeps them.
This store is the KV cache. Without it, every decoding step would process the whole text from the beginning. Here is the same 1,024-token answer generated both ways:
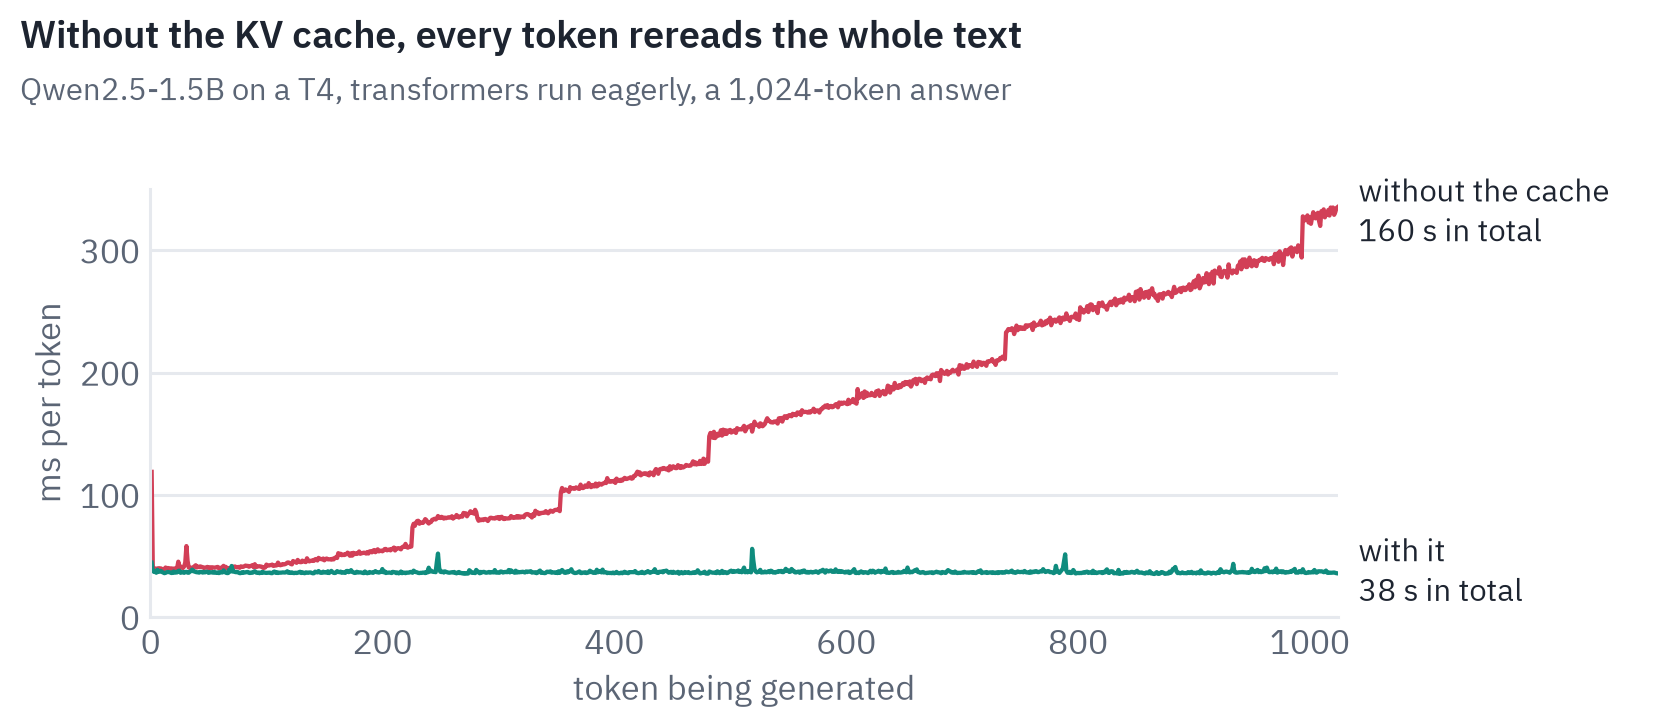
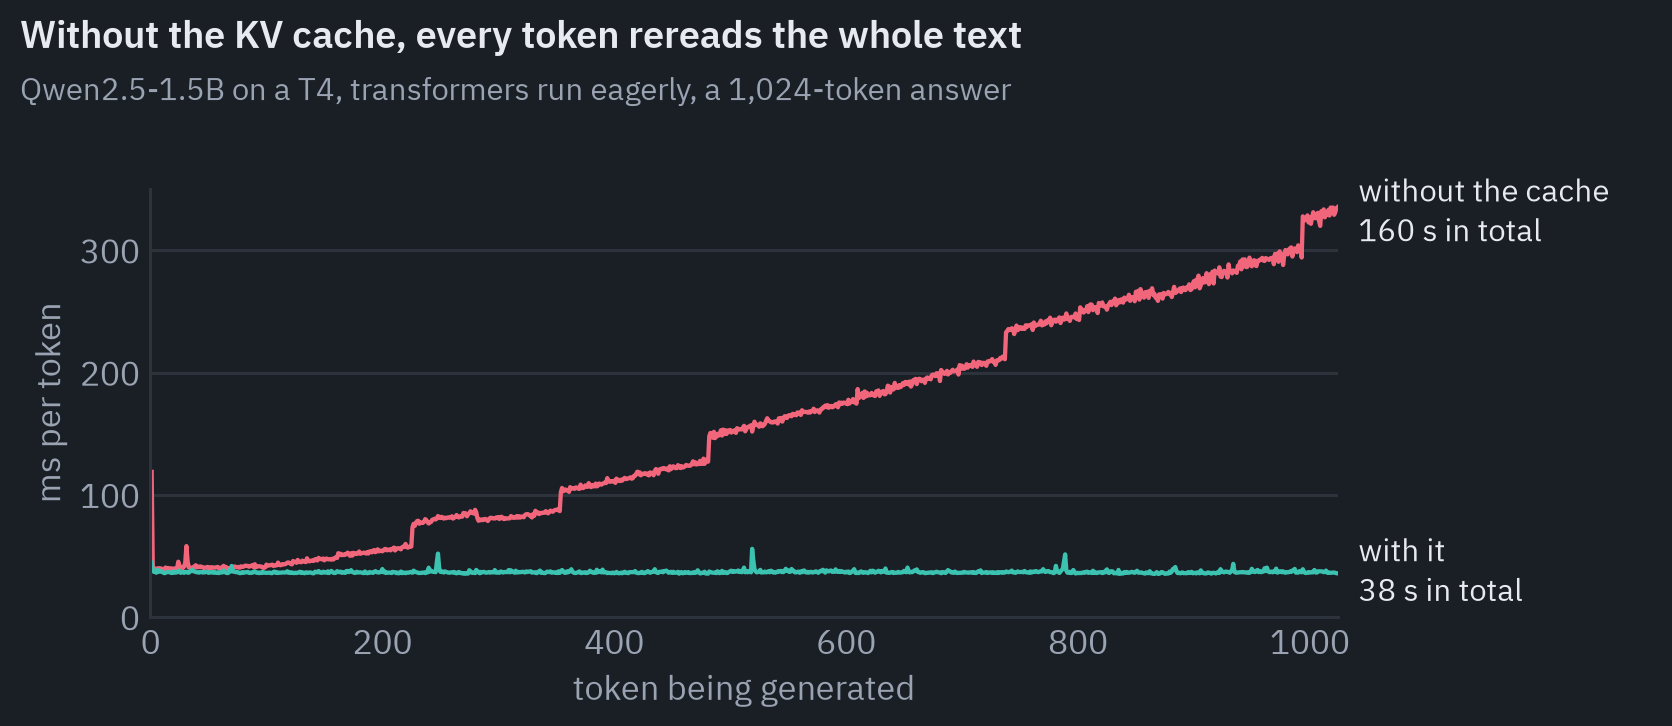
With the cache, every step costs the same 37 ms. Without it, step \(t\) processes all \(t\) tokens again, and the answer takes 160 seconds instead of 38. The cache trades that compute for memory, and memory is what runs out.
How much memory? Every layer stores one key and one value vector per KV head, for every token:
\[\text{bytes per token} = 2 \cdot L \cdot H_{kv} \cdot d_{\text{head}} \cdot b ,\]where the 2 counts keys and values, \(L\) is the number of layers, \(H_{kv}\) the number of key-value heads, \(d_{\text{head}}\) the size of a head, and \(b\) the bytes per number, 2 in bf16.
For Llama 3.1 70B that is \(2 \cdot 80 \cdot 8 \cdot 128 \cdot 2 = 327{,}680\) bytes, 320 KiB for every token of every conversation. One conversation at the model’s full 128K context takes 40 GiB, half of an H100.
The formula needs nothing but the model’s config.json:
import json
from huggingface_hub import hf_hub_download

def kv_bytes_per_token(config, bytes_per_value=2):
    layers = config["num_hidden_layers"]
    if "kv_lora_rank" in config:  # MLA: one compressed vector plus the key's positional part
        per_layer = config["kv_lora_rank"] + config["qk_rope_head_dim"]
    else:
        heads = config["num_attention_heads"]
        kv_heads = config.get("num_key_value_heads", heads)
        head_dim = config.get("head_dim") or config["hidden_size"] // heads
        per_layer = 2 * kv_heads * head_dim
    return layers * per_layer * bytes_per_value

config = json.load(open(hf_hub_download("unsloth/Meta-Llama-3.1-70B", "config.json")))
print(kv_bytes_per_token(config) // 1024, "KiB")
320 KiBThe same function over a few well-known models:
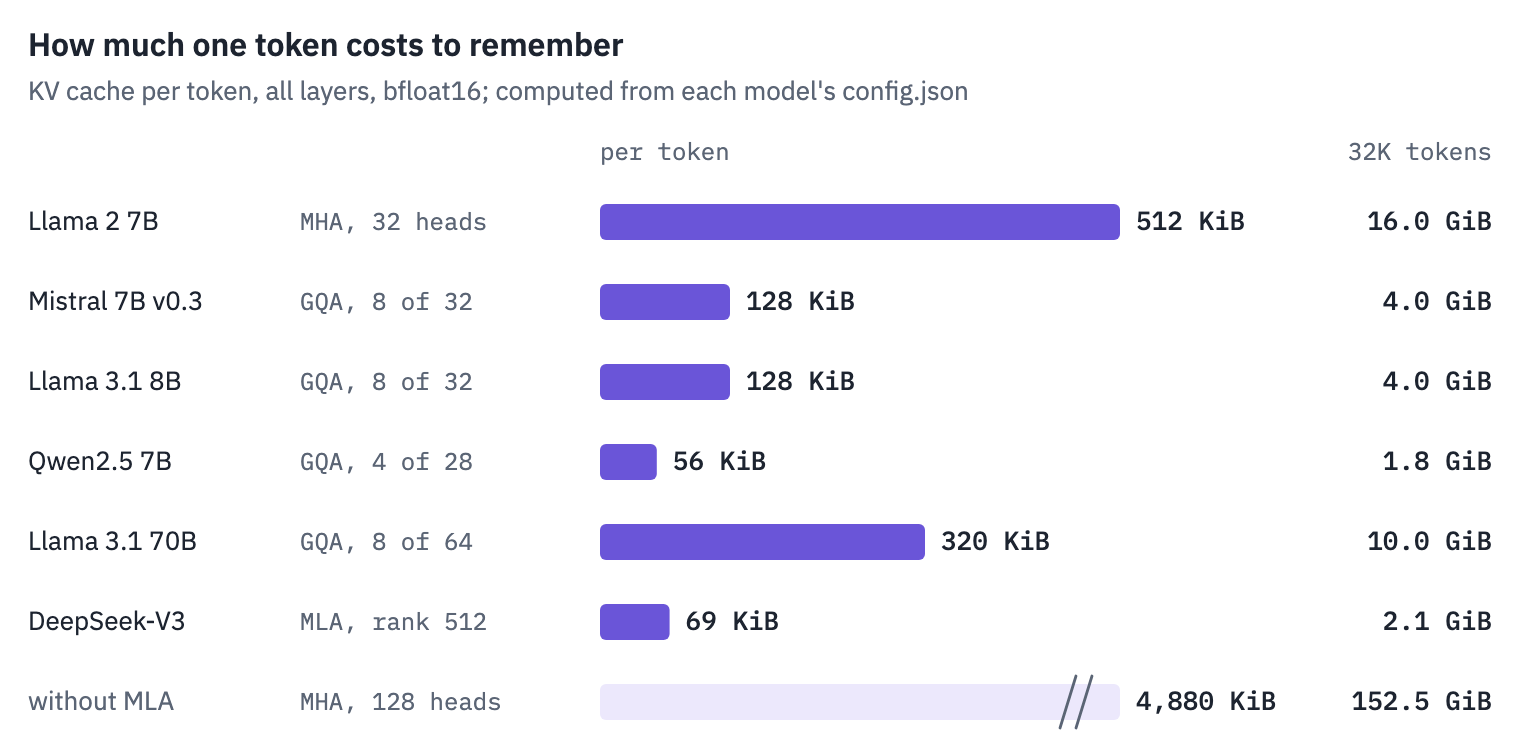
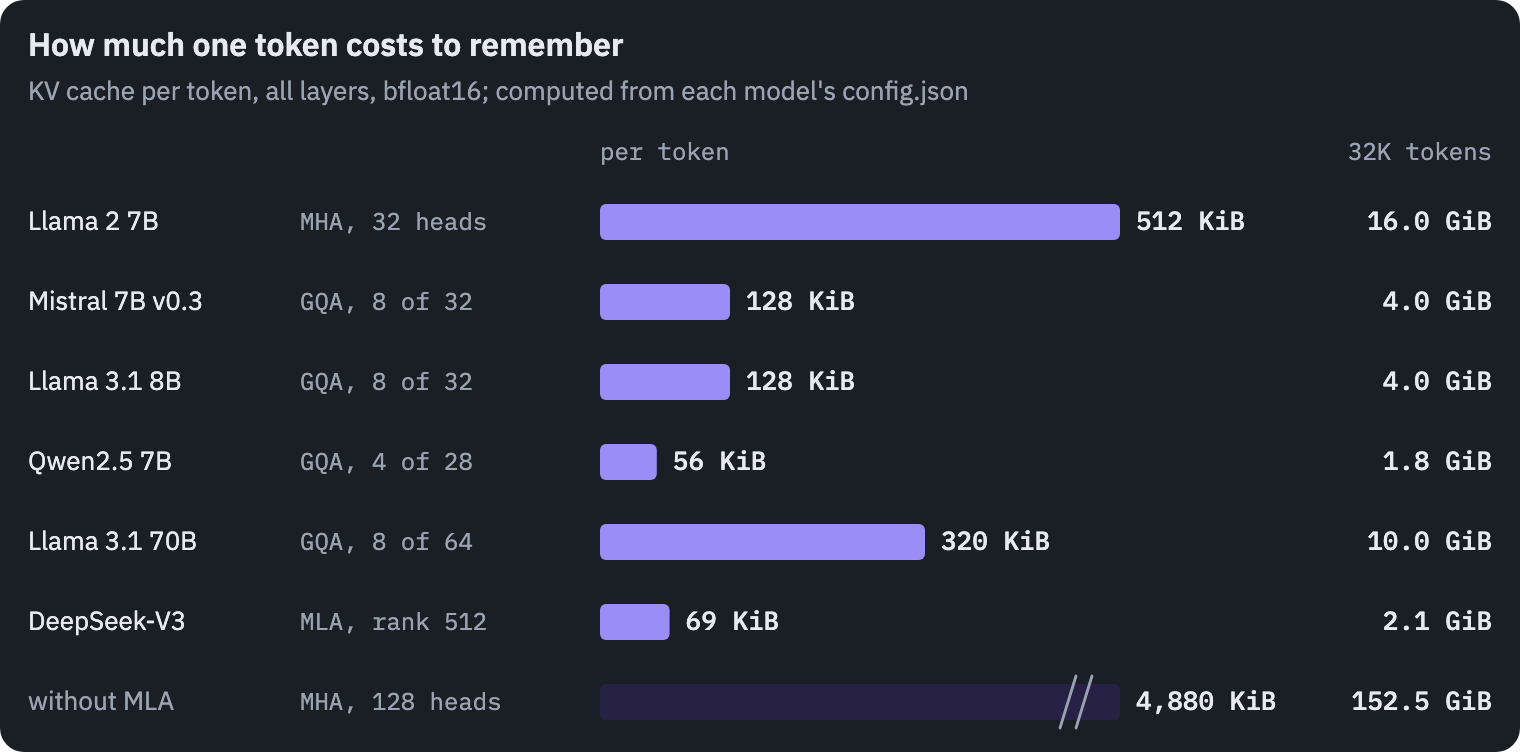
Llama 2 7B and Llama 3.1 8B have the same hidden size and differ fourfold. A formula you will often see, \(2 \cdot L \cdot d_{\text{model}} \cdot b\) bytes per token, is right for the first and four times too large for the second. Newer models don’t give every attention head its own keys and values:
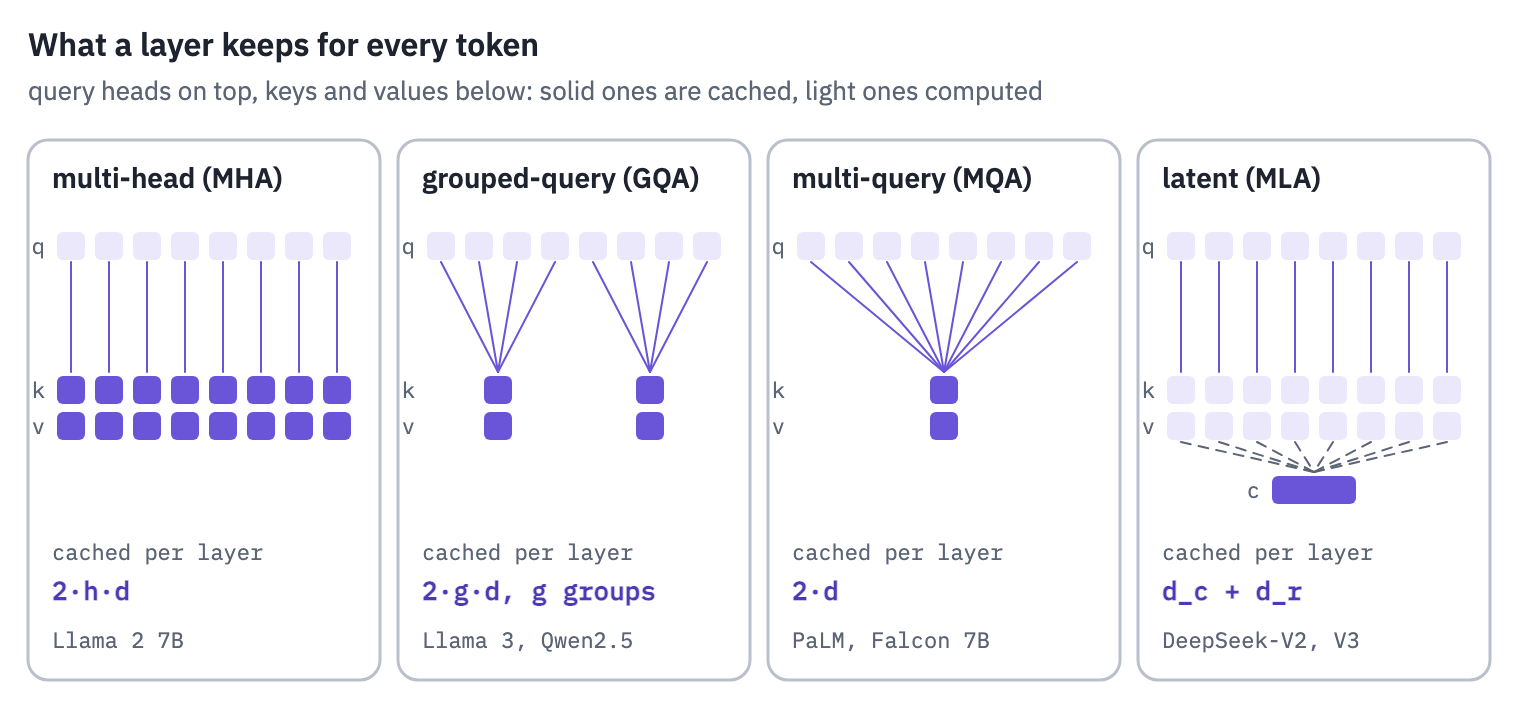
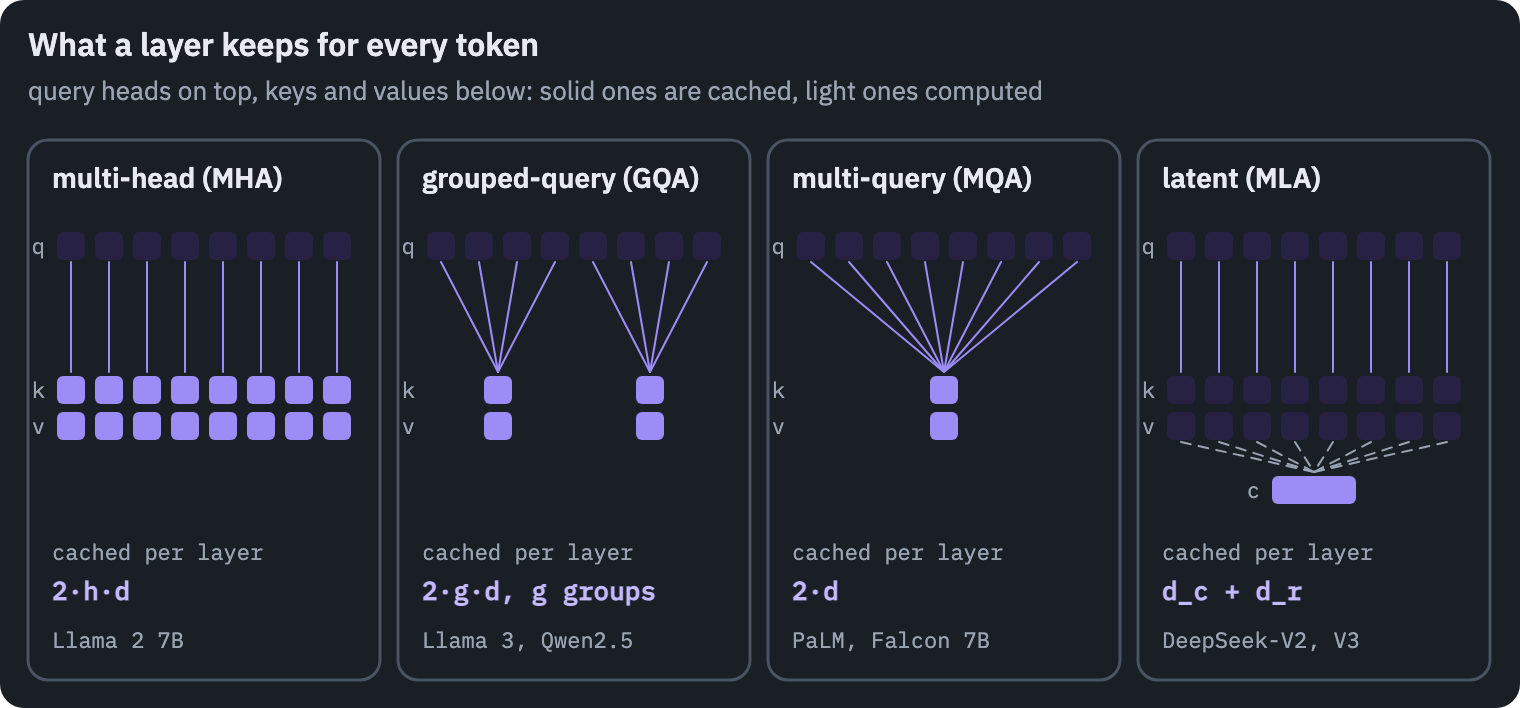
- Multi-head attention (MHA), the original design: every query head has its own key and value head.
- Multi-query attention (MQA), Shazeer, 2019: all heads share one key and one value. The cache shrinks by the number of heads, and quality suffers somewhat.
- Grouped-query attention (GQA), Ainslie et al., 2023, the middle ground: each group of query heads shares a key-value head. Llama 3 has 8 of them for 32 or 64 query heads. The authors also show that an existing MHA model can be converted with further training on 5% of its original pre-training compute.
- Multi-head latent attention (MLA), from DeepSeek-V2: the cache holds one compressed vector per token and layer, 512 numbers in DeepSeek-V3, plus 64 for the part of the key that carries the position. Each head’s keys and values are computed from that vector when attention needs them. DeepSeek-V3 caches 69 KiB per token; with ordinary attention over its 128 heads it would need 4,880 KiB, seventy times more.
About a number that travels with MLA: DeepSeek-V2 “reduces the KV cache by 93.3%”, but that compares the whole deployed model with DeepSeek 67B, and the deployed cache is also quantized to about 6 bits per number. Counting numbers alone, MLA gives 82%: 60 layers of 576 against 95 layers of \(2 \cdot 8 \cdot 128\).
The size of the cache matters twice. It decides how many conversations fit next to the weights, and so how large a batch can be.
And every decoding step reads every sequence’s whole cache, which batching can’t share: the weights are read once for the batch, the cache once per sequence. With 16 sequences on the T4:
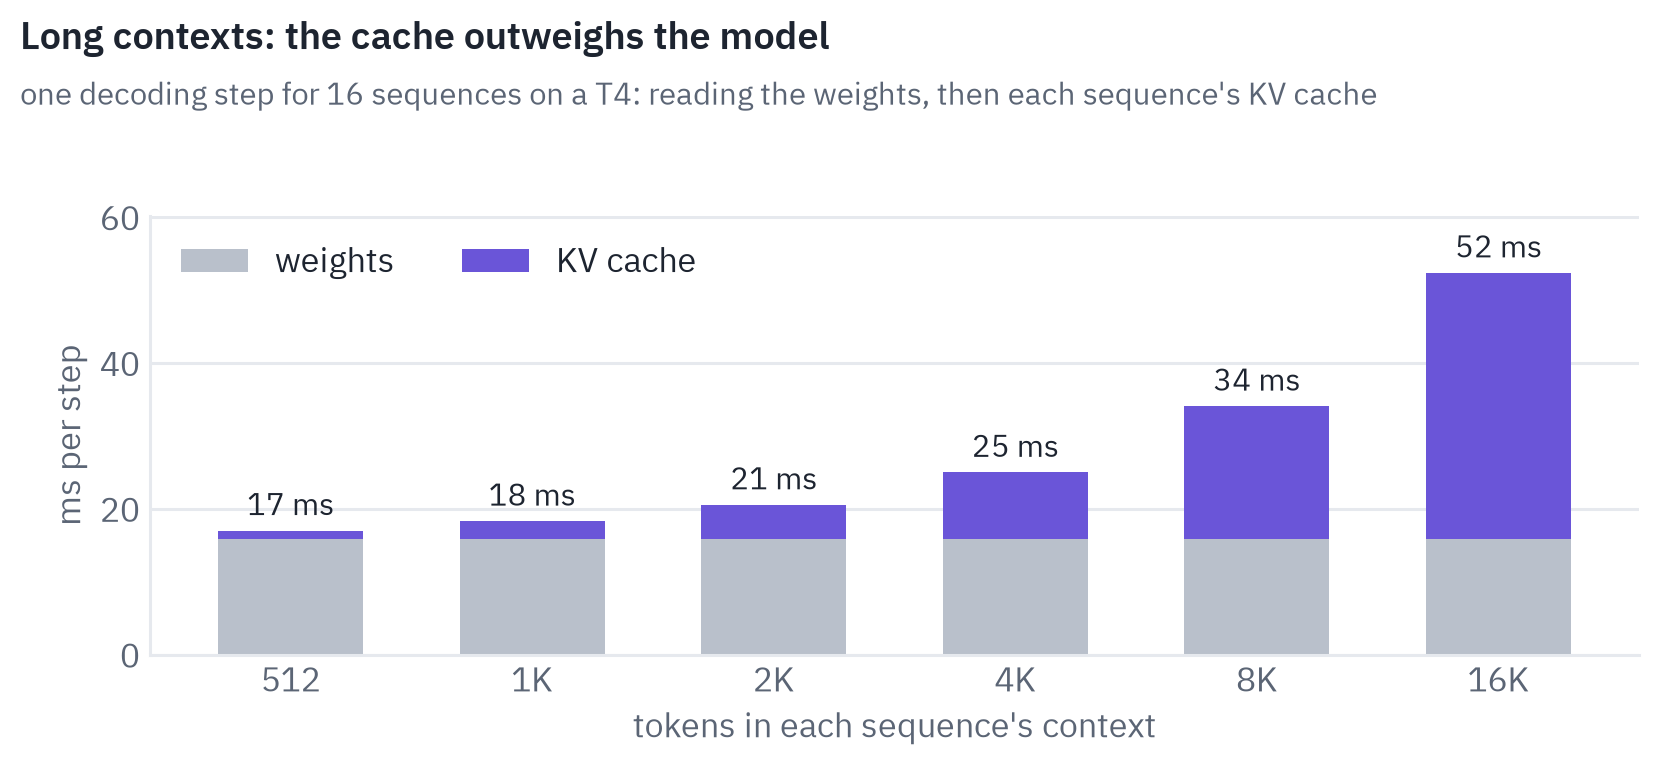
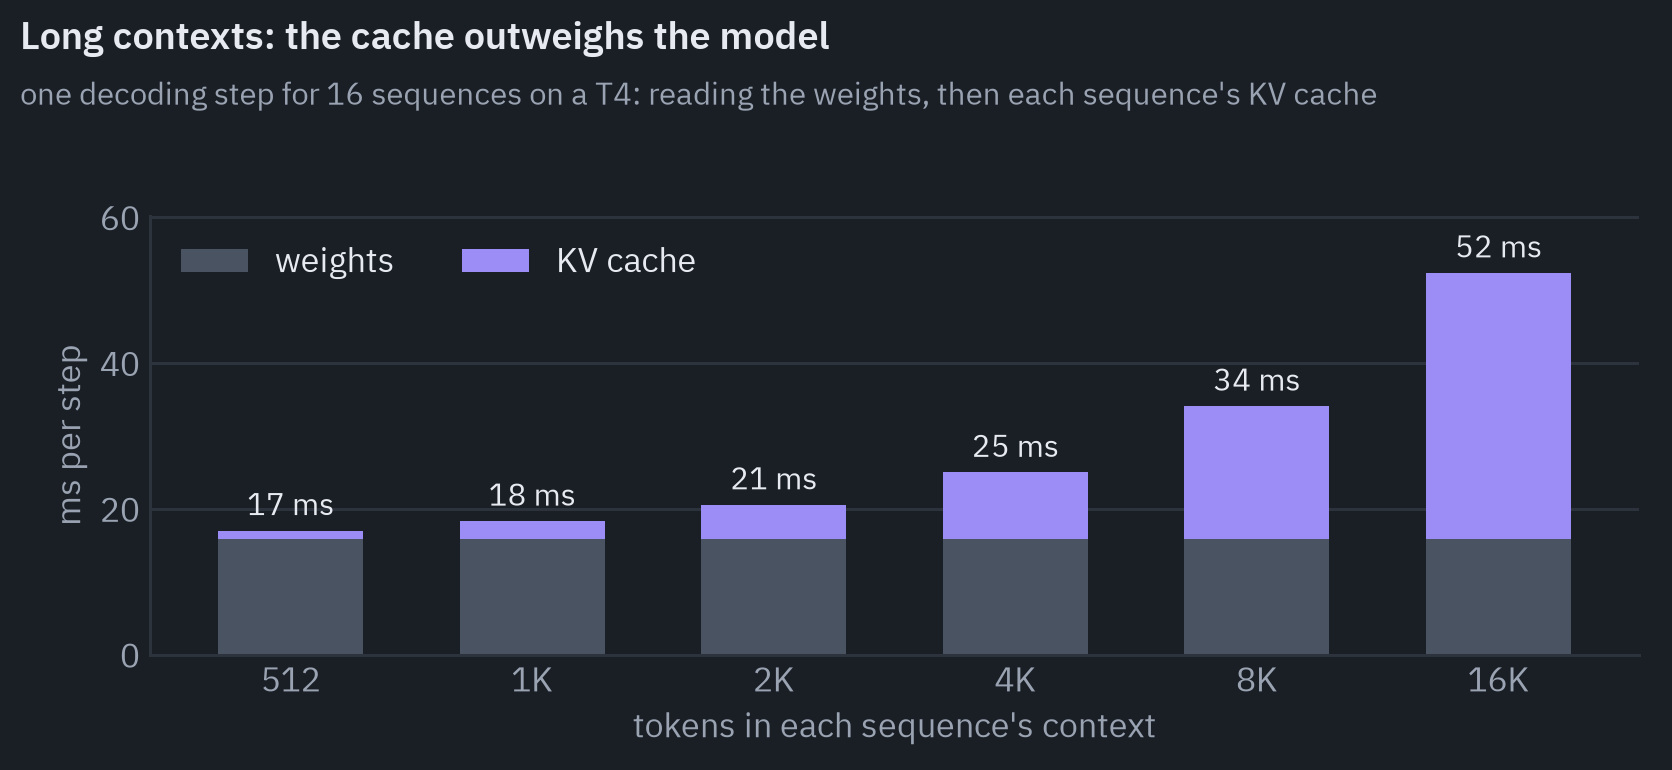
The cache adds less than a tenth to the step at 512 tokens of context, costs more than the whole model past about 7,000, and takes more than two thirds of the step at 16K.
This is why long contexts are slow and expensive per token, and some price lists say so: Claude Haiku 5.5 charges five times more per input token for prompts over 100,000 tokens.
Paging the cache
How much cache do you reserve for an answer whose length you don’t know? Early serving systems reserved the maximum, as one contiguous region per request, and most of it sat empty.
The vLLM paper measured that in those systems “only 20.4% - 38.2% of the KV cache memory is used to store the actual token states”. The rest was reserved for tokens never generated, or lost in the gaps between regions.
vLLM’s answer, PagedAttention, borrows virtual memory from operating systems. The cache is cut into fixed-size blocks, 16 tokens by default.
A sequence gets a new block when it fills the last one, anywhere in memory, and a block table maps its logical blocks to physical ones. The attention kernel reads the cache through the table.
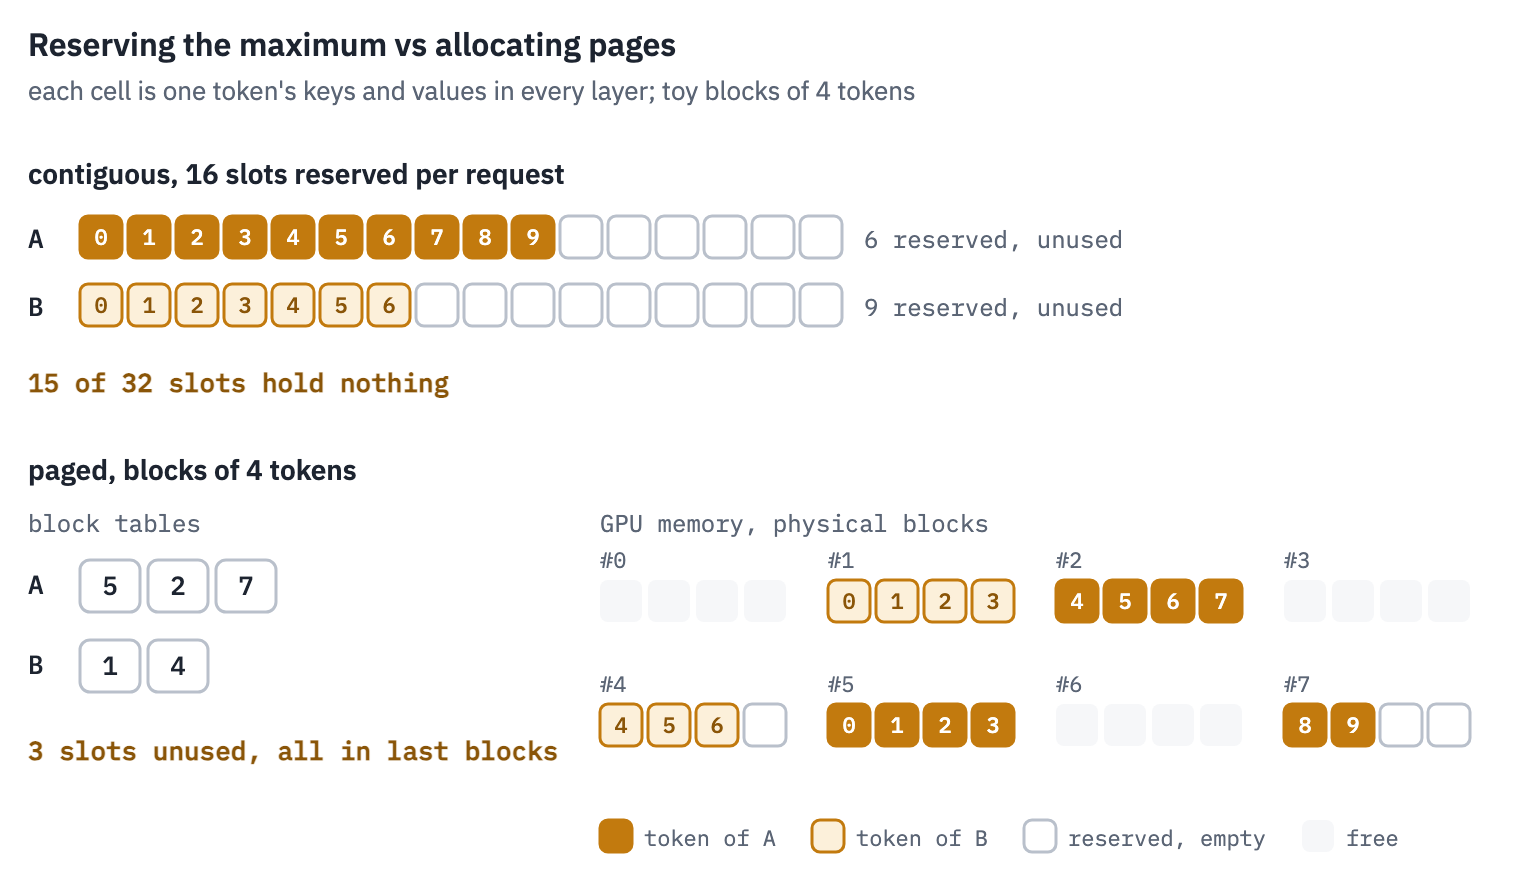
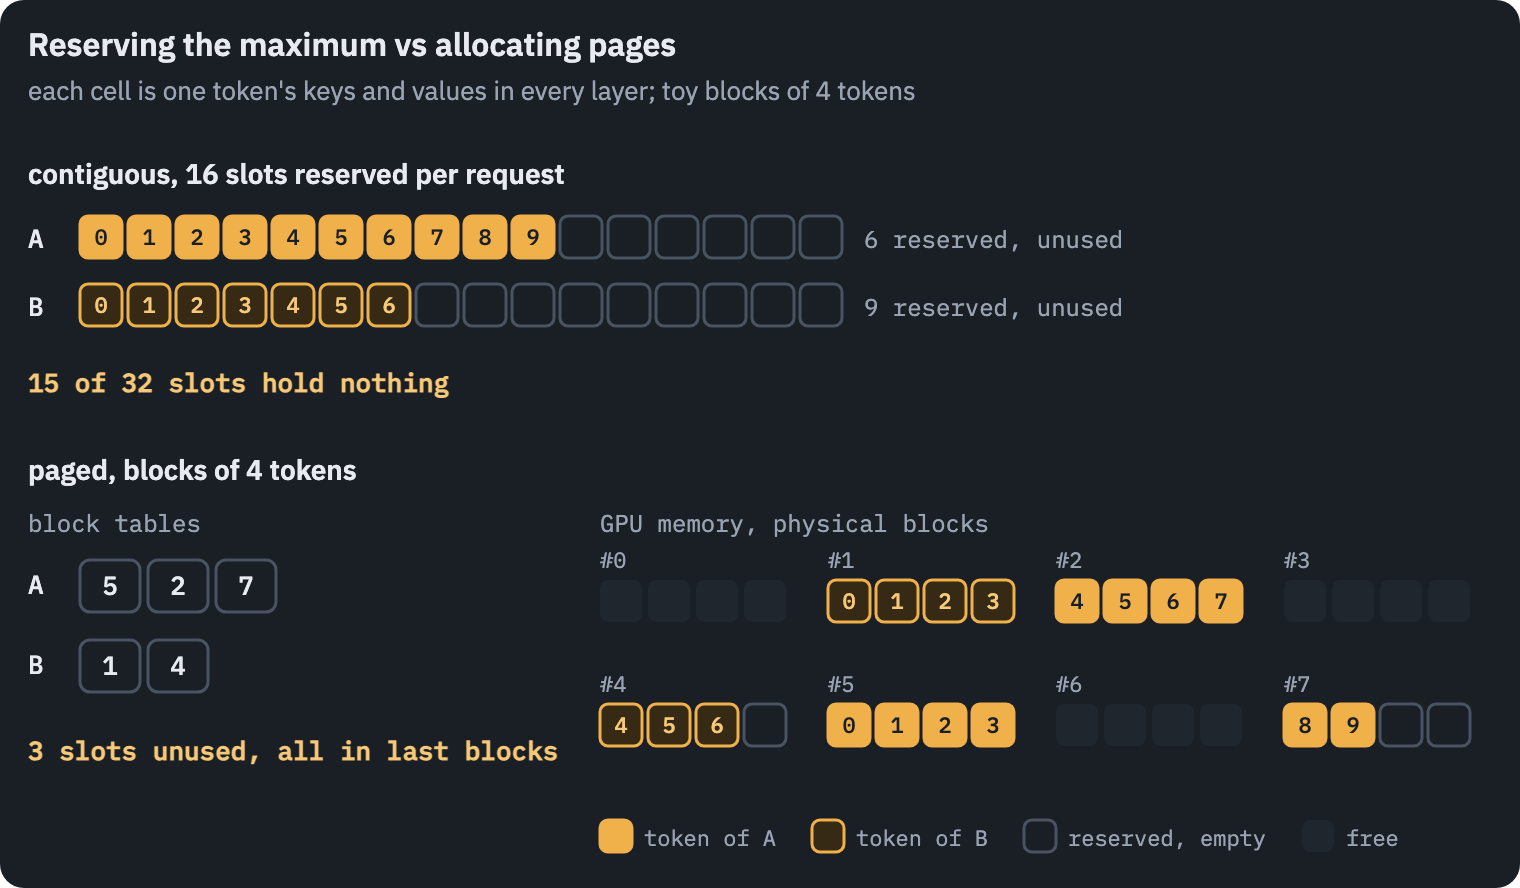
A sequence now wastes at most the empty part of its last block, under 4% of the memory in vLLM’s measurements. The freed memory becomes batch size, and batch size, as the previous sections showed, is throughput: the paper reports 2 to 4 times the throughput of FasterTransformer and Orca at the same latency.
Blocks can also be shared. Several samples from one prompt point at the same prompt blocks and copy a block only when one of them writes to it, copy-on-write, the way fork() shares memory between processes. The paper measured 6 to 10% less memory for parallel sampling and 38 to 55% less for beam search.
The same sharing across requests is prefix caching. When a new request starts with tokens the engine has already processed (the same system prompt, the same tool definitions, the same document), it reuses their blocks and skips their prefill. vLLM finds such blocks by hashing each one together with the blocks before it, and does it by default; SGLang’s RadixAttention keeps the prefixes in a tree.
Prefix caching only shortens the prefill and does nothing for decoding[1]. This is the cache hit on the price list.
In practice
When you build on an API, put what doesn’t change at the start of the prompt and what changes at the end: a single changed token invalidates the cache for everything after it.
Batching that never waits
Large batches need requests to batch together, and requests don’t arrive together. Static batching gathers a batch, runs it to the end, and only then takes the next. The batch is done when its longest answer is done, so the slots of short answers stand empty while new requests wait outside.
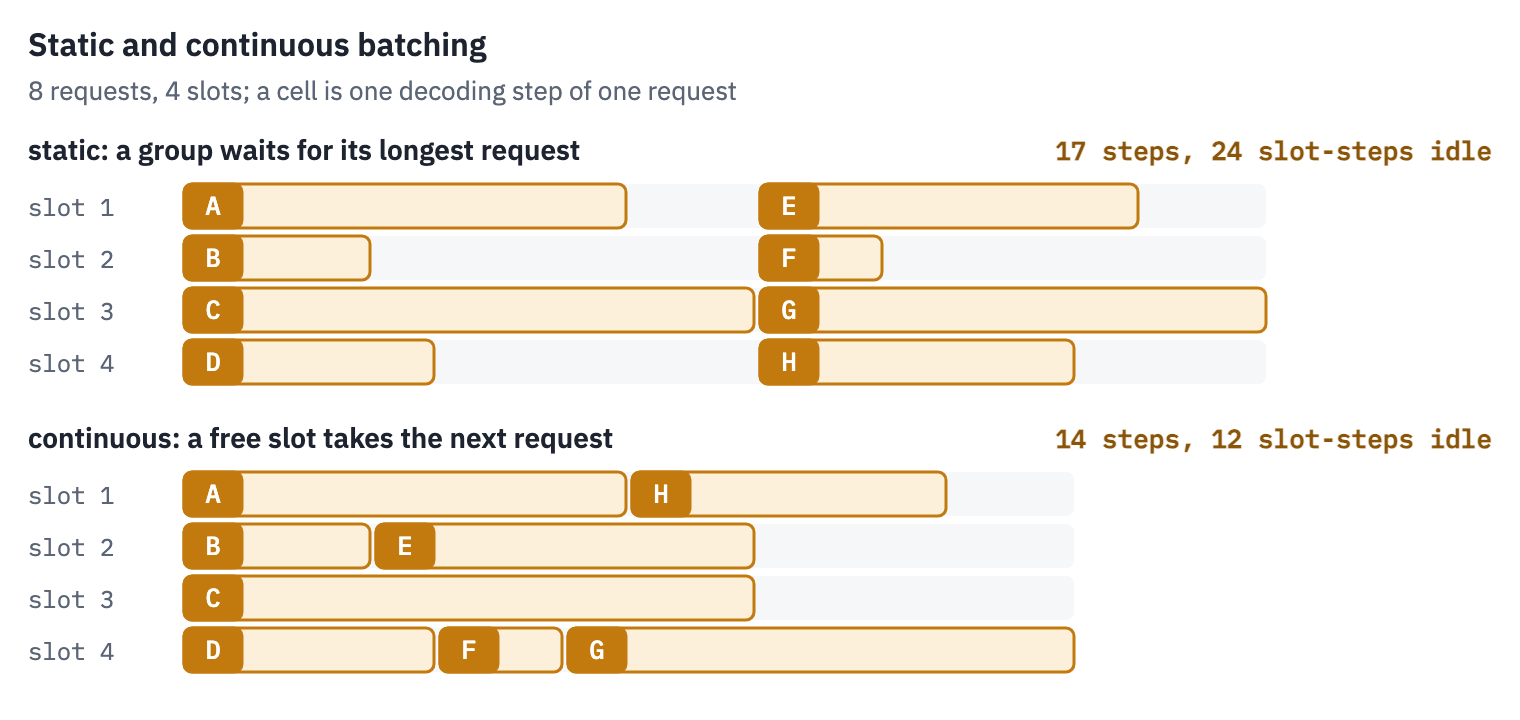
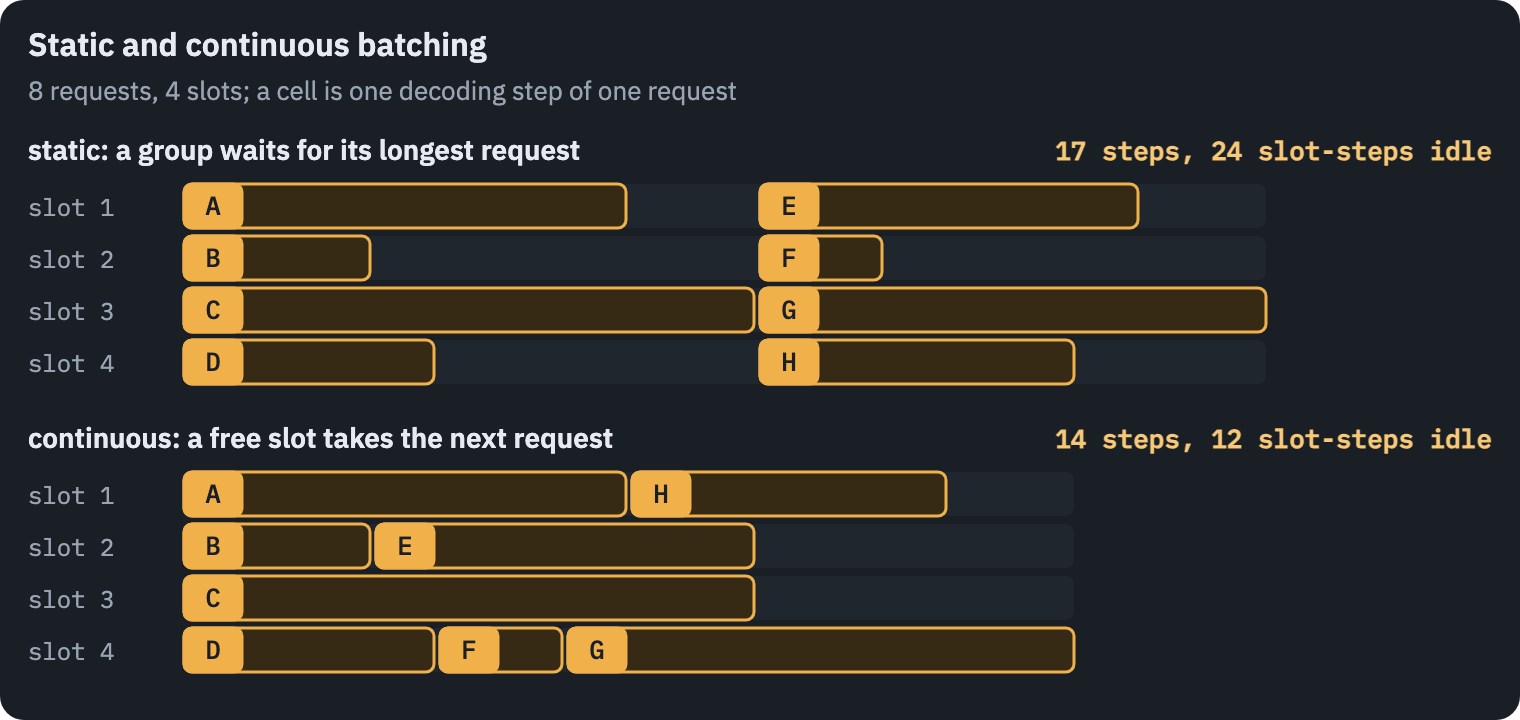
Orca (OSDI 2022) moved scheduling from the request to the iteration. After every decoding step the scheduler can drop finished sequences and add waiting ones, so no slot stays idle while requests wait.
What makes it possible is that sequences of different lengths don’t need to be padded into one tensor: the matrix multiplications run over all tokens of all sequences at once, and only attention runs per sequence, each against its own cache.
Orca reported 36.9 times the throughput of FasterTransformer on GPT-3 175B at the same latency. Under the name continuous batching it is now standard in serving engines.
In the toy above the gain is 17 steps against 14. With real traffic it is larger: answers range from one word to thousands of tokens, and a static batch always waits for the longest.
Continuous batching brought its own problem. A request joins the batch with its prefill, and the prefill of a long prompt is a long step. Every sequence in the batch waits for it, and their users watch the stream freeze.
Sarathi-Serve (OSDI 2024) calls these generation stalls and removes them with chunked prefill: the prompt is cut into chunks, and each step carries one token for every running sequence plus one chunk, up to a budget of tokens per step.
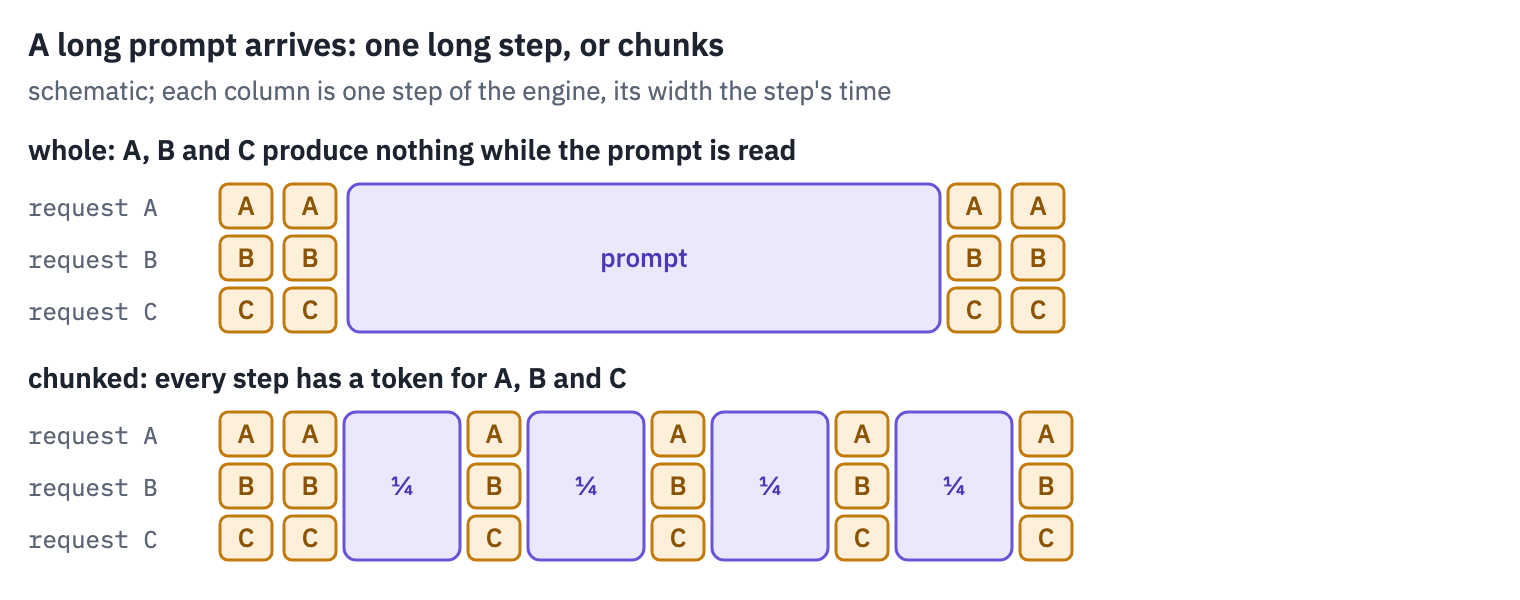
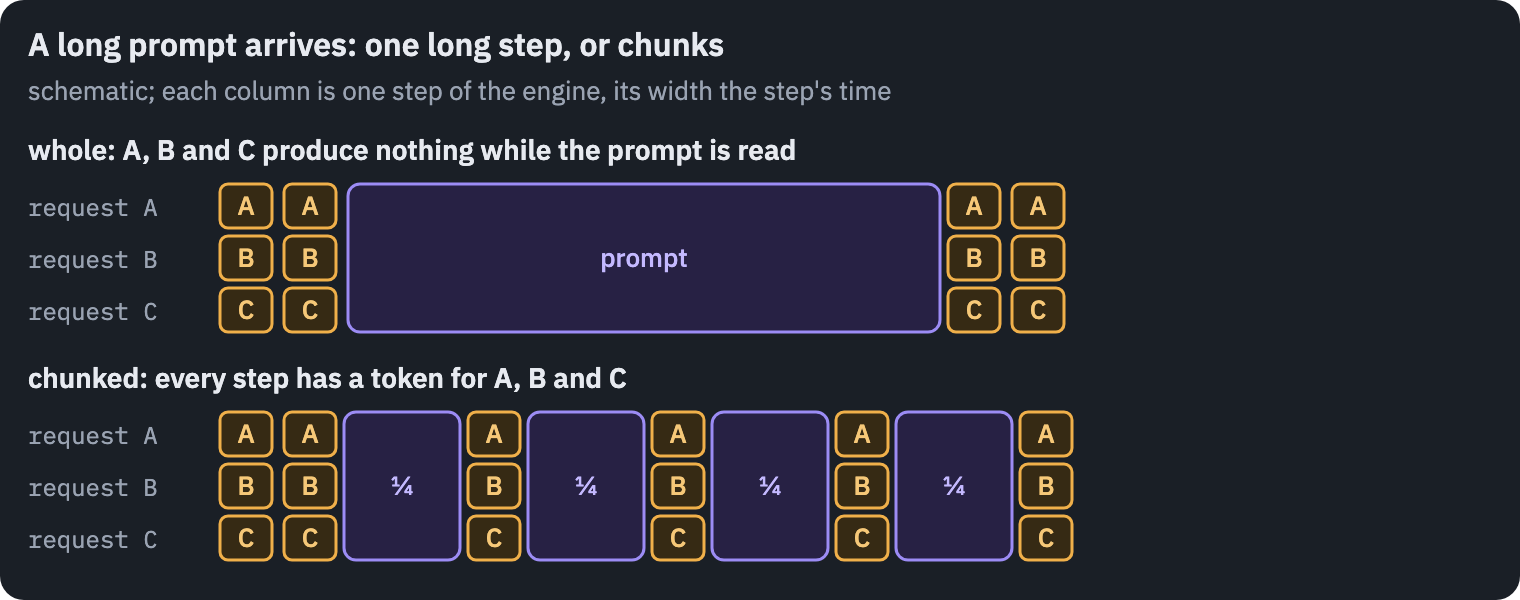
Decoding steps get a little slower and stop freezing. The paper reports 2.6 times the serving capacity of vLLM for Mistral-7B under the same latency targets, and up to 5.6 times for Falcon-180B. In vLLM the budget is max_num_batched_tokens, and it is the knob between the two phases: a larger budget gives faster prefills and slower decoding steps.
The other way out is to separate the phases. Disaggregated serving runs prefills on one set of GPUs and decoding on another, and moves each request’s cache between them.
Each pool is sized and tuned for one kind of work; DistServe reports up to 7.4 times more requests within the same latency targets. The price is moving the cache, which for a long conversation on a large model is gigabytes.
When the cache runs out. A batch grows until the cache is full. Then sequences that are still generating need new blocks, and there are none. vLLM preempts: it evicts a request, frees its blocks, and later rebuilds the request’s cache from its text, which costs another prefill.
(The vLLM paper also describes swapping blocks to CPU memory; the current scheduler only recomputes.) A few preemptions at peak load are normal. Many mean the batch is larger than the memory: lower max_num_seqs, shorten the maximum context, quantize, or add GPUs.
How many sequences will the engine hold at once? Little’s law answers it for any stable queue:
\[L = \lambda \, W ,\]the average number of requests in the system, \(L\), equals their arrival rate \(\lambda\) times the average time each spends inside, \(W\). At 10 requests per second and 12 seconds per request, 120 requests are in flight.
If each brings a 4,096-token context to Llama 3.1 8B, their cache takes \(120 \cdot 4096 \cdot 128\ \text{KiB} = 60\ \text{GiB}\). One H100 has room for about 57 GiB next to the weights (see the next section). Such a service hits preemptions at its average load, before any peak.
Fewer bytes per weight: quantization
Decoding reads every weight at every step, so a weight stored in fewer bytes is read sooner. In the memory-bound regime the gain is direct: half the bytes, up to twice the tokens per second. Quantization also frees memory for the cache, and on large models that is often the bigger win:
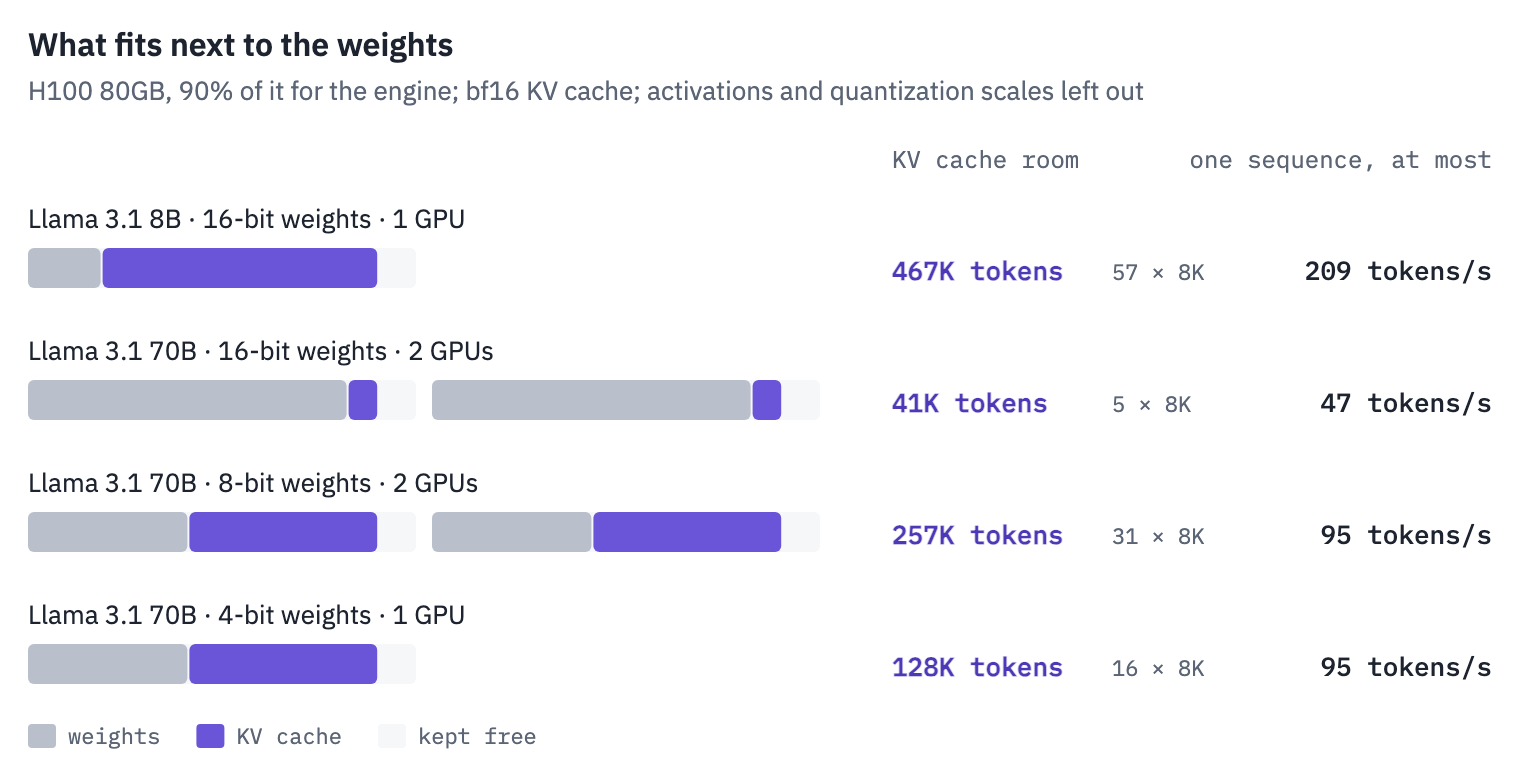
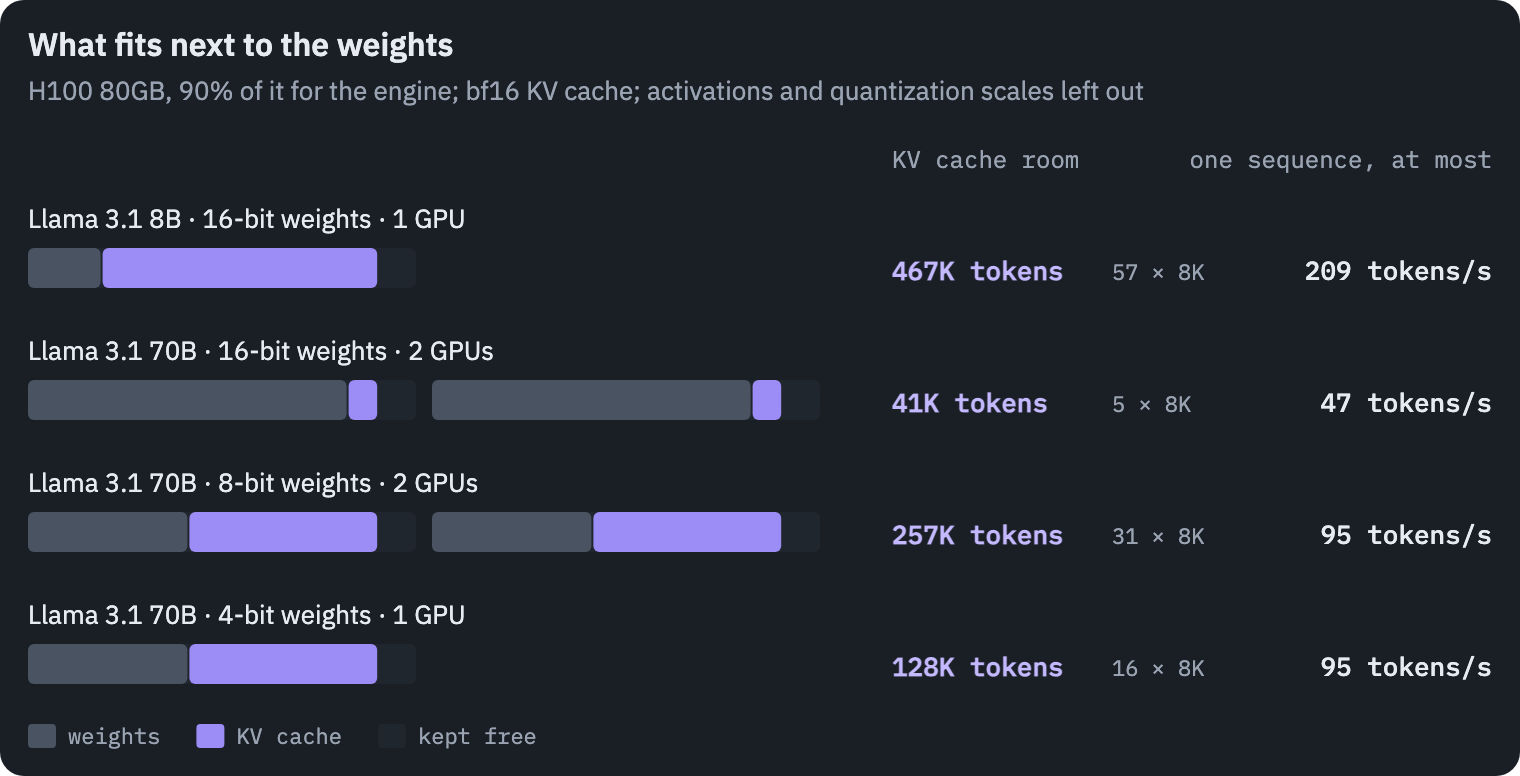
Llama 3.1 70B in 16 bits barely fits on two H100s. With 90% of their memory given to the engine, vLLM’s default, there is room for 41,000 tokens of cache: five conversations of 8K. In 8 bits, the same two GPUs hold six times more cache and double the ceiling for one sequence.
In 4 bits the model fits on one GPU with room for 128,000 tokens. The bars leave out the engine’s memory for activations and the scales that quantized formats store, so real numbers are somewhat lower.
The methods differ in what they quantize:
- Weights only. Weights are stored in 4 or 8 bits and multiplied in 16. GPTQ chooses how to round each weight using second-order information and quantizes a 175B model in about four GPU hours. AWQ observes that “protecting only 1% salient weights can greatly reduce quantization error”, finds those weights from activation statistics, and protects them by scaling rather than by keeping them in higher precision. Weight-only formats speed up memory-bound decoding. At large batches, where the step is compute-bound, unpacking the weights is extra work, and they can be slower than 16 bits.
- Weights and activations. With both in 8 bits, the GPU’s 8-bit arithmetic does the multiplication too. LLM.int8() showed why this is hard: from about 6.7B parameters, a few hidden dimensions carry values far larger than all the others, in every layer. The method keeps those dimensions in 16 bits and multiplies the rest, more than 99.9% of the values, in 8. On H100s, FP8 doubles the dense tensor throughput, from 989 to 1,979 TFLOPS, so the prefill gets faster as well.
- The KV cache. Stored in 8 bits, it takes half the memory, and twice the context or twice the batch fits.
How much quality a format costs depends on the model, the method and the task.
Trap
Measure a quantized model on your own task, before and after: an average over general text, such as perplexity, can hide losses in exactly the cases you care about, such as arithmetic, code or a less common language.
Guessing ahead: speculative decoding
The roofline has a strange gift. A decoding step reads all the weights to produce one token, and reading them to check five tokens costs about the same, because the step is memory-bound either way.
Speculative decoding[2, 3] makes use of it. A small draft model, cheap to run, proposes \(\gamma\) tokens one by one. The large target model reads all of them in a single forward pass, which gives its own prediction at every position.
The proposals are accepted up to the first one the target disagrees with, and there the target’s own token is taken instead. Every round yields at least one token and at most \(\gamma + 1\).
Here is a real round. Qwen2.5-0.5B drafts for Qwen2.5-1.5B, and both take their most likely token:
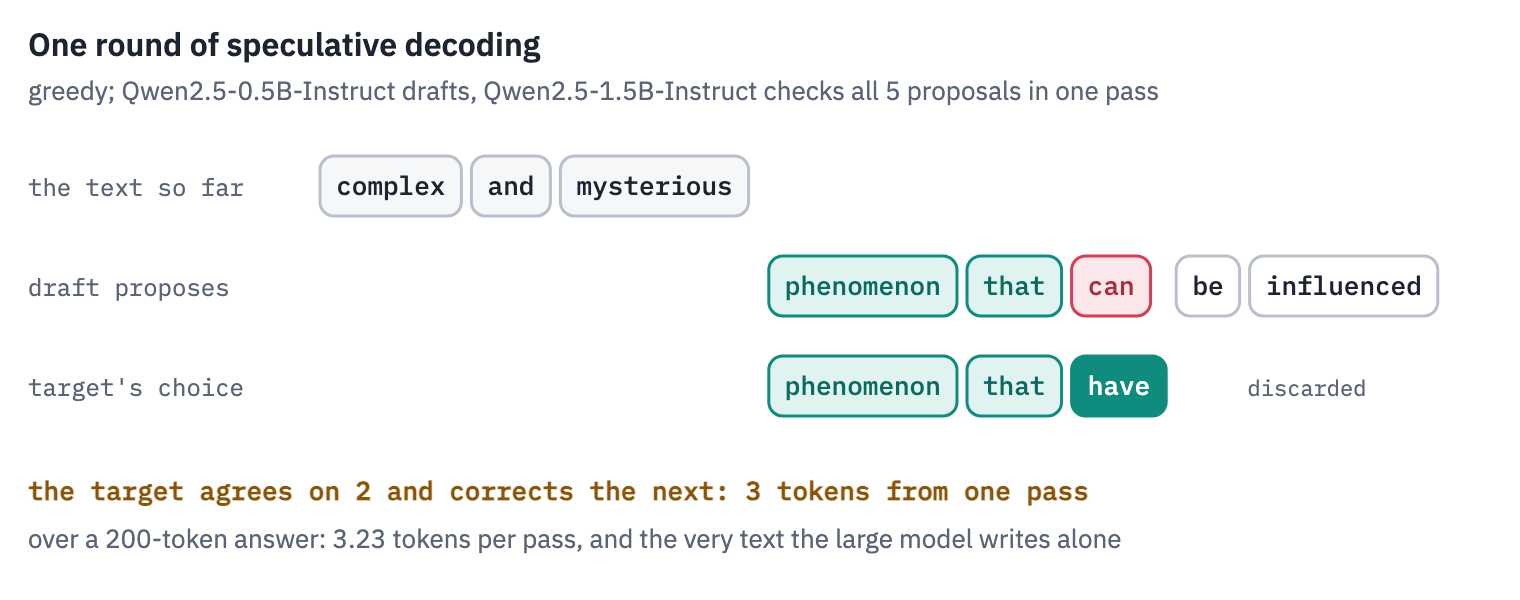
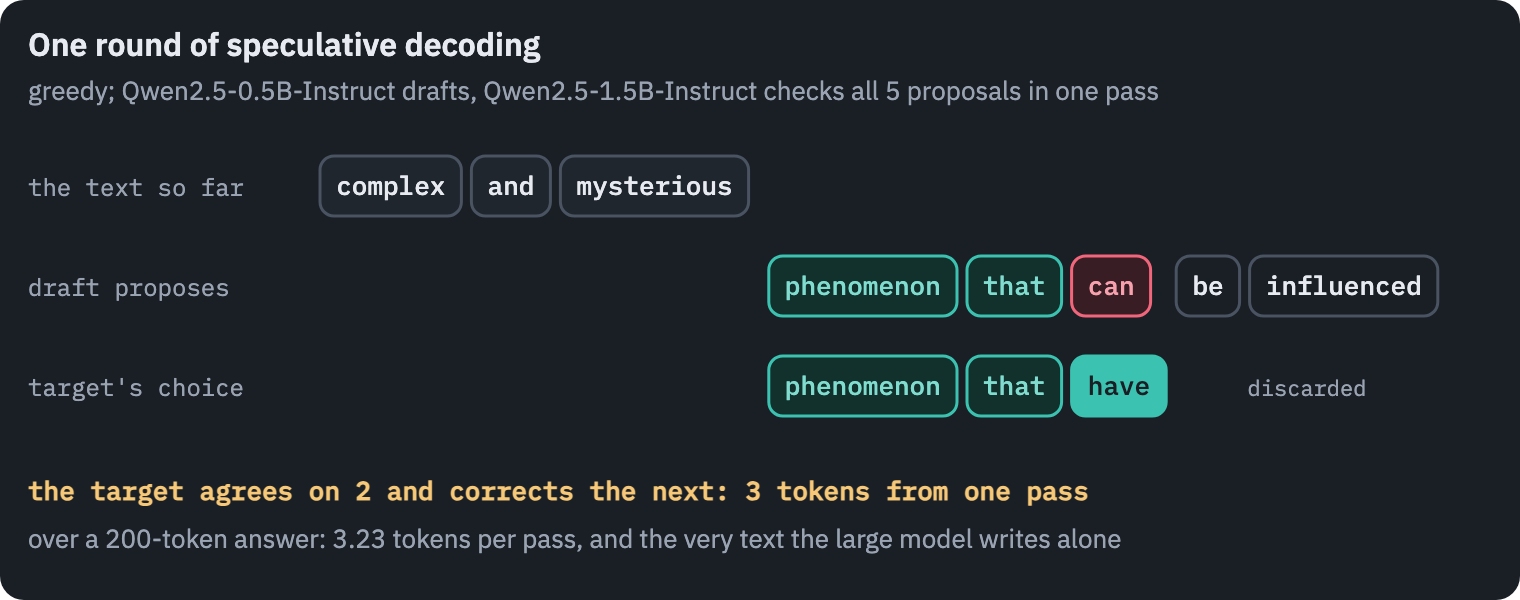
With greedy decoding, acceptance means that both models choose the same token, and the text is exactly what the target would write alone. I checked: the 200 tokens produced this way are identical to plain greedy decoding with the target.
With sampling, the papers accept each proposal with probability \(\min\left(1, p(x)/q(x)\right)\), where \(p\) and \(q\) are the target’s and the draft’s probabilities of the proposed token, and on rejection they sample from what is left of \(p\). The output then follows the target’s distribution exactly, “within hardware numerics”, as Chen et al. put it.
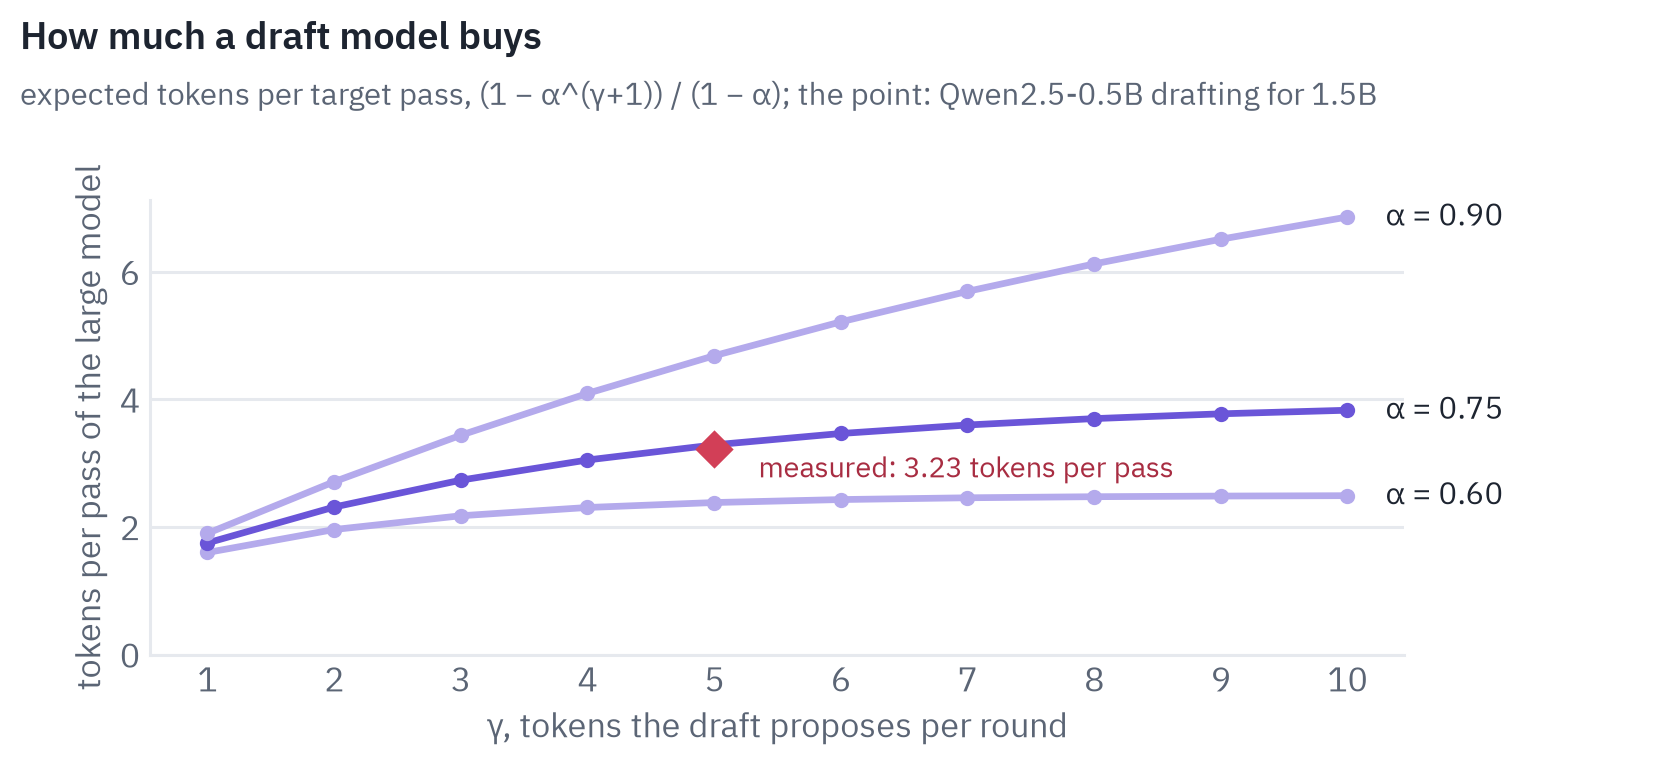
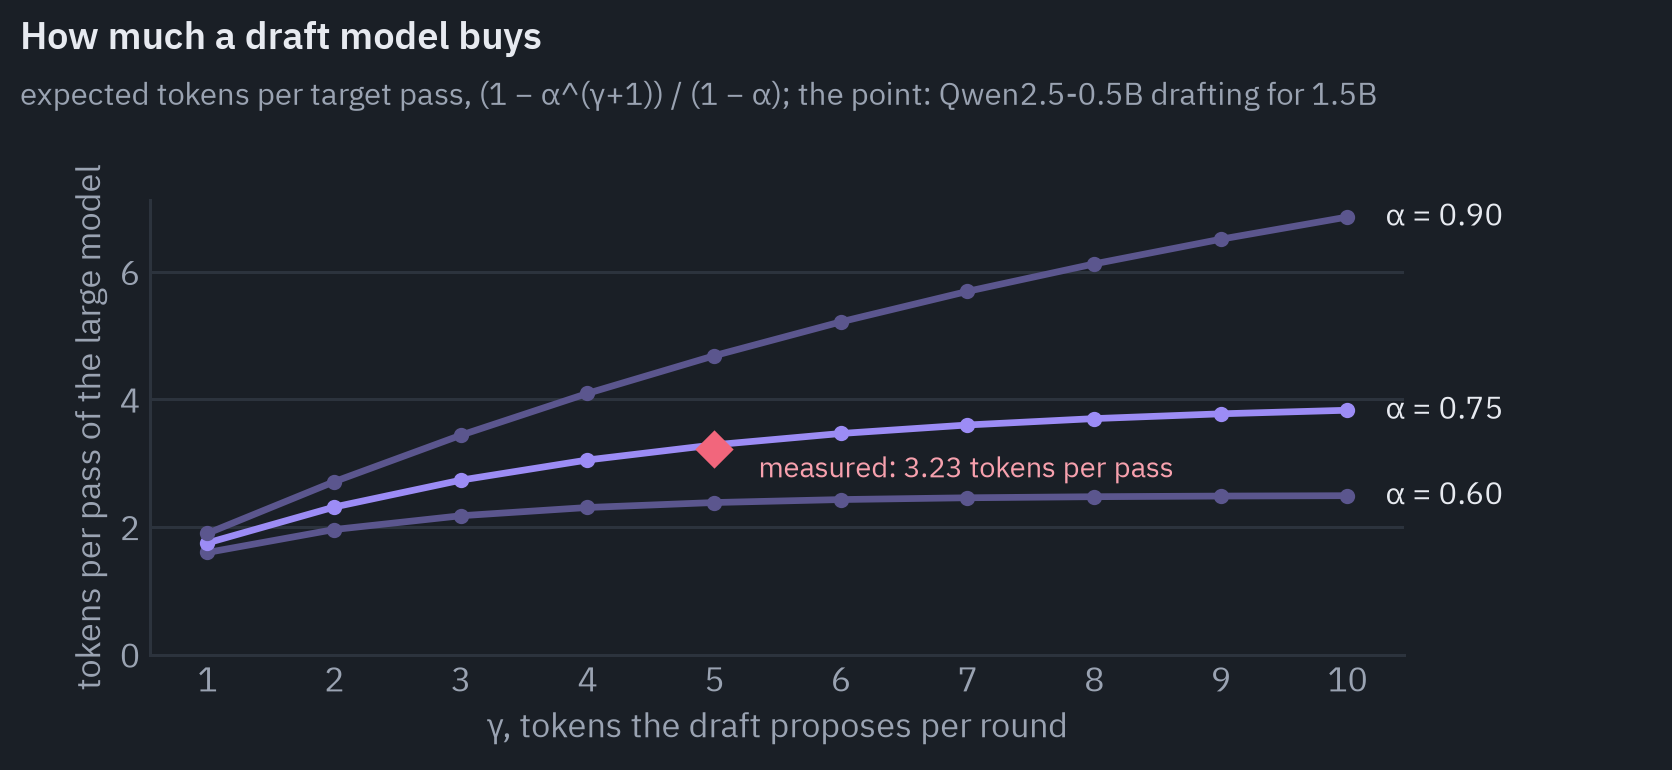
How many tokens does a round give? If each proposal is accepted with probability \(\alpha\), independently of the others, the expected number of tokens per pass of the target is (Leviathan et al., equation 1)
\[\mathbb{E}[\text{tokens}] = \frac{1 - \alpha^{\gamma + 1}}{1 - \alpha} .\]Read it as a sum. One token is certain. A second comes if the first proposal is accepted, with probability \(\alpha\); a third if the first two are, \(\alpha^2\); and so on up to \(\alpha^\gamma\).
The formula is this geometric series added up. Even a perfect draft gives no more than \(\gamma + 1\) tokens, and a weak one no more than \(1/(1-\alpha)\), however far ahead it guesses.
On a 200-token answer the 0.5B draft and the 1.5B target agreed often enough for \(\alpha = 0.75\), estimated from how many proposals each round accepted. The formula then predicts 3.29 tokens per pass, and the measured 3.23 is close:
Tokens per pass are not yet speed. The draft runs \(\gamma\) times per round, and if a draft pass costs a fraction \(c\) of a target pass, the expected speedup is (Leviathan et al., theorem 3.8)
\[\text{speedup} = \frac{1 - \alpha^{\gamma + 1}}{(1 - \alpha)(\gamma c + 1)} .\]Our pair is badly matched for it. Decoding is memory-bound, so a pass costs about in proportion to the parameters it reads: \(c \approx 0.49 / 1.54 = 0.32\), and with \(\gamma = 5\) the speedup is \(3.29 / 2.6 \approx 1.26\).
A draft a hundredth of the target’s size would give 3.1 with the same \(\alpha\); in Leviathan et al.’s experiments, drafts about two orders of magnitude smaller than the target usually did best.
In practice the draft often isn’t a separate model at all. Medusa and EAGLE attach small extra heads to the target itself that predict further ahead; n-gram lookup drafts by copying from the prompt, which works when the answer quotes it, as in code editing.
DeepSeek-V3 trains a module that predicts one more token alongside the model, and its report gives an acceptance rate of 85 to 90% for that token and 1.8 times the tokens per second.
The gift has a condition. Checking \(\gamma\) tokens is nearly free only while the step is memory-bound.
a large batchthe GPU is already busy computingthe extra positions cost real timethe speedup shrinks or turns into a slowdown
Speculative decoding buys latency when the load is light; measure it under the load you actually have.
Attention kernels
The prefill computes attention between every pair of prompt tokens. Written plainly, attention puts the score matrix, \(T \times T\) for every head, into GPU memory, and reads it back for the softmax and again for the weighted sum of values.
FlashAttention computes the same result in tiles that fit in the on-chip SRAM and never writes the full matrix out. It is exact, not an approximation, and its authors measured attention 7.6 times faster on GPT-2.
The quadratic part is visible on the T4: an 8,192-token prompt took 9.9 s to read, 4.2 times as long as 4,096 tokens, so at that length attention, not the weights, sets the time.
Decoding has one query per sequence and no large matrix to avoid; its cost is reading the cache, as the measurement above showed. What matters is how many of the GPU’s cores share that reading.
A kernel that gives each sequence and head to one block of threads leaves most of the GPU idle when the batch is small and the context is long.
Flash-Decoding also splits the cache along its length, computes attention over the pieces in parallel and combines them using each piece’s log-sum-exp, for “up to 8x faster generation for very long sequences”.
The kernel matters even for this simple job: on the T4, a fused attention kernel read the cache at about 200 GB/s, and the same attention written as two matrix products and a softmax at 91 GB/s.
More than one GPU
When the weights don’t fit on one GPU, or one GPU decodes too slowly, the model is split. Inside one server the usual way is tensor parallelism, as in Megatron-LM: every GPU holds a slice of every weight matrix.
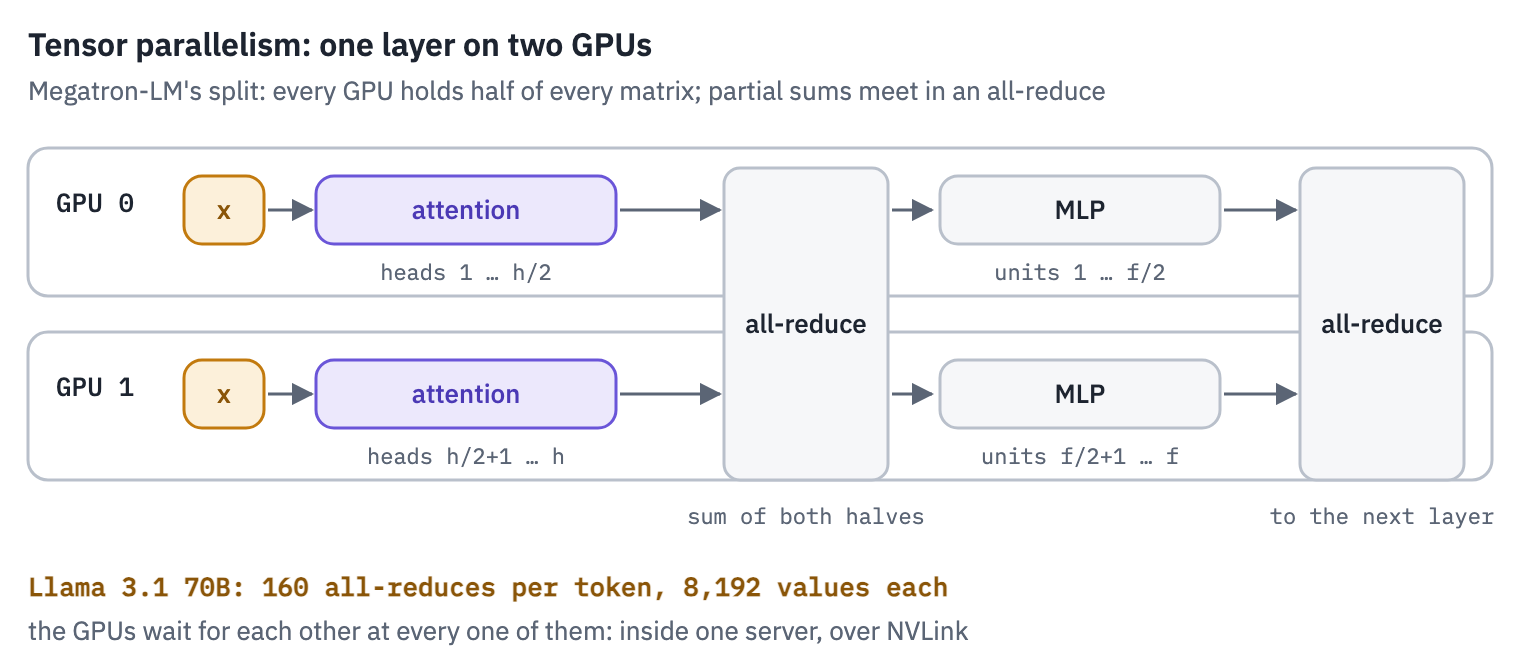
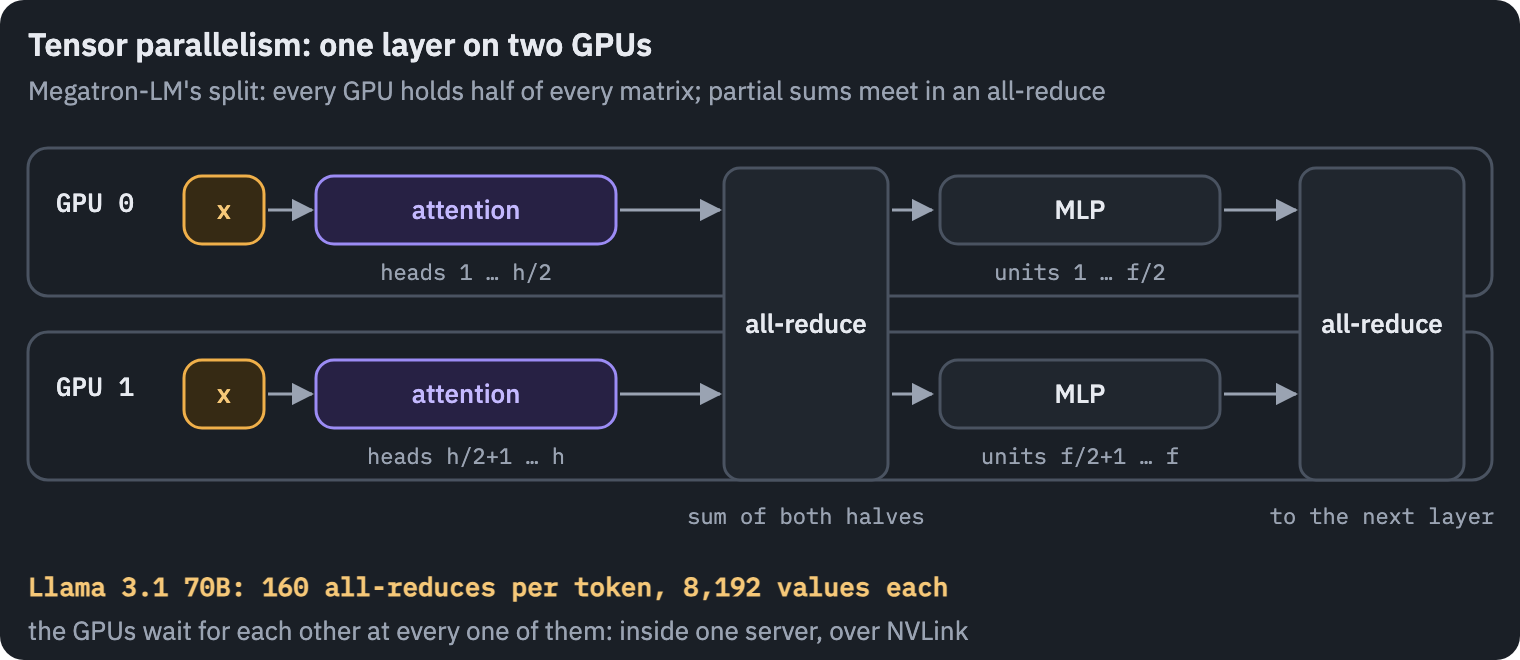
The attention heads are divided among the GPUs, and so is the MLP: its first matrix by columns, its second by rows. Each GPU then holds a partial sum of the block’s output, and an all-reduce adds the parts up, twice per layer in the forward pass.
Each GPU reads only its share of the weights, so their bandwidths add up, and two H100s decode Llama 3.1 70B about twice as fast as one would if the model fit.
The all-reduces are the price. Llama 3.1 70B makes 160 of them for every generated token, and at each one all GPUs wait for the slowest. The messages are small, 8,192 numbers per sequence, so the link’s latency matters as much as its bandwidth:
| link | bandwidth per direction |
|---|---|
| NVLink, H100 | 450 GB/s |
| NVLink, A100 | 300 GB/s |
| PCIe 5.0 x16 | 64 GB/s |
| PCIe 4.0 x16 | 32 GB/s |
| InfiniBand NDR, one port | 50 GB/s (400 Gb/s) |
NVIDIA quotes NVLink as the sum of both directions: 900 GB/s for H100 and 600 for A100. Tensor parallelism stays inside a server, on NVLink.
Across servers the model is split by layers instead, pipeline parallelism: each group of GPUs runs a range of layers and passes the activations on once per step. It needs far less communication, but a stage stands idle unless several batches are in flight at once.
Mixture-of-experts models add expert parallelism: DeepSeek-V3 sends every token to 8 of its 256 routed experts in each MoE layer, and the experts live on different GPUs.
The system around the engine
The engine is one box on a longer path, and every box on it can undo the engine’s work.
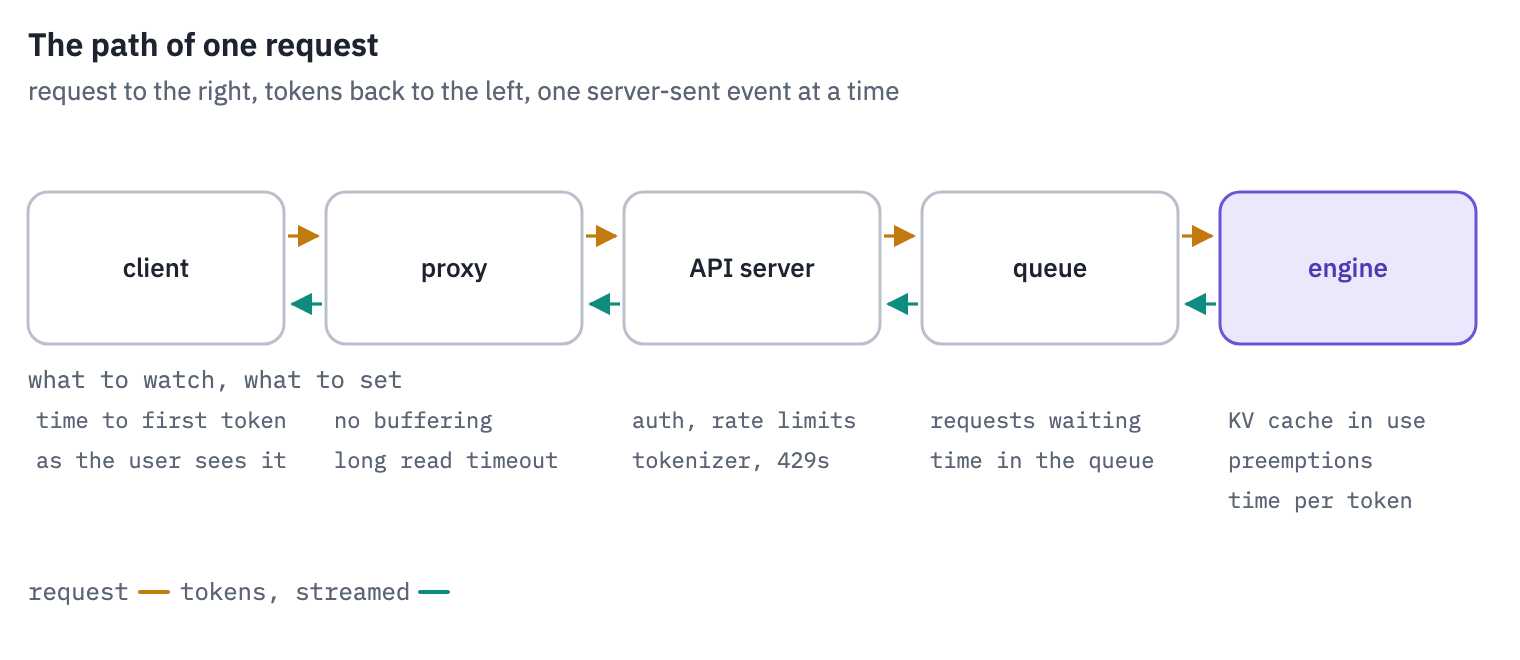
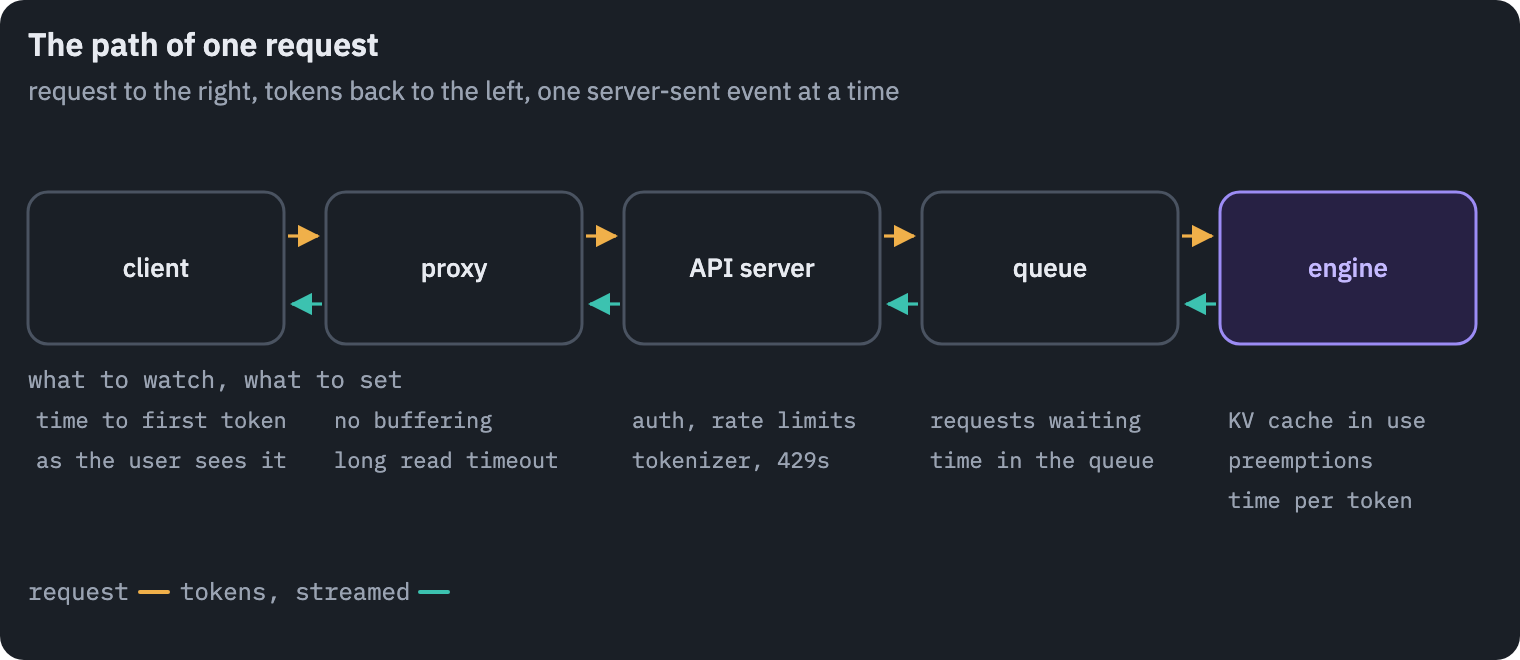
Streaming. Tokens go back to the client as they are generated, usually as server-sent events on one long HTTP response. Any hop that buffers the response turns the stream into a few bursts.
The classic one is nginx, which buffers proxied responses by default. Turn buffering off for the streaming location, or send X-Accel-Buffering: no from the application[4]:
location /v1/ {
    proxy_pass http://engine:8000;
    proxy_http_version 1.1;
    proxy_buffering off;
    proxy_read_timeout 300s;  # the default 60 s can run out before the first token
}
If tokens still arrive in clumps, look lower. Nagle’s algorithm holds a small write until the previous one is acknowledged, and Linux delays acknowledgements by 40 to 200 ms; a server turns Nagle off on the socket with TCP_NODELAY.
Queues and backpressure. Little’s law tells how many requests are inside at a given rate. When requests arrive faster than the GPUs serve them, the queue grows without limit, and everyone in it eventually times out after the longest possible wait.
A bounded queue with fast rejection is kinder: answer 429 with a Retry-After header when the expected wait exceeds what the client will tolerate, and let the client retry or fall back.
Count tokens as well as requests, since a request with a 100,000-token prompt takes as much of the engine’s time as a hundred requests of a thousand tokens, or more. And when a client disconnects, abort its request in the engine, or the GPU keeps generating tokens that nobody reads.
Scaling. GPU utilization is the wrong signal for autoscaling: as the first chart showed, it says 100% for a single sequence. Scale on what users feel and on what limits the batch: requests waiting, KV cache usage, TTFT.
A new replica is slow to start. Llama 3.1 70B in bf16 is 141 GB; at 1 GB/s from network storage, reading it takes more than two minutes, before the engine has captured its CUDA graphs and warmed up.
Keep the weights close to the GPUs, keep a warm replica in reserve, and scale out when the queue starts to grow, not when it is already long.
What to watch. vLLM exports the essentials as Prometheus metrics[1]: vllm:num_requests_waiting and vllm:num_requests_running, vllm:kv_cache_usage_perc, vllm:num_preemptions, vllm:time_to_first_token_seconds, vllm:inter_token_latency_seconds, and vllm:prefix_cache_hits against vllm:prefix_cache_queries.
Watch TTFT and time per token separately, and at the 99th percentile as well as the median: a chunked-prefill budget that is too large shows up as a long tail in time per token while the median looks fine.
For every request, log the time in the queue, in prefill and in decoding, and the number of input and output tokens.
References
- vLLM: automatic prefix caching, preemption, metrics. ↩
- Leviathan et al. Fast Inference from Transformers via Speculative Decoding. ICML 2023. ↩
- Chen et al. Accelerating Large Language Model Decoding with Speculative Sampling. 2023. ↩
- nginx: proxy_buffering. ↩
- Kwon et al. Efficient Memory Management for Large Language Model Serving with PagedAttention. SOSP 2023.
- Yu et al. Orca: A Distributed Serving System for Transformer-Based Generative Models. OSDI 2022.
- Agrawal et al. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve. OSDI 2024.
- Zhong et al. DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving. OSDI 2024.
- Zheng et al. SGLang: Efficient Execution of Structured Language Model Programs. 2023.
- Shazeer. Fast Transformer Decoding: One Write-Head is All You Need. 2019.
- Ainslie et al. GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints. EMNLP 2023.
- DeepSeek-AI. DeepSeek-V2, 2024, and DeepSeek-V3 Technical Report, 2024.
- Frantar et al. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. ICLR 2023.
- Lin et al. AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration. MLSys 2024.
- Dettmers et al. LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale. NeurIPS 2022.
- Cai et al. Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads. 2024.
- Li et al. EAGLE: Speculative Sampling Requires Rethinking Feature Uncertainty. 2024.
- Dao et al. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. NeurIPS 2022.
- Dao et al. Flash-Decoding for long-context inference. 2023.
- Shoeybi et al. Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism. 2019.
- NVIDIA: nvidia-smi, DCGM profiling metrics, datasheets of the T4, A100 and H100.
- Anthropic: API pricing.
The measurements: experiment.py (Kaggle T4), speculative.py (CPU), and the figures, figures.py, with the data they were drawn from.